Picking between frontier AI models in 2026 isn't a two-horse race anymore. OpenAI, Anthropic, Google, xAI, Meta, Z.ai, and DeepSeek have all shipped new top-tier models in the past few months, and the price gap between them now runs to roughly 40 times on the same job.
That spread is the real story. The same heavy month of API use costs dozens of times more on one model here than on another, and the cheaper option isn't always the weaker pick for what you need.
This guide covers eight frontier models, using each company's own launch pages, docs, and pricing tables (as of November 2026). Benchmark scores are vendor-reported, so treat them as each company's best foot forward, not a neutral leaderboard.
You'll get what each model is, where it's strong, where it falls short, and what it costs, both in a monthly app plan and per token through the API. The order isn't a ranking. By the end, you should know which model fits your work and your budget.
1. GPT-6 Astra
Best for: Hard math, science, and long technical projects where accuracy beats speed.
GPT-6 Astra is OpenAI's flagship, and the company calls it state-of-the-art on computer use, browsing, software engineering, cybersecurity, science, and professional work in its launch post. OpenAI has since expanded the GPT-6 family with GPT-6 Sol and GPT-6 Luna, which it added on September 22.
The math numbers are the headline. OpenAI's own table puts Astra at 97.6% on FrontierMath Tier 4 and 96.0% on GPQA Diamond, two demanding reasoning tests (you can read more in Zeniteq's launch coverage of GPT-6 Astra as well).
Key features:
- Reasoning: Leads OpenAI's comparison on FrontierMath Tier 4, GPQA Diamond, and ARC-AGI-3
- Long tasks: In Codex, Astra can keep notes across context windows instead of repeatedly compressing them
- Access: ChatGPT Plus, Pro, Business, and Enterprise, plus the API as
gpt-6-astra - Clouds: Also served through Microsoft Azure and Amazon Bedrock
For a general user, Astra makes the most sense if you already pay for ChatGPT. It's included in the paid plans, so you don't have to touch an API at all. If you're doing science homework, research-heavy analysis, or a multi-step coding project, that's where OpenAI says it pulls ahead.
Here's what OpenAI charges through the API:
- Standard: $10 input / $50 output per 1M tokens
- Fast mode: About twice the speed at twice the standard price
The trade-offs are real. OpenAI rates Astra at the Critical threshold in cybersecurity under its own safety framework, so it refuses advanced security work like writing proof-of-concept exploits. Extra safety checks can also slow, pause, or stop legitimate tasks, and in the API the task simply stops.
It isn't the top scorer everywhere, either. OpenAI's own table shows Astra at 57.2% on Humanity's Last Exam with tools, behind Claude Fable 5.1 at 65.0%. And its per-token price puts it at the expensive end of this list, tied with Fable.
Before you commit, check whether your plan gives you Astra in the mode you'll actually use, since OpenAI says Enterprise admins have to switch Astra on for their workspace.
2. Claude Opus 5.5
Best for: Everyday coding, writing, and knowledge work at a price most people can justify.
Claude Opus 5.5 is Anthropic's newest model, and the company says it performs at the level of Claude Fable 5.1 on most work while costing about 40% less to run than Opus 5. That's a pretty bold claim for a model that's cheaper per token than its sibling.
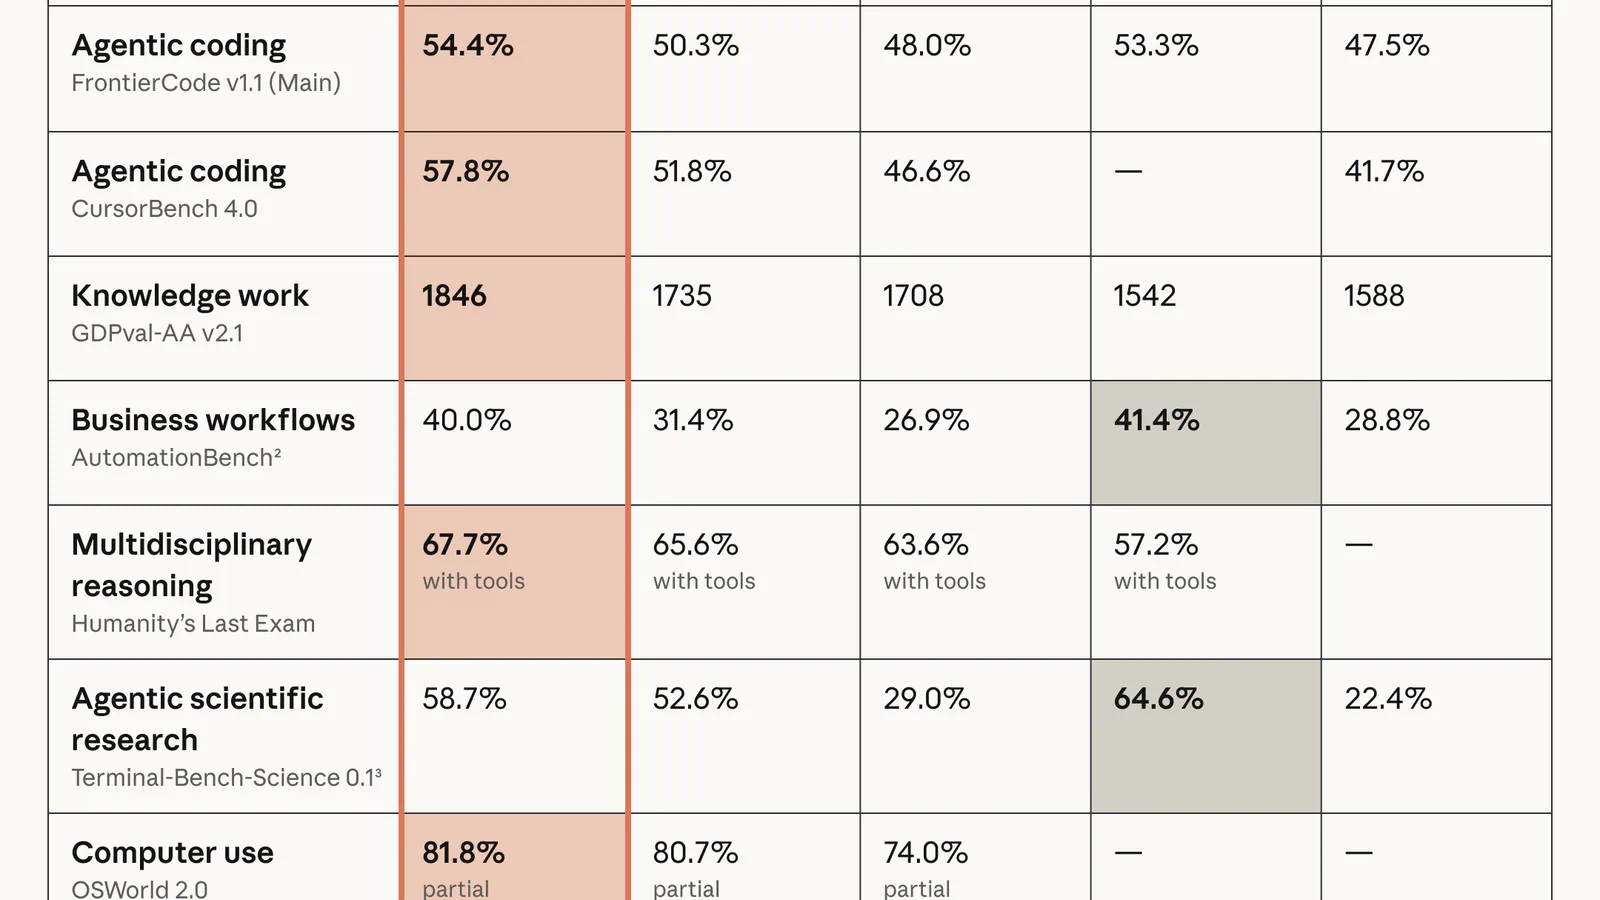
On Anthropic's published table, Opus 5.5 scores 66.4% on Terminal-Bench 4.0, ahead of GPT-6 Astra's 57.9%, and posts the top GDPval-AA score in that comparison. It doesn't sweep every row, though: Astra still edges it on AutomationBench and Terminal-Bench-Science.
Key features:
- Context: A 1M-token context window, enough for long contracts, codebases, or reports
- Speed option: A fast mode for when you'd rather wait less and pay more
- Plans: Available on Claude Pro, Max, Ultra, Team, and Enterprise
- Clouds: On the Claude Platform, Amazon Web Services, Google Cloud, and Microsoft's cloud
The price is the strongest argument. Anthropic lists Opus 5.5 at $4 per million input tokens and $20 per million output tokens, 20% below Opus 5, with cache reads 60% cheaper too. For a general user, the simpler path is a subscription:
- Claude Pro: $20 a month billed monthly, or $17 a month on the annual plan
- Max: $100 a month
- Ultra: $200 a month
- Fast mode (API): $8 input / $40 output per 1M tokens
The catch is mostly about safeguards. Opus 5.5 is the first Opus model to launch with Fable-class protections around cybersecurity, biology, and anti-distillation, so some security research and lab-science requests may get blocked or routed elsewhere. Anthropic's plan comparison doesn't include Opus on the free Claude plan, so you'll need at least Pro.
If you mostly write, analyze documents, or code inside an editor, try Opus 5.5 on Pro for a month before paying for anything bigger.
3. Claude Fable 5.1
Best for: Long, unattended projects that run for hours across several apps.
Claude Fable 5.1 is the model Anthropic positions above Opus. It shipped on September 1, and Anthropic calls it its most capable model for coding and knowledge work, built for jobs that take hours and span many applications.
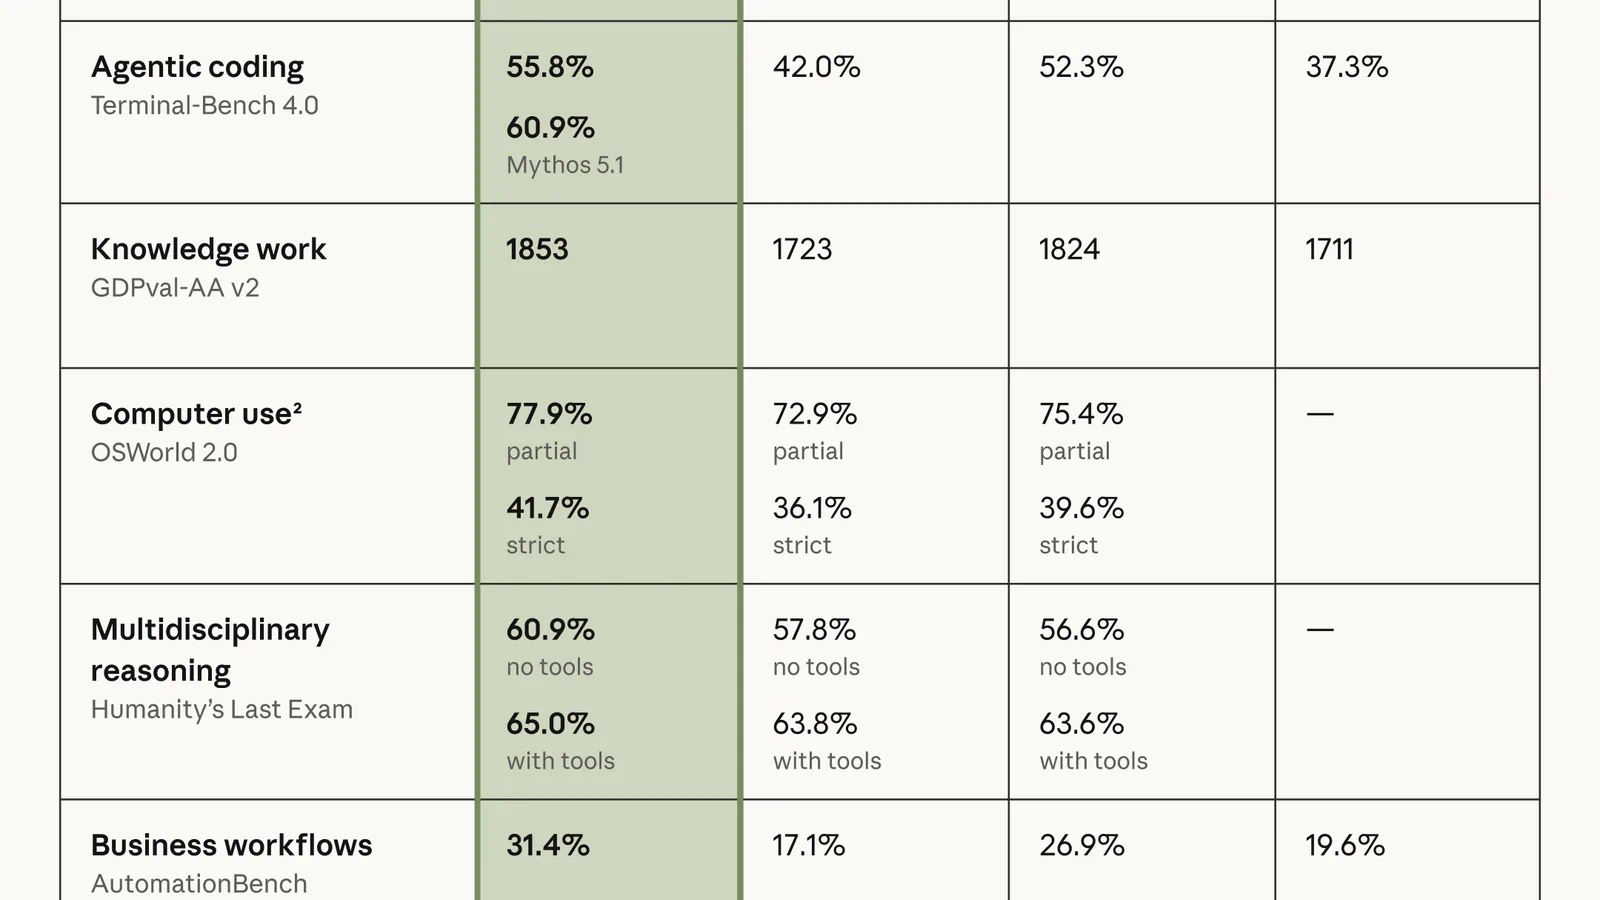
Think of it as the "go away and come back later" model. Anthropic's examples include working through a backlog in Cowork, picking up requests in Slack, operating a browser, and running unattended as a managed agent. Its benchmark table shows big jumps on science tasks: 52.6% on Terminal-Bench-Science, up from 24.7% for Fable 5.
Key features:
- Long-horizon work: Multi-day autonomous sessions and codebase-wide changes
- Research: Anthropic pitches it for scientific and deep-research work
- Plans: Pro, Max, Ultra, Team, and Enterprise
- Data location: US-only inference at 1.1 times the normal price
Here's how Fable is priced:
- API: $10 per million input tokens and $50 per million output tokens
- Cache reads: $0.25 per million tokens, 75% below Fable 5
- On Claude Pro: Fable is paid with usage credits rather than included
- On Max: Included, up to half your weekly limit
There are three trade-offs worth knowing. Using Fable requires 30-day data retention for safety monitoring by default, which some businesses won't accept. Requests flagged in sensitive areas get automatically routed to less capable models (you're not charged Fable prices when that happens). And since Anthropic itself says Opus 5.5 matches Fable on most work, Fable's extra cost only pays off on the longest, hardest jobs.
Unless your tasks routinely run for hours, start on Opus 5.5 and move up only when it stalls.
4. Gemini 4 Argon
Best for: Professional work in finance, legal, and science, and anyone who already pays for Google AI.
Gemini 4 Argon is Google's flagship, and as of October 13 it's globally available for developers and in the Gemini app for Google AI Pro and Ultra subscribers, so anyone on a paid plan or the paid API tier can use it now.
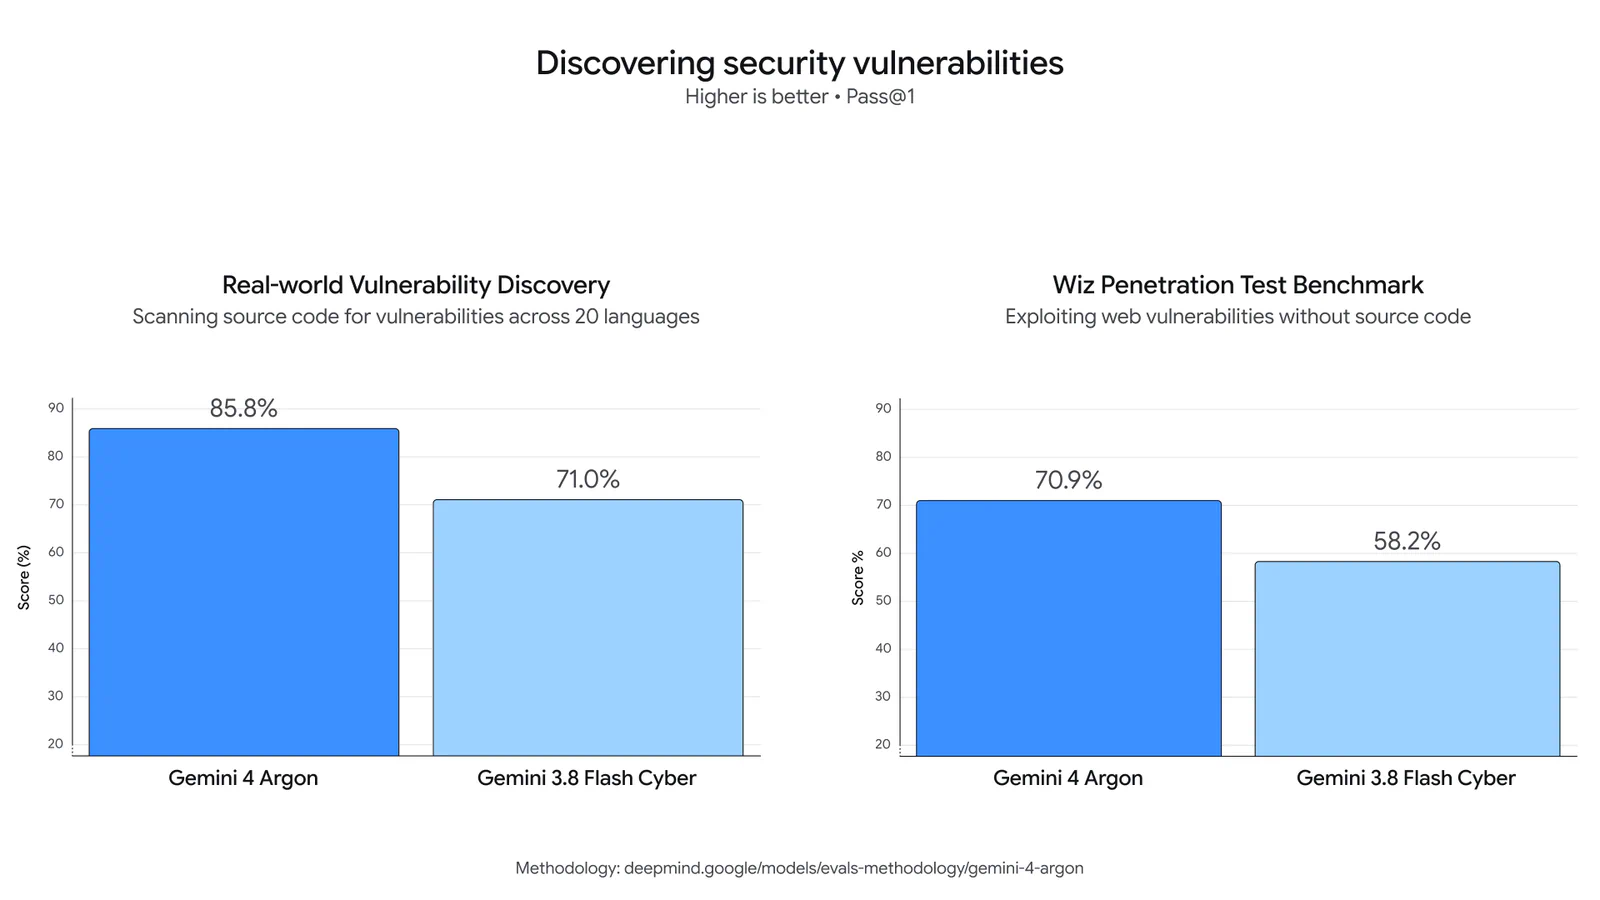
Google says Argon ranks #1 on the Vals Index, which tests models on finance, coding, legal, and tax work. It also claims a top 87% score on the ERQA embodied-reasoning test and major gains in spatial reasoning, math precision, and visual coding over earlier Gemini models.
Key features:
- Huge output: A 1M unified input-output token limit, so it can write very long documents in one go
- App access: Gemini app and AI Mode in Search for AI Pro and Ultra subscribers
- Prompt-injection resistance: Google says attack success fell to 0.7% on the Gray Swan benchmark
- Agent safety: Trained to pause for confirmation before irreversible steps
For developers, Argon is a bargain right now, but only for a few more weeks. Google's introductory API price is $2 per million input tokens and $10 per million output tokens, with cached input 95% off. After November 30, 2026, it doubles to $4 input and $20 output.
That deadline is the main thing to plan around. If you build a budget on the intro price, your bill doubles in December. Some access is also tiered: Google lists Antigravity (its coding environment) for AI Ultra subscribers, and cyber defenders who want Argon without guardrails have to apply to a separate program.
For most people, the question is simple: if you already pay for Google AI Pro, you've got Argon in the Gemini app, and you can see how it handles your work before spending more. Read how Google took Argon global at half-price API rates for the launch details.
5. Grok 4.7
Best for: Coding and knowledge work where price matters as much as raw scores.
Grok 4.7 is the newest flagship from xAI, which now brands itself SpaceXSI. The company calls it its most capable model for coding and knowledge work, built on a new, larger base model than Grok 4.6 and trained to check its own work more carefully.
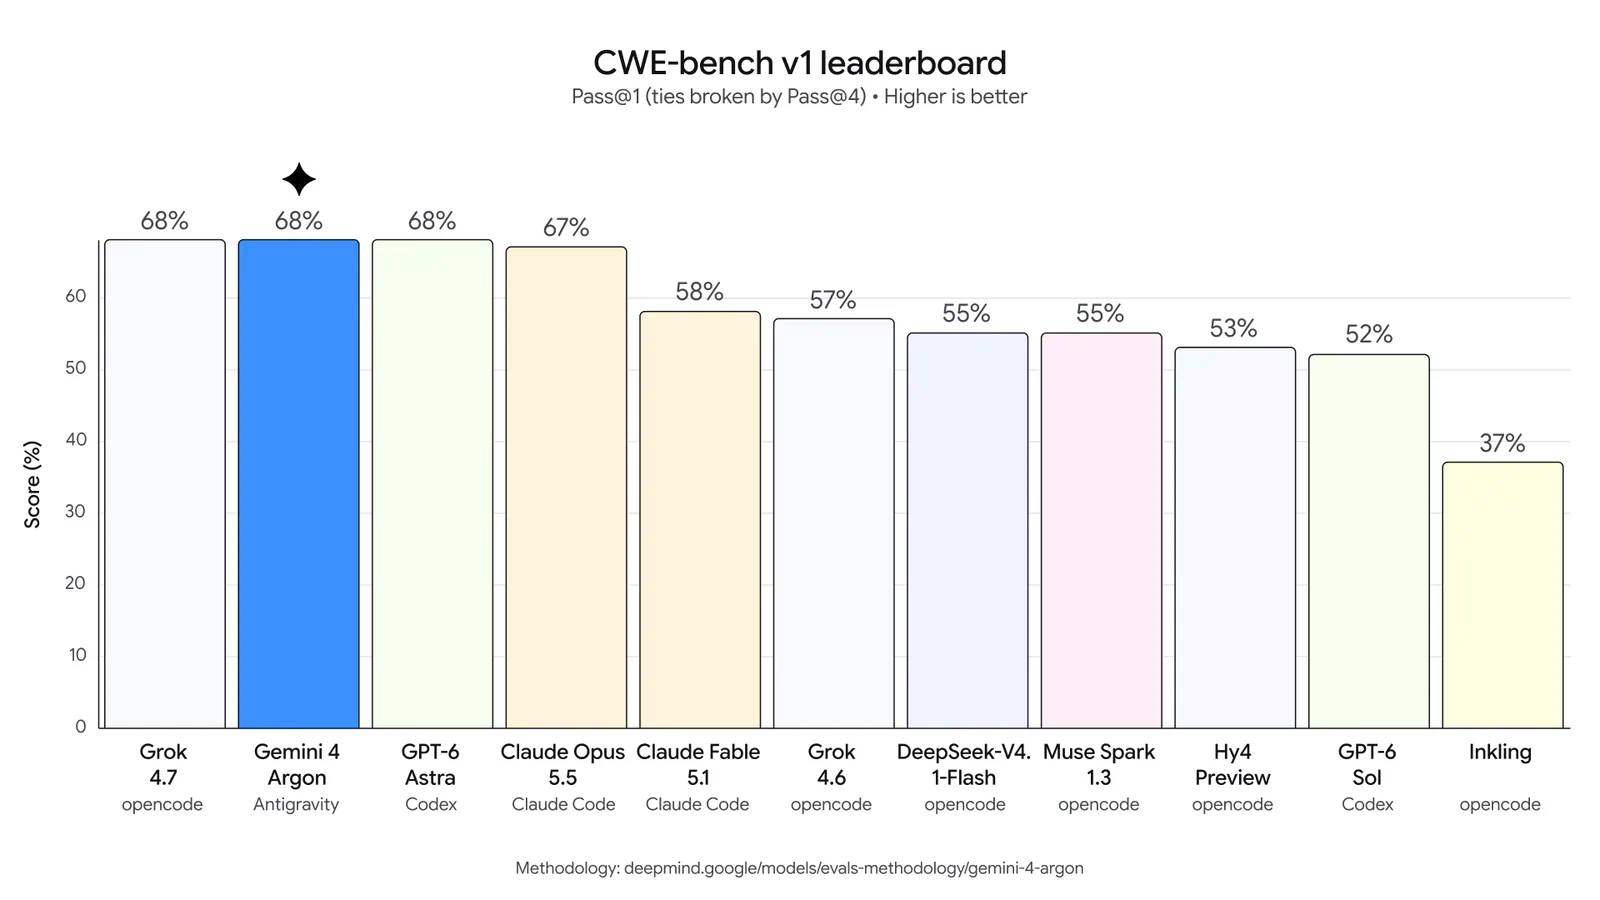
The pitch is value. xAI says Grok 4.7 is "at the frontier in price-performance" on CursorBench 4.0, a test of longer-running coding tasks, and it serves the model at the same price and speed as Grok 4.6. On xAI's own table it also scores 19.6% on the Harvey Legal Agent benchmark, well ahead of the other models listed there.
Key features:
- Self-checking: Better at verifying its own work and managing longer context, according to xAI
- Where it runs: Cursor, Grok Build, the Grok API, third-party coding tools, and model routers
- Fast variant: Twice the output speed at twice the price
- Safeguards: Advanced cyber capabilities are invite-only for select security partners
Here's what xAI charges through the API:
- Standard: $2 input / $6 output per 1M tokens
- Fast variant: About double that
That's a fifth of Astra's input price and an eighth of its output price. The trade-off shows up on the hardest coding tests. On xAI's own table, Grok 4.7 scores 46.3% on CursorBench 4.0 against 51.8% for Claude Fable 5.1, and 37.6% on Terminal-Bench 4.0, well short of the Claude models.
Also note where it's offered. xAI's announcement points to Cursor, Grok Build, and the API, and doesn't mention the Grok chat app, so check your Grok plan's model list before assuming you'll get 4.7 there.
6. Muse Spark 1.3
Best for: High-volume work where a low cost per task beats top-tier scores.
Muse Spark 1.3 is Meta's model for agentic and coding work at scale. Meta's docs describe it as the lower-cost option for high-volume, latency-sensitive work, and Meta pairs it with its other model, Muse Wonder (the docs even suggest running Spark as a sub-agent under a Wonder main loop).
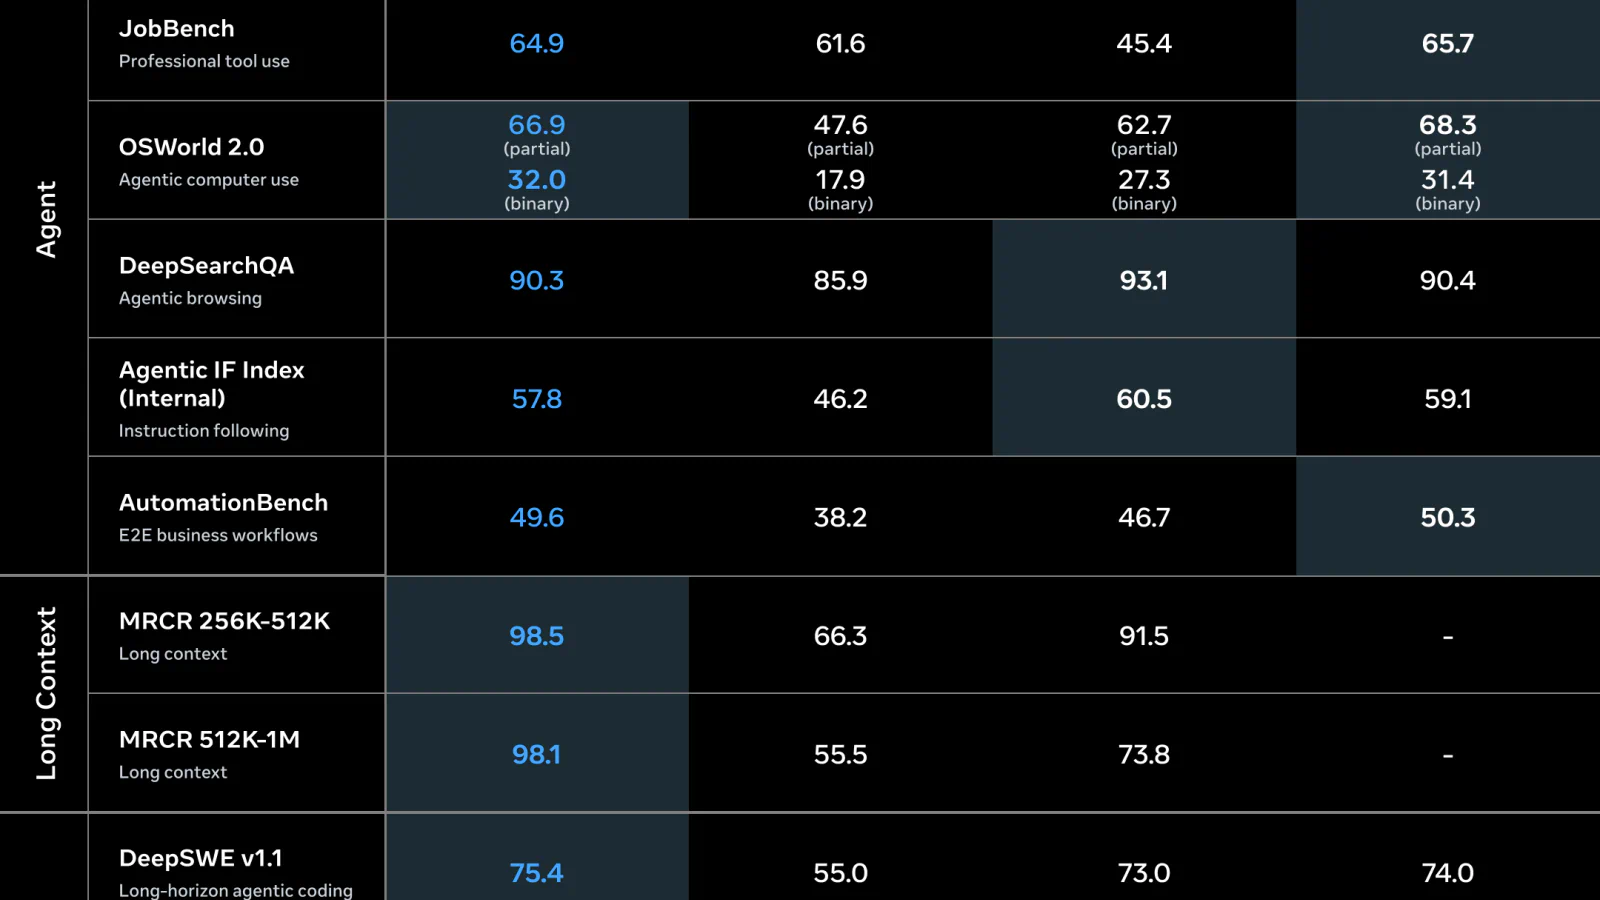
One correction to a common claim: Muse Spark 1.3 isn't open-weight. Meta offers it through its Model API and Muse Code. Meta's docs list a separate model, Muse Spark Open, under open-weight models.
Key features:
- Inputs: Text, image, video, audio, and PDF in, text out
- Context: A 1,048,576-token window
- Reasoning effort: Adjustable from "minimal" to "max"
- Contributor mode: Much cheaper tokens if you let Meta train on your content
Here's where Muse Spark gets interesting for budget-minded users. Meta lists Muse Spark at $1.25 per million input tokens and $4.25 per million output tokens in Standard mode:
- Standard: $1.25 input / $4.25 output per 1M tokens, with cached input at $0.15
- Contributor: $0.10 input / $0.20 output, in exchange for training rights on your content
- No long-context premium: A full context window costs the same per token as an empty one
- Web search grounding: $2.50 per 1,000 queries
Contributor mode is the trade-off to think hardest about. The discount is huge, but you're giving Meta permission to use your prompts to train future models, which rules it out for client work or anything confidential. Max reasoning effort also isn't available in Contributor mode.
Frequently Asked Questions
5 questions
1What is a frontier AI model?
A frontier AI model is a general-purpose model at the current state of the art, the most capable systems available at a given time. The group changes quickly, and every model on this list launched within the past few months.