A drone software company in Gothenburg couldn’t test its own map. Airpelago builds traffic management and autonomous flight software for drone operations, including inspection flights along power lines for utility companies. The map is the center of the product. Operators plan inspection routes on it, monitor flights on it, and export reports from it.
By mid-2025, their Playwright suite was failing differently on every run. The interactive map widgets resisted selector-based scripts almost completely, and every red build told the team more about their test code than about their product.
Most teams treat this kind of failure as a chore. You rerun the pipeline, the checks go green, and everyone moves on. The information content of the failure is zero, and everybody knows it.
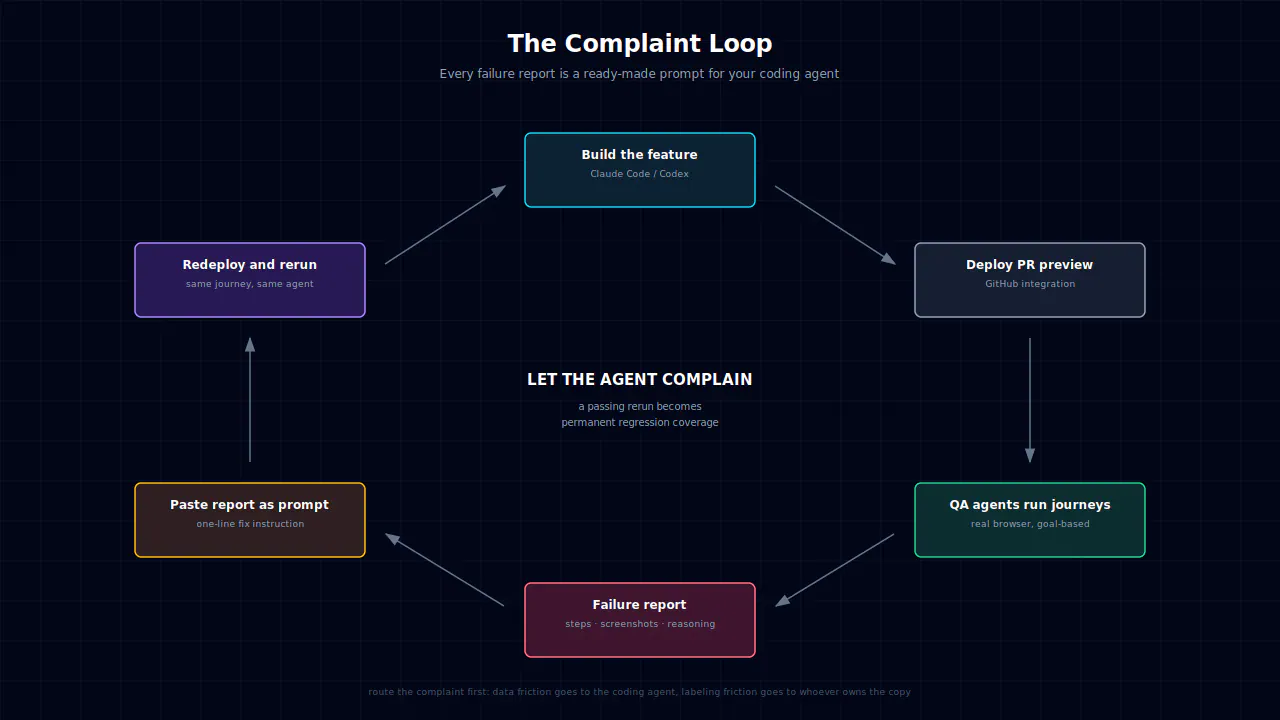
But what if the failures were the useful part? What if the struggle of the thing doing the testing, every retry, every hesitation, every abandoned attempt, was product data you could act on before your code even merges?
That idea has a name in this article: friction as telemetry.
Agentic QA, which is testing where an AI agent works toward a user goal instead of executing a script, is what makes it practical, and Airpelago’s story shows what it looks like when it works.
What “Friction as Telemetry” Means
Telemetry usually means the data your app emits about itself: logs, metrics, traces, crash reports. Friction as telemetry extends the same idea to the testing layer. The effort an automated tester spends fighting your app is itself a measurement of the product.
For that measurement to mean anything, you have to separate two kinds of test friction.
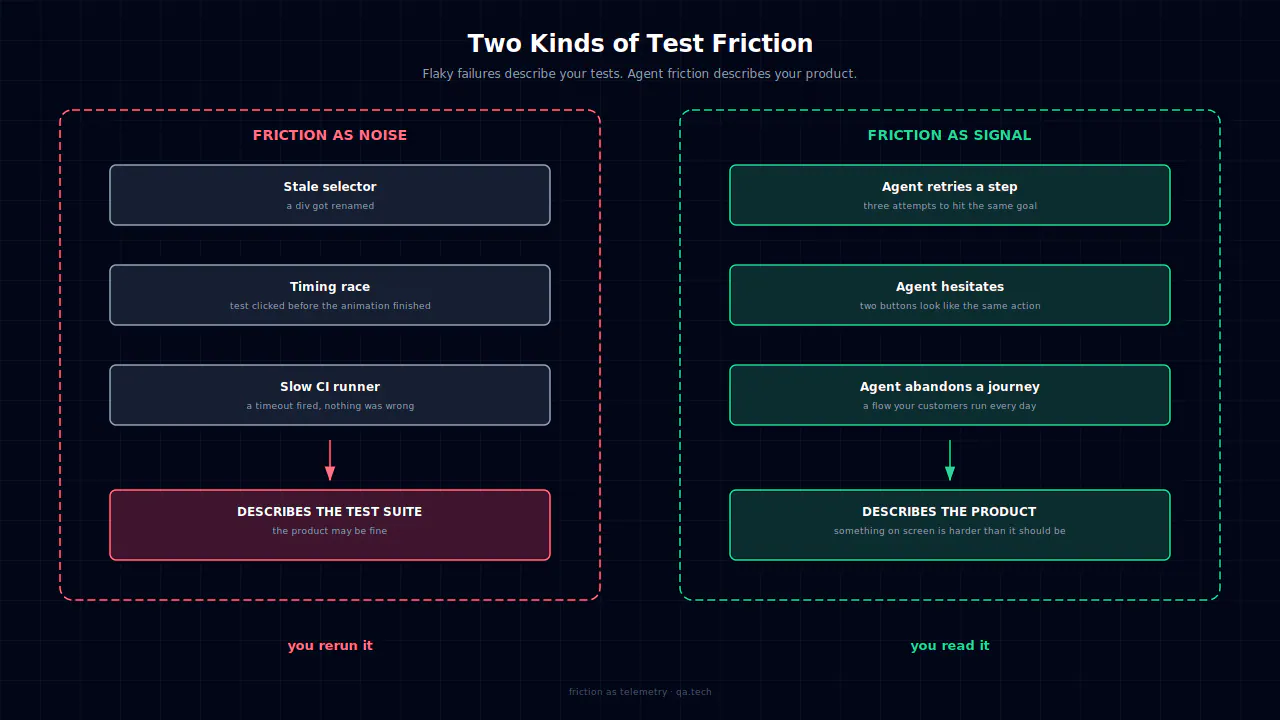
The first kind is noise. A selector broke because a div got renamed. A test raced ahead of an animation and clicked too early. A CI container ran slower than usual and a timeout fired.
These failures describe the test suite. The product may be perfectly fine.
Teams learn to distrust these failures, which is how a red build turns into something you rerun instead of something you read.
The second kind is signal. A QA agent doesn’t follow a script of selectors. This is the core difference between agentic QA and script-based regression testing: the agent works toward a goal the way a user would — read the screen, find the next step, act, check the result.
When an agent retries a step three times, hesitates between two similar buttons, or gives up on a journey your customers complete every day, the friction is coming from the product. Something on the screen is harder than it should be, or the app returned a result that doesn’t match the request.
Traditional script-based frameworks like Playwright and Cypress can’t make this distinction because their failures are dominated by noise. Agentic QA platforms flip the ratio. QA.tech agents adapt when your UI changes, so the failures that survive are mostly about your app rather than your tooling. Once the noise drops, the complaints become worth listening to.
One clarification before the case study, because ‘are AI test automation tools reliable?’ is a fair question: I’m not claiming agents never produce noise. They do, especially early on while they’re still learning your product. The claim is narrower: the ratio of signal to noise is high enough that reading failures becomes a better use of time than rerunning them.
Here’s a quick test you can apply to your own suite:
Pick your last ten red builds and ask, for each one, whether the failure taught you anything about your product. If the honest answer is two out of ten, your failures are noise and nobody should feel bad about ignoring them. The goal of everything that follows is to push that number up until ignoring a failure feels reckless.
Testing the Impossible: Map-Based Interfaces
Airpelago is a Swedish company of under 50 people building software for drone operations. By mid-2025, the platform was growing quickly, and the team wanted to onboard more external users: customers, partners, and drone operators. Quality problems in production were making that expansion risky.
According to QA.tech’s case study on the company, the team tried to expand its end-to-end coverage internally and hit a wall. Their Playwright setup struggled with flakiness, and the interactive map at the heart of the product resisted automation entirely.
Tobias Fridén, Airpelago’s CTO and co-founder, put it this way:
“Testing the map-based interfaces was almost impossible. Every interaction was flaky.”
Think about what that means in friction terms. The team saw failures constantly, but the failures carried no information. A red run on Monday meant a stale selector. A red run on Tuesday meant a timing bug.
None of it said anything about whether an operator could actually plan an inspection route and export the report a utility client was waiting for.
In June 2025, Airpelago adopted QA.tech and started by defining their 20 main test cases. Everything from planning a drone inspection route to exporting reports for utility clients got written down as a goal, in plain language, rather than as a script.
The agents run those journeys in a real browser as a goal-driven testing platform rather than a selector script, which is what finally made the map testable. Because the agents are framework-agnostic, there was nothing to migrate — no Playwright config to port, no selectors to rewrite.
An agent doesn’t need a DOM ID to drag a route marker. It sees the widget on screen and interacts with it the way an operator would. The E2E suite now runs alongside Airpelago’s unit and integration tests, so the coverage spans every layer instead of stopping where the selectors ran out.
The GitHub PR integration runs the full suite whenever a commit message contains the keyword ‘E2E’, so developers decide when the heavy tests matter. Tobias called that flexibility valuable because nobody wants a 20-test-case browser suite blocking every commit. If you’re comparing AI-driven QA tools for CI pipelines, that flexibility is the detail worth checking.
Airpelago now runs their QA.tech suite multiple times per day. Tobias describes the change bluntly: the team used to tiptoe into every release, and now they ship without hesitating. For a company whose customers fly physical drones based on what the software tells them, that confidence is worth more than any individual feature.
Notice what changed and what didn’t. The app still has bugs. Tests still fail.
What changed is that a failure now points somewhere. When a test case breaks, it breaks because the product changed, and the report says where.
What Changes When the Failure Is Trustworthy
When a flaky suite fails, you rerun it. When an agent fails, you read it.
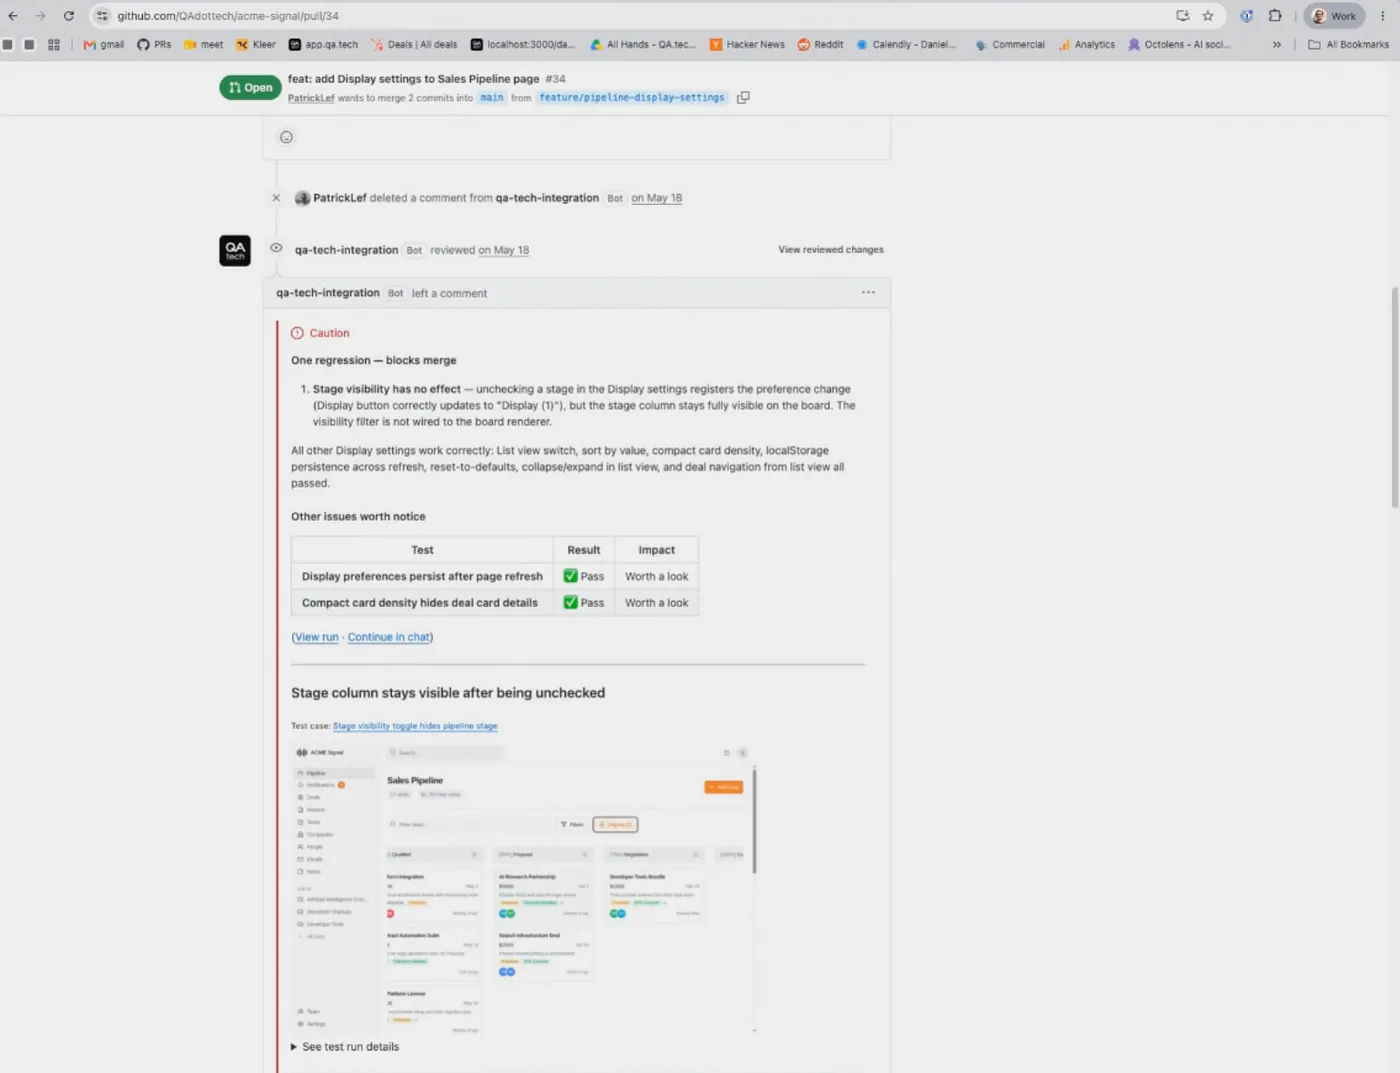
That habit change sounds small, but it rewires the whole feedback loop. QA.tech attaches screenshots, logs, and network activity to every step of a run, plus the agent’s own reasoning at the point of failure.
A failed test stops being a red icon in CI and becomes a narrated bug report. Here’s the goal I was given, here’s what I saw, here’s the step where the product stopped cooperating.
Reproduction steps are usually the most expensive part of any bug. Someone has to notice the problem, figure out how to trigger it again, and write the steps down before anyone can start fixing. An agent produces that artifact as a side effect of failing. The cost of reproduction drops to the cost of reading.
Timing matters just as much as detail. These reports show up on the pull request, against a preview deployment, before the code merges. The PR check is only the surface, though. The full run history, every step, screenshot, and network trace, lives in QA.tech’s dashboard, where the whole team can inspect it. That’s how Airpelago works day to day: the commit keyword triggers the run, and the detailed results sit in the platform instead of getting buried in CI logs.
Compare that with your other options. Session recordings and heatmaps tell you users struggled after launch. Support tickets tell you weeks later, filtered through a frustrated customer’s memory. Friction telemetry arrives while the diff is still open and the developer still has the context loaded in their head.
Teams building AI products lean on this hard because their code output has exploded and human review can’t keep pace with it. If you want to see what per-PR agent testing looks like at a company shipping at that speed, QA.tech’s recent webinar includes a segment on how companies like Lovable run tests on every pull request. The timestamped link drops you right at that section.
Every failure you read and fix becomes a journey the agent keeps testing — dynamic regression coverage that grows with the product, so the report you acted on in March is still guarding that flow in November.
Flaky suites work in the opposite direction. Each ignored red build trains the team to ignore the next one, until the suite is technically running and practically decorative. I’ve watched that decay happen on more than one project, and the turning point is always the same: the day someone reruns a failure without reading it.
The practical rule I’d take from all of this: treat a trusted failure as the start of work rather than an interruption of it.
A Short Taxonomy of Agent Complaints
Not every complaint means the same thing. After reading enough agent test reports, the failures sort into four buckets, and each bucket points at a different kind of fix.
- Navigation friction: The agent can’t find a path to its goal. It wanders through menus, backtracks, or completes the task through a route you never intended. This usually means a flow changed and nothing announces it, or an important action sits buried three screens deep. The fix lives in information architecture, not code.
- Labeling friction: The agent hesitates between two similar buttons, or picks the wrong one. If a goal-driven agent reading your UI can’t tell “Save” from “Apply,” a rushed human on a Friday afternoon can’t either. The fix is copy and visual hierarchy.
- State friction: The agent acts before the app is ready, or gets stuck waiting for a state that never resolves. Spinners that spin forever, half-loaded views, buttons that silently do nothing during loading. Scripted tests paper over these with hardcoded waits, which is exactly why the bugs survive. The fix is loading and error states.
Sources
- Airpelagoairpelago.com
- Playwrightplaywright.dev
- Agentic QAqa.tech
- QA.techqa.tech
- According toqa.techhttps
- end-to-end coverageqa.tech
- https://vimeo.com/1208685282?fl=pl&fe=vlvimeo.com
- pull requestqa.tech