World models have become the thing every big AI lab wants to crack. In the past several months alone, Google DeepMind shipped Genie 3, which generates playable 3D environments at 24 frames per second and now runs as a prototype app for Google AI Ultra subscribers. NVIDIA is pushing Cosmos for robotics, Runway built GWM-1 around interactive video, and Yann LeCun left Meta to start a company dedicated entirely to the idea.
All of these models chase the same goal. Rather than predicting the next word in a sentence, they predict how a scene changes over time when you act inside it. Get that right, and you have a simulator for anything, whether that’s a game level, a robot training ground, or a film set.
Spend ten minutes with any of them, though, and you run into the same problems. Textures smear, dropped frames, and way too much lag. Sessions cap out after a few seconds. You also can’t download or run most of them yourself because the weights sit behind an API or a waitlist.
On July 9, Robbyant, Ant Group’s robotics subsidiary, released something that takes a direct shot at those problems. LingBot-World 2.0 is a world model that remains stable for a full hour of continuous generation at 720p and 60 fps, and it’s open source.
I read the technical report and spent time inside the live demo, and I’ll walk you through both in this article.
What’s New in LingBot-World 2.0?
If this is your first time hearing about LingBot-World, it is an interactive world model. You give it a starting image or a text prompt, and instead of producing a fixed video clip, it generates the world frame by frame as you move through it.
Press W and the camera walks forward. Swing a sword and the model has to figure out what happens next. Think of it as a video game with no game engine underneath, just a neural network guessing the next frame based on your input.
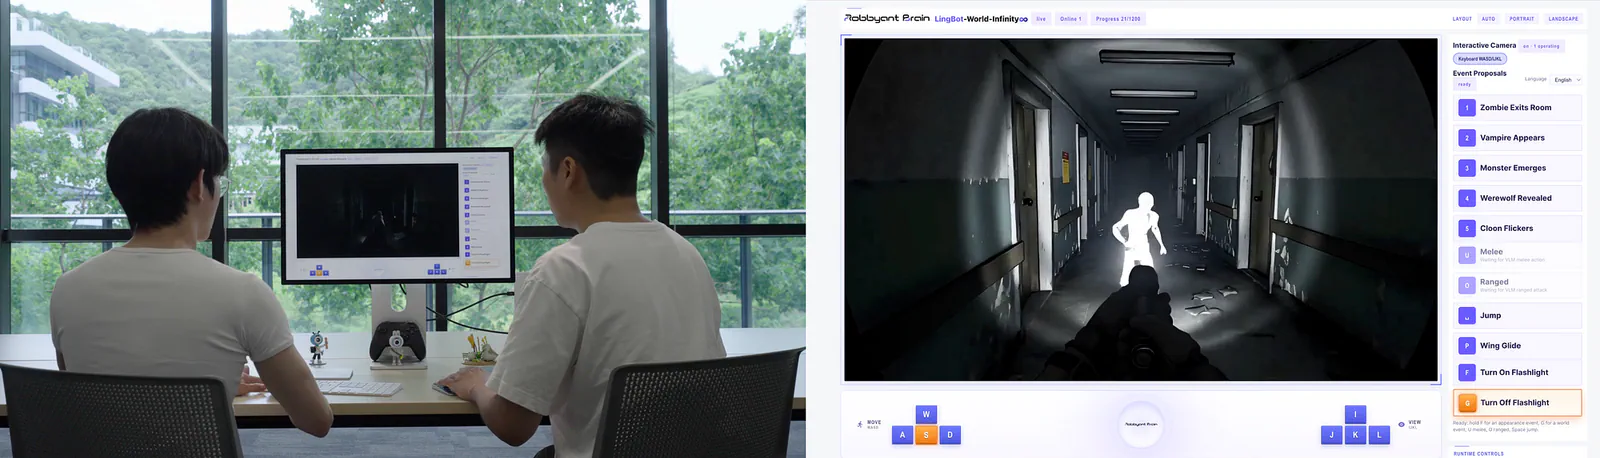
One user can navigate as the player, while another acts as a director, guiding actions, events, or high-level intent.
The first version could hold a scene together for a few minutes before quality drops. Version 2.0, which the paper calls LingBot-World-Infinity, makes a much bigger swing.
The technical report lists four core upgrades.
- An unbounded interaction horizon: The world keeps generating indefinitely without quality drift, verified through an hour-long uninterrupted session.
- Real-time 720p at 60fps: A distilled fast variant streams frames as they’re generated, so you never wait for a full sequence to render.
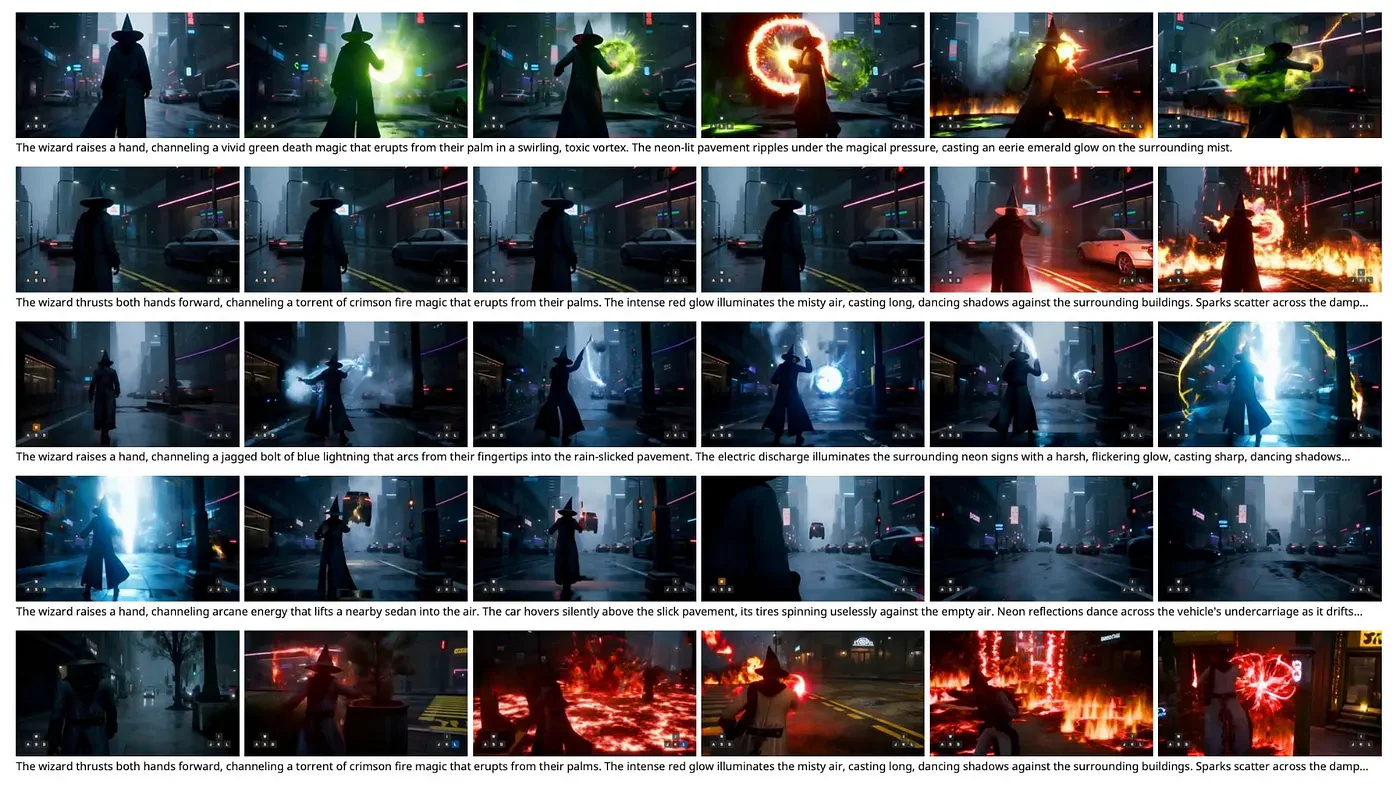
- A wider action space: Beyond walking and looking around, characters can attack, shoot arrows, cast spells, and fire ranged weapons, plus text-driven events like weather changes and entity spawning.
- An agentic harness: Two agents run alongside the generator to keep the world alive, which I’ll unpack below because it’s the part I find most interesting.
Beyond those four, the paper adds a multiplayer interface where several people share the same generated world, and pairs the 14B model with a lightweight 1.3B counterpart built to run on a single GPU. Only the 14B fast variant has shipped so far.
The paper’s comparison table lines it up against Matrix-Game 3.0, DreamX-World, HappyOyster, Genie 3, and its own predecessor. It’s the only model in that group claiming hour-level generation while staying real-time, semantically interactive, and fully open.
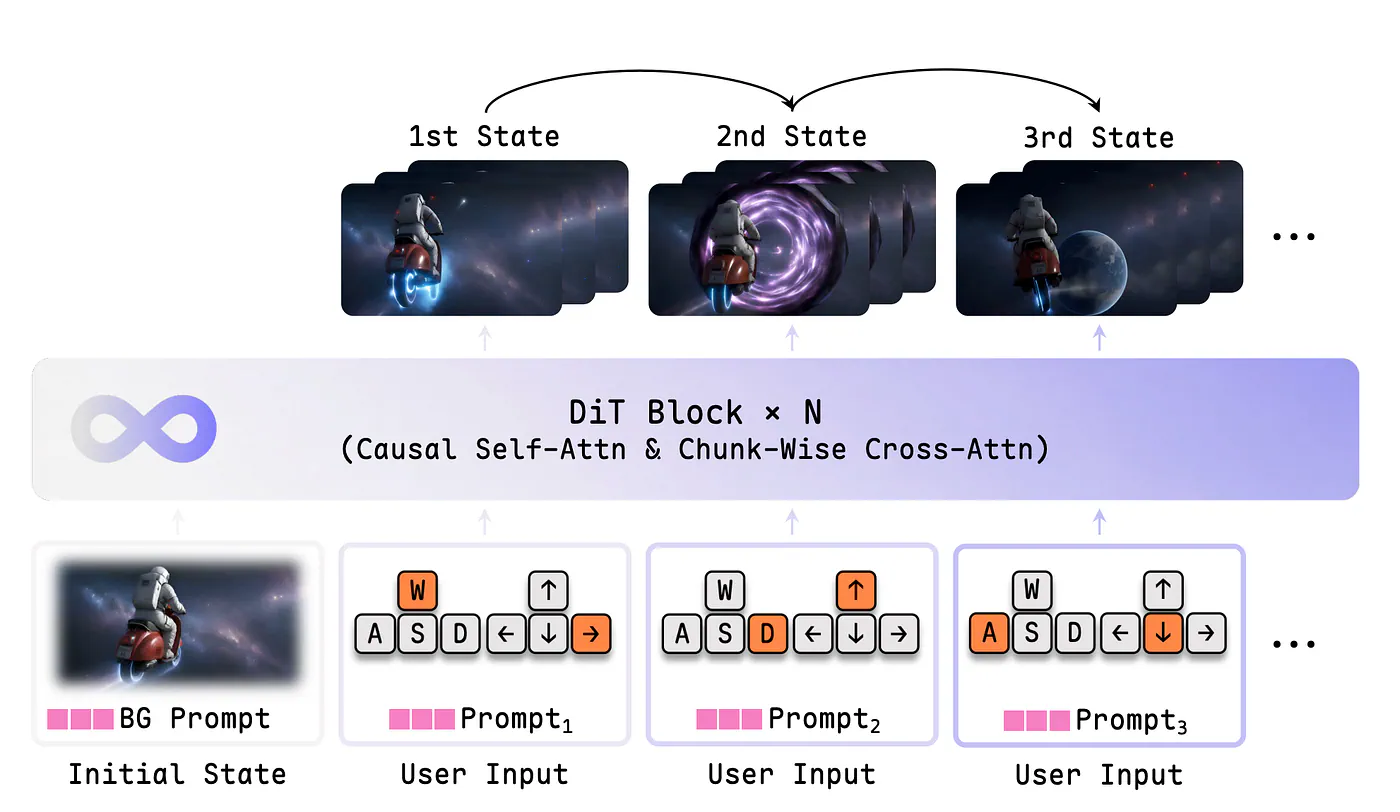
Overview of LingBot-World-Infinity Pipeline. An interactive world simulator is implemented as a causal video model. Our Infinity World is initialized from an initial image and its background description.
The training data mixes three sources, and each covers a weakness of the others.
- Egocentric videos supply real first-person interactions
- Synthetic clips from games and Unreal Engine carry precise action signals like jumping and driving
- Web videos add open-domain variety
Each clip also gets chunk-wise captions on top of a single global one, so the model learns to follow instructions that change mid-session.
How it stays stable for an hour
The core problem with long-horizon video generation is compounding error. Each frame becomes context for the next, so tiny mistakes pile up until textures smear and geometry warps. This is why most world models fall apart within minutes.
The fix starts with a strictly causal design. Each frame is generated only from past frames and the inputs received up to that moment, never from anything ahead of it. The method section even opens with a David Hume quote, “the cause must be prior to the effect.”
Mixture of Bidirectional (MoBA) and Autoregressive Attention Mask handles a subtler failure. In standard teacher forcing, the model leans on its growing context instead of learning to predict, which ends in visual decay. MoBA adds a bidirectional attention block to the mask as a regularizer against exactly that.
Training then runs in two stages.
- Pre-training produces a stable but slow model
- Post-training distills it into a few-step generator using consistency distillation plus distribution matching distillation on the model’s own long rollouts
It practices correcting the exact drift it will produce in deployment.
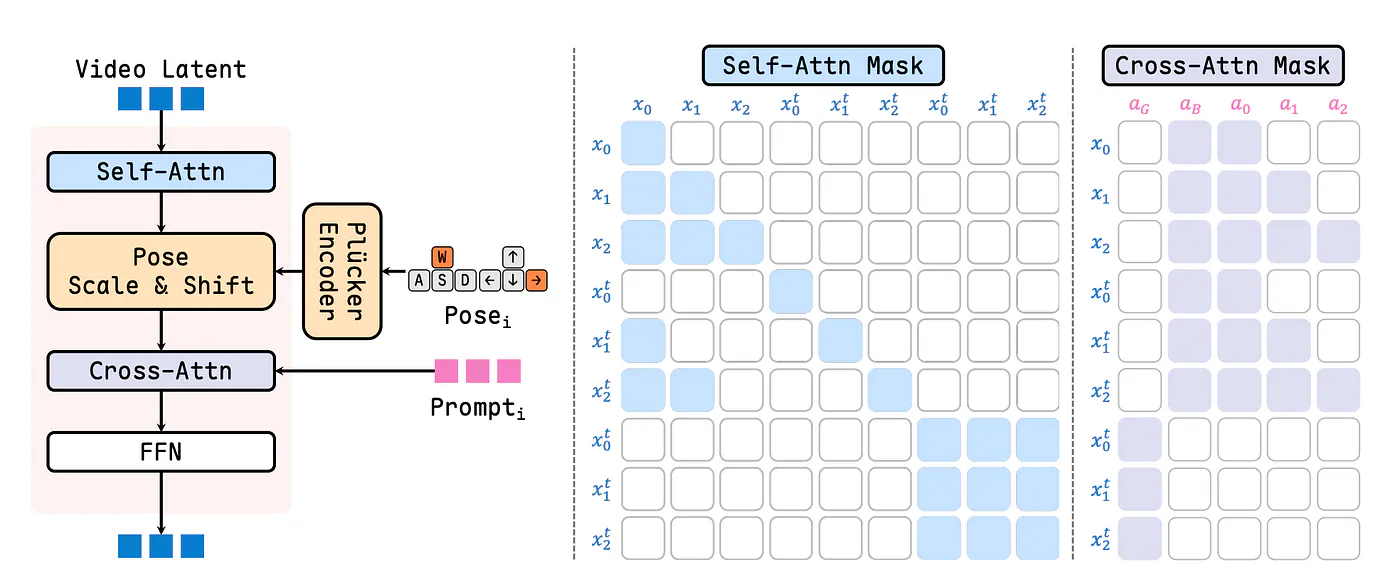
Overview of LingBot-World-Infinity DiT Block and MoBA Attention Mask. The action comprises camera poses and chunk-wise prompts, injected into the DiT block to enable user interaction.
The proof is the stress test. The team ran a single uninterrupted 60-minute session covering 20 different scenarios, opening in a bamboo canal town and ending with an orbital view of Earth at the 59-minute mark. The paper reports no perceptible quality decay across the entire run.
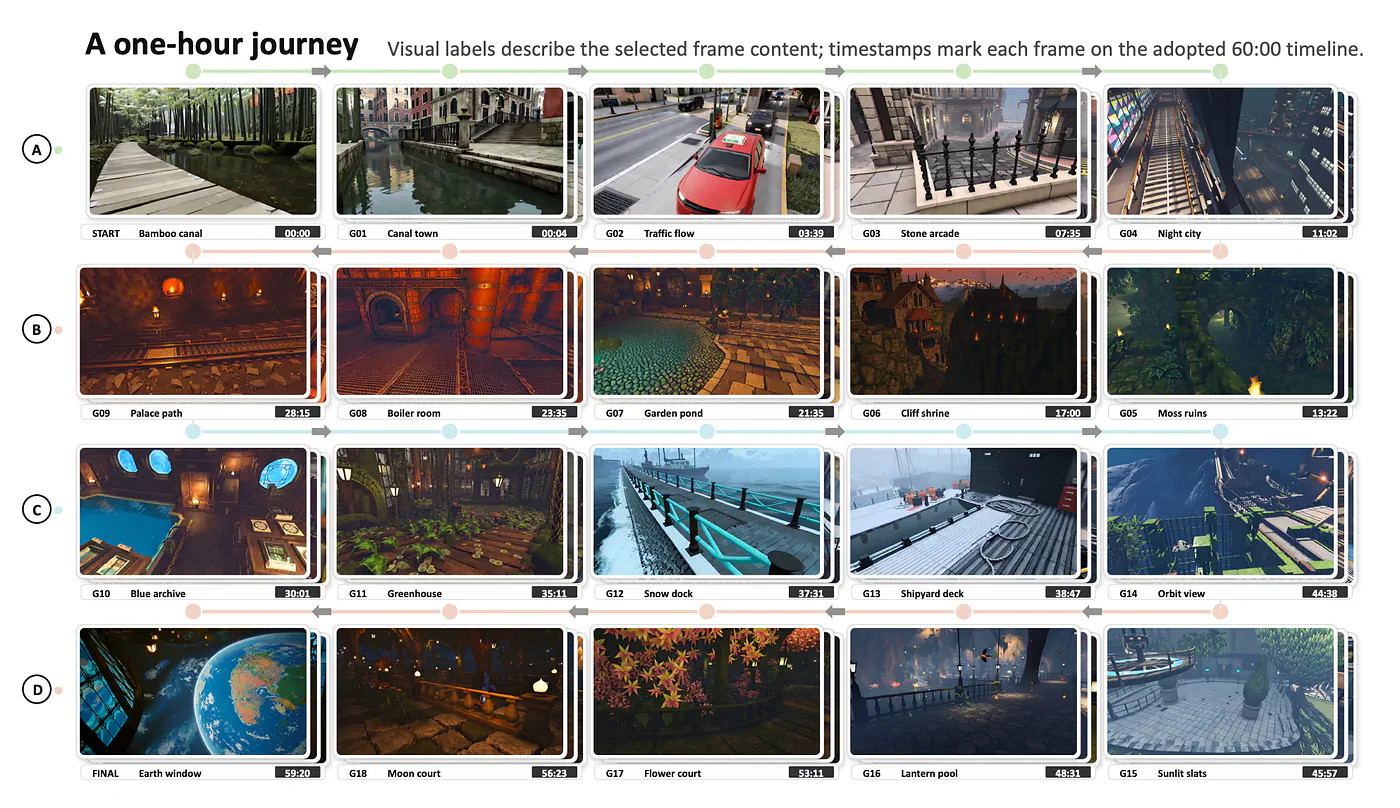
Hour-long world rollout. The researchers sample frames from a single 60-minute generated session, covering 20 distinct scenarios.
The authors also admit a real limitation here, and I respect them for stating it plainly.
The model doesn’t truly remember places that leave its context window. Walk far enough away and return much later, and that region gets regenerated rather than recalled, so the world is persistent in appearance but not in identity.
The dual-agent mechanism
Robbyant says this is a first for world models. LingBot-World 2.0 ships with two agents wired into the generation loop.
The harness pairs two systems with very different jobs.
- The Director is a vision-language model. It reads the current scene, reasons about what should logically happen next, and writes explicit event proposals.
- The Pilot is the video generator itself. It takes those proposals and grounds them into physically consistent frames.
The paper describes the split as a brain and a cerebellum. One handles semantic rules and causal reasoning, the other handles low-level physical dynamics and rendering.
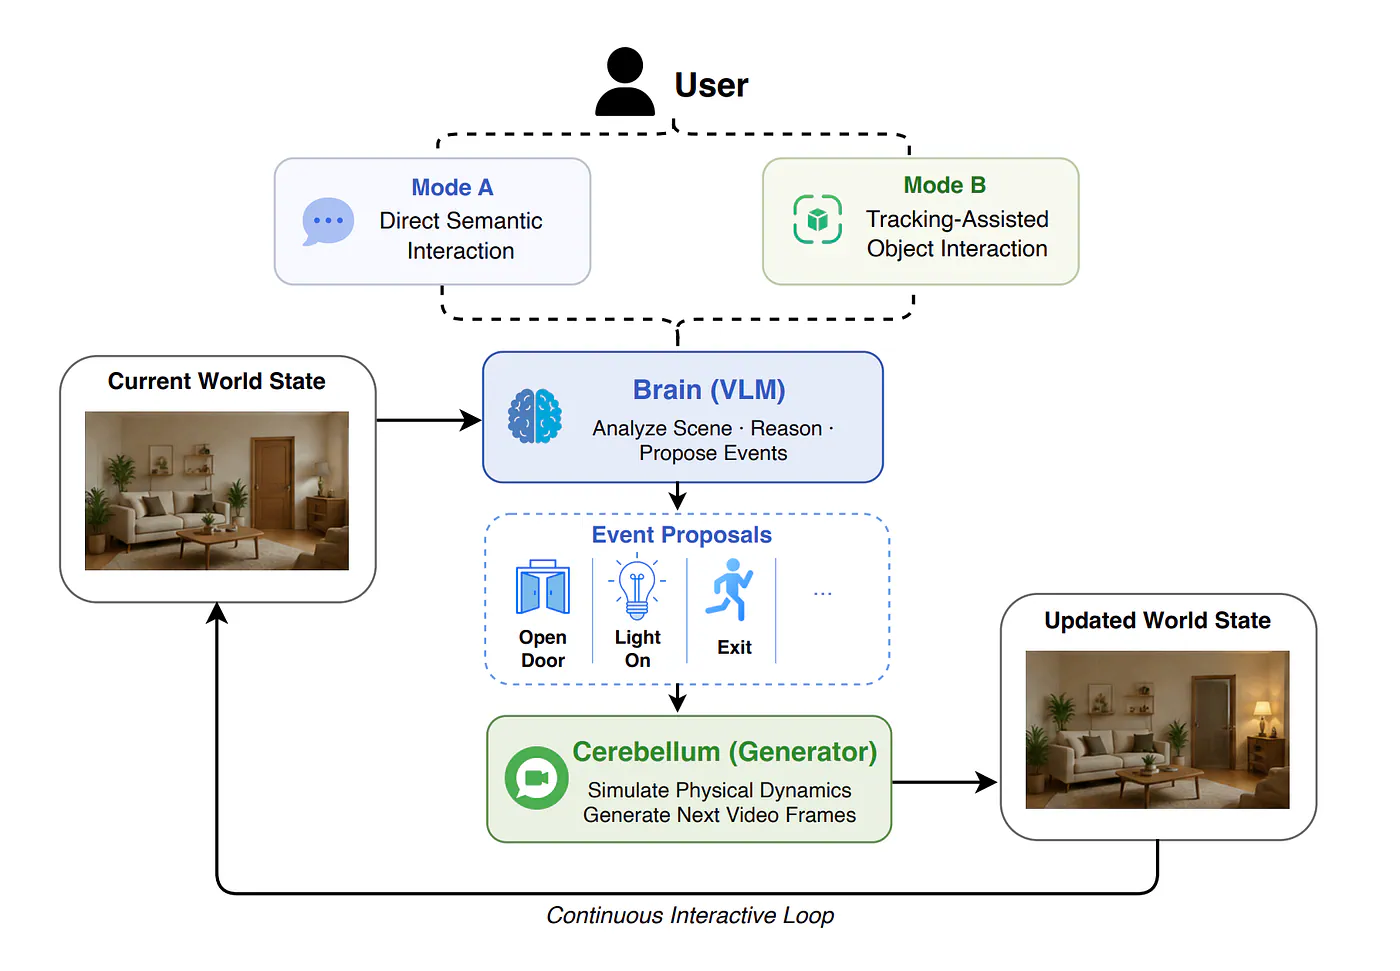
Overview of the Agentic Interaction Harness. Users can either interact with the existing world through semantic or object-centric actions, or intervene by introducing high-level textual events.
The result is a world that doesn’t just sit there waiting for your keystrokes. Things happen. The environment evolves whether you act or not, which is the difference between a video you can steer and a place that feels inhabited. Robbyant describes this as moving generated worlds from “watchable and controllable” to sustainably interactive, and after trying the demo, that framing tracks.
Real-Time Exploration of Infinite Worlds
Reading a paper only gets you so far. I wanted to know how it feels to actually play, so I loaded the free demo on Reactor and recorded my session. You can watch the video below.
It only lasts a couple of seconds because that’s how long the demo version lets you use it. For longer videos, please check the project page. Let me share a longer example with more dynamic movements.
The graphics are incredibly detailed and vibrant, which I did not expect from a model generating every pixel on the fly. Light bounces off surfaces convincingly, and distant objects hold their shape as you approach them instead of dissolving into mush.
The controls surprised me just as much. My character responded to every keystroke with barely any lag. I walked, turned, jumped, and the world kept up.
There’s a moment in games where your brain stops noticing the controls, and you feel like you’re just there. I got flashes of that here, which is strange when you remember there is no level file, no meshes, no physics engine. Every frame I saw was generated on the spot by a 14B model reacting to my keyboard.
The consistency impressed me most. I’d wander away from a landmark, spin the camera around for a while, and come back to find it exactly where I left it.
Anyone who has played with earlier world models knows this is the thing they always got wrong. Objects would vanish or mutate the moment they left your field of view. Here, the world remembers itself.
To be completely honest, I also ran into some rough edges during my session.
- I hit dropped frames a few times, usually during fast camera swings or busy scenes.
- Your experience depends heavily on your internet connection, since frames are generated server-side and streamed to your browser. On a slow connection, the 60fps promise becomes theoretical.
Sources
- dedicated entirely to the ideanews.ycombinator.com
- Robbyanttechnology.robbyant.com
- LingBot-World 2.0technology.robbyant.com
- technical reportarxiv.org
- Reactorreactor.inc
- https://vimeo.com/1209048540?fl=pl&fe=vlvimeo.com
- https://vimeo.com/1209052413?fl=pl&fe=vlvimeo.com
- WAIC 2026waica2026.worldaic.com.cn