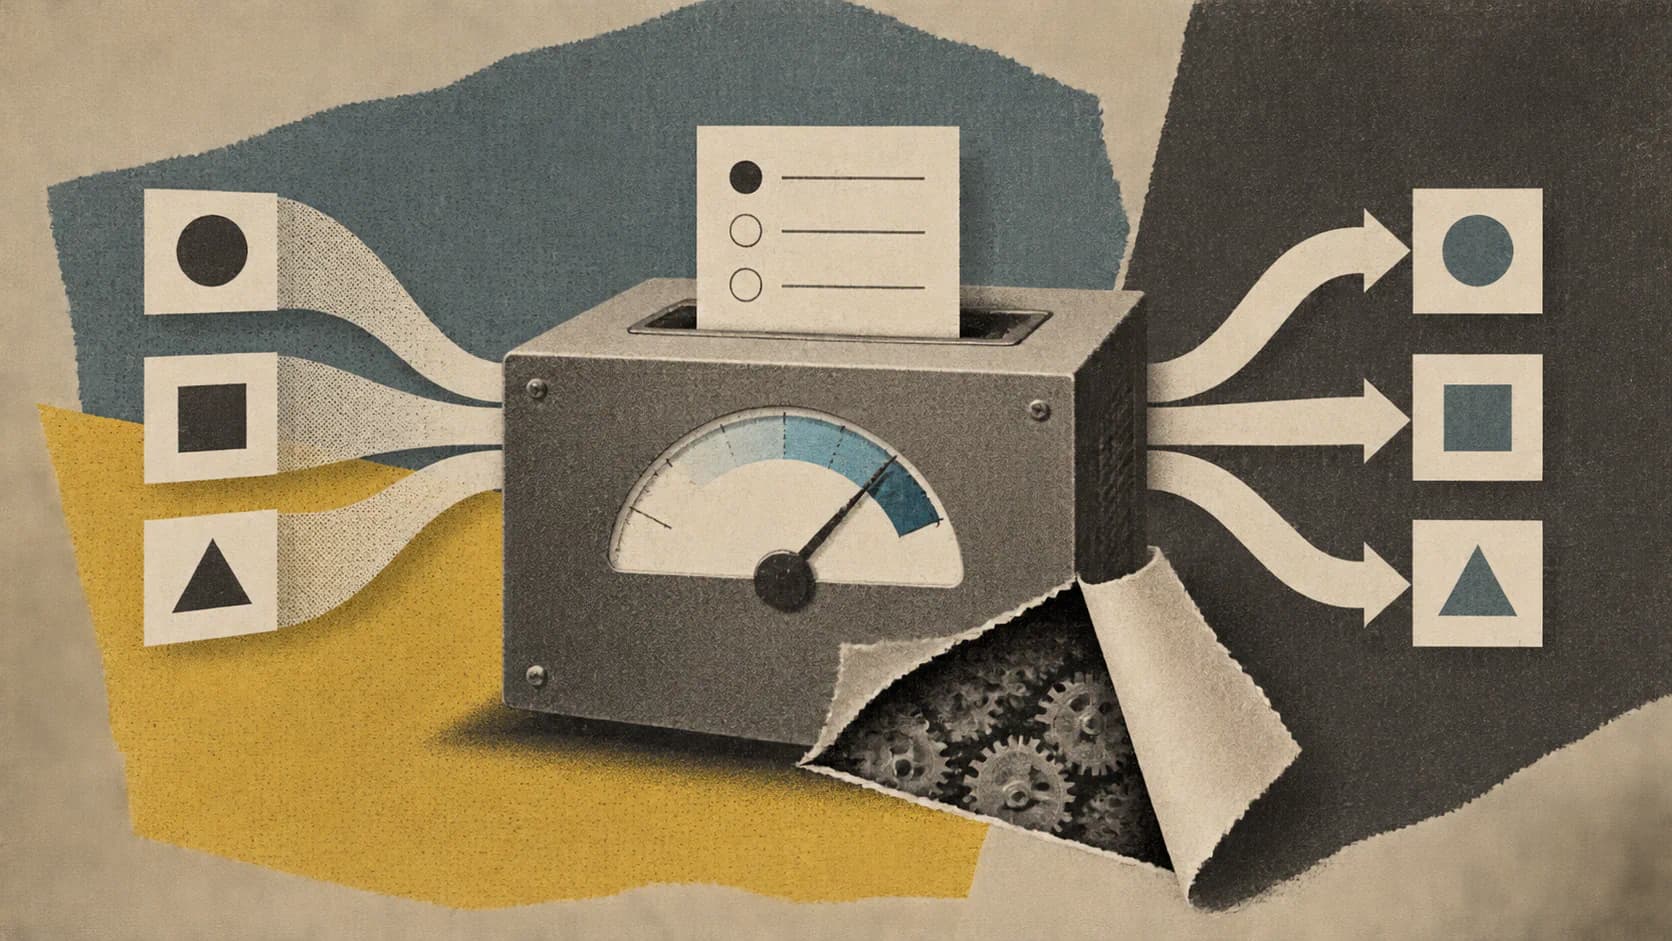
Microsoft is offering a model that charges $0.042 per million input tokens, with output free, to handle decisions developers might otherwise send to a general-purpose LLM. Rather than generate an answer, Microsoft-Decision-1 returns probability scores for a fixed set of options.
That makes the model release relevant to the less visible work inside AI agents: choosing a route, grading a response, checking whether evidence supports an answer, or deciding whether a proposed action needs review. Microsoft announced Decision-1 on October 9, 2026, and lists it in Microsoft Foundry.
The launch announcement reports roughly 35 times lower median latency than GPT-6 Sol and the highest accuracy in Microsoft’s comparison across 36 benchmarks. Those are Microsoft’s measurements, not independently established production results. The useful question is narrower: can a specialized scorer replace expensive LLM calls at particular decision points without introducing unacceptable errors?
Decision-1 Scores Choices Instead of Writing Answers
A decision-scoring model takes a situation, a closed question, and predefined answer options. Its output is a probability for each option, rather than generated prose that another component must interpret.
For example, an application could provide a proposed tool call and ask whether it is permitted under a supplied policy. The options might be “allow,” “block,” and “cannot tell.” This is an illustrative workflow, not a published API request format.
According to the Microsoft Foundry model card, Decision-1 supports yes/no questions, multiple-choice questions, ratings, classification, and rubric-based evaluation. It produces structured scores in a single model invocation, accepts up to 32,768 input tokens, and has JSON output.
Microsoft describes those probabilities as calibrated. Calibration means confidence should correspond to observed correctness: decisions assigned high confidence should prove correct more often than those assigned lower confidence. That property matters when software must choose between acting automatically and escalating an uncertain result.
Calibration is still something developers need to verify on their own workloads. A model’s confidence on a benchmark does not establish how well its scores behave on an organization’s policies, documents, or unusual requests.
The model card also draws a useful boundary. Decision-1 is text-only and does not generate explanations or rationales. It is not designed for conversation, summarization, translation, or open-ended question answering. Its structured output is useful precisely because the application has already defined the decision.
The Qwen Base Matters More Than the Microsoft Label
Microsoft says it built Decision-1 by post-training Alibaba’s Qwen3.5-9B, using publicly available datasets processed through Microsoft’s Open Data process alongside synthetic data created by the team.
This is therefore a specialized model built on an existing open-weight foundation, rather than a newly disclosed Microsoft foundation model. The distinction helps explain the product: Microsoft is adapting a smaller model to a constrained scoring task instead of asking a general-purpose assistant to handle every workflow step.
Single-pass scoring also changes what the application receives. Developers do not need to request a written judgment and then extract a label from its wording. The output is designed to feed directly into application logic.
That does not make Decision-1 interchangeable with the original Qwen model. Post-training, calibration, and the serving interface are relevant parts of the product. Nor does its open-weight base, by itself, establish that Microsoft’s finished scoring model is downloadable or supported for local inference.
Microsoft says future versions will also use Microsoft AI and OpenAI models as bases. That is a stated development direction, not an available feature of this release.
Where It Can Replace an LLM, and Where It Cannot
Decision-1 is most relevant when the answer space is small and the necessary evidence can be supplied in the input.
For model routing, an application could score whether a request belongs on a cheaper model, a stronger model, or a human-review path. The application would still need to define what makes a request difficult and measure whether its routing choices preserve acceptable answer quality.
For grading and validation, a scorer could evaluate a response against a rubric or assess whether it is supported by supplied evidence. This can avoid paying for a long written critique when the workflow only needs a score or a pass-or-escalate decision.
For agent control, it could evaluate a proposed action before the application permits execution. Microsoft lists agent guardrails, content-safety screening, relevance judgments, and confidence-based automation among the intended uses.
The limits are substantial. Decision-1 does not invent the next tool call, write a plan, or supply missing evidence. If an application needs a rationale explaining why an action failed a policy check, the score alone will not provide it.
A probabilistic judgment also should not displace a deterministic check when the latter is sufficient. An application can directly enforce an allowlist or validate a required field without consulting an AI model. Decision scoring is more useful for semantic judgments that cannot be resolved by a simple rule.
Microsoft explicitly says the model is not designed or evaluated as the sole automated decision-maker for consequential decisions about people, including employment, credit, healthcare, and legal rights.
The 35x Latency Claim Needs a Narrow Reading
Microsoft reports that Decision-1 achieved the highest accuracy in its 36-benchmark comparison, covering nearly 150,000 questions on benchmarks the company says were kept blind from training.
The company also reports that it was the fastest model measured: roughly 35 times quicker than GPT-6 Sol at P50 latency and 4.5 times quicker than Quyet-1.0-Large, the runner-up in its comparison.
P50 is the median request latency. It does not describe the slowest requests, and a median advantage cannot establish how a service behaves under a particular application’s concurrency, input lengths, or deployment conditions.
The comparison is also about structured decision tasks. It does not demonstrate that Decision-1 is a better conversational assistant, coding model, or general reasoning system. Its documented output cannot perform many of those jobs.
Microsoft additionally reports an average 1.3% decision-flip rate across perturbations. That measures stability under the tested changes, not the overall probability of making a wrong decision. A stable answer can still be wrong; robustness and accuracy answer different questions.
These figures justify testing, but they should remain clearly labeled as vendor-reported results. Developers need application-level measurements of accuracy, calibration, latency, and error cost before treating the headline ratios as expected production performance.
The Price Is Low, but Routing Errors Can Be Expensive
At Microsoft’s announced rate, 100 million input tokens would cost $4.20, with no output-token charge.
As an illustrative calculation, 100,000 scoring calls using 1,000 billed input tokens each would total that amount. This is token arithmetic, not a measured application bill, and it excludes any other infrastructure or downstream model costs.
Sources
- launch announcementcommandline.microsoft.com
- Microsoft Foundry model cardai.azure.com
- Hacker News discussionnews.ycombinator.com