JetBrains has released downloadable Mellum 2.1 weights for developers who want to run a coding model on private infrastructure. Its training targets repository exploration, file editing, and checking changes, giving teams an agent-oriented LLM to evaluate without sending their source code to a hosted model.
The Mellum 2.1 announcement describes a 12-billion-parameter mixture-of-experts model that activates 2.5 billion parameters during inference. It retains Mellum 2’s architecture and Apache-2.0 license. The main change is post-training, particularly reinforcement learning in sandboxed environments.
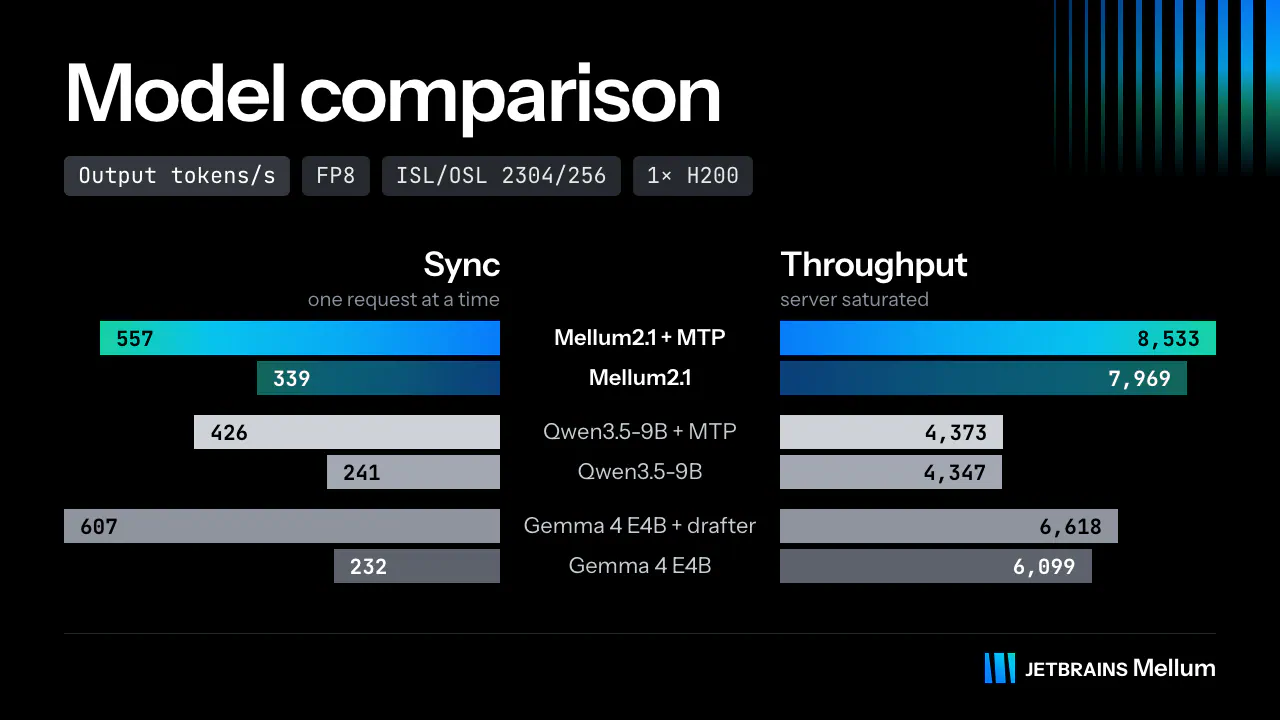
The release is more interesting as a potential worker inside a coding system than as another general-purpose chatbot. JetBrains positions it for coding agents, fast subagents, and self-hosted deployment. Whether it deserves those jobs depends on how reliably it completes repository tasks and how efficiently a team can serve it. The launch supplies JetBrains’ own evidence for both, with no independent validation.
Repository Work Became the Main Training Target
JetBrains says almost all the work on Mellum 2.1 went into post-training, primarily reinforcement learning. In Mellum 2, RL was a short final stage; for this release, the company says it became the main part of training.
The company reports millions of sandboxed runs across thousands of environments, using infrastructure it built in-house. Those environments trained the model for repository exploration, file editing, and checking its own changes.
A repository agent needs to find relevant files, interpret existing behavior, make a change, and use feedback to decide whether that change worked. Training around those interactions addresses a different problem from producing plausible code from a prompt.
JetBrains also reports adding RL tasks in mathematics, competitive programming, science, tool use, and software engineering. It combined open datasets with tasks developed internally, then filtered sources before training. The company identifies broken tests, unverifiable answers, and tasks that were too easy or impossible for the model as problems in open training data.
An environment’s feedback is only useful when it measures the intended outcome: a broken test can reward or penalize the wrong behavior. JetBrains’ description suggests it treated feedback quality as a training concern, although the announcement does not provide enough detail to independently assess the filtering process.
The resulting capabilities remain company claims. “Checks its own changes” should mean that the model can participate in a verification workflow, not that its output is automatically correct. Passing an available test is useful evidence, but suitable test coverage and review are still needed.