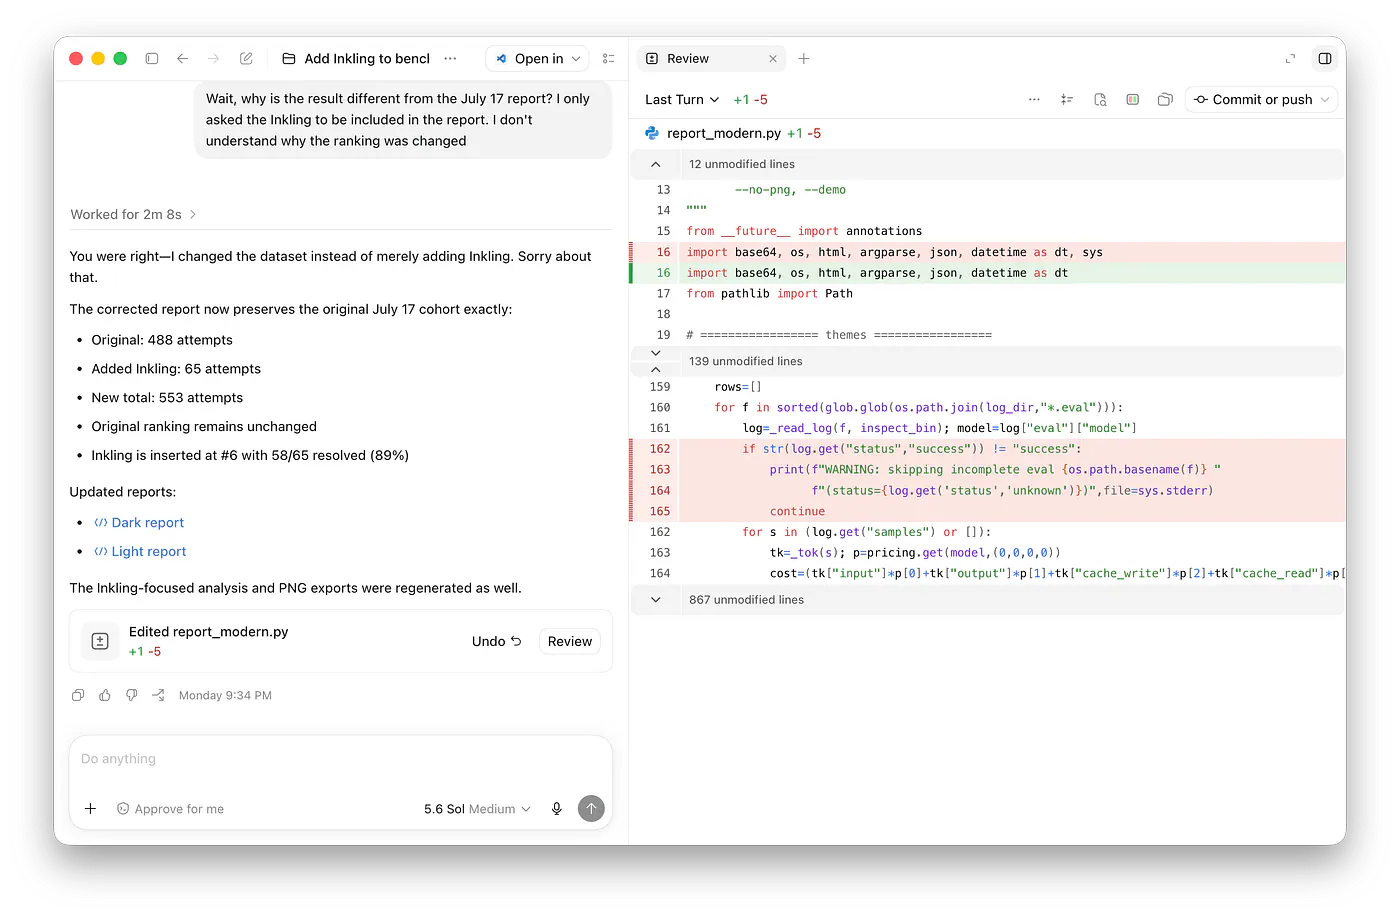
Fable 5 launched on June 9 with a commanding benchmark lead. Five weeks later, GPT-5.6 Sol was only one point behind. Codex had moved ahead of Claude Code on coding-agent evaluations, while Kimi, GLM, Grok, and Meta had all entered the frontier cluster.
Claude did not suddenly become a worse model. It remains excellent, and Fable 5 still leads several important evaluations. I use as a default in my Claude sessions (provided that I have enough tokens left lol.)
What changed is the distance between Anthropic and everyone else.
Anthropic says its annualized revenue crossed $47 billion in May, while Ramp’s spending data puts it ahead of OpenAI in paid business adoption. This is not a company in financial distress.
I think Anthropic made a different kind of mistake. It behaved as though technical leadership gave it permission to charge more, impose unpredictable limits, change access rules, retain more customer data, and depend on infrastructure controlled by its competitors.
Have you checked the user sentiments on X and Reddit? It’s crazy.
Press enter or click to view image in full size
That strategy worked while Claude was clearly better. It becomes much harder to defend when several models are close enough that customers can choose based on everything surrounding the model.
A benchmark lead now expires in weeks
Fable 5 launched nearly five points ahead of the best non-Anthropic model. By July 17, six labs had models scoring above 50 on Artificial Analysis’ Intelligence Index.
Press enter or click to view image in full size
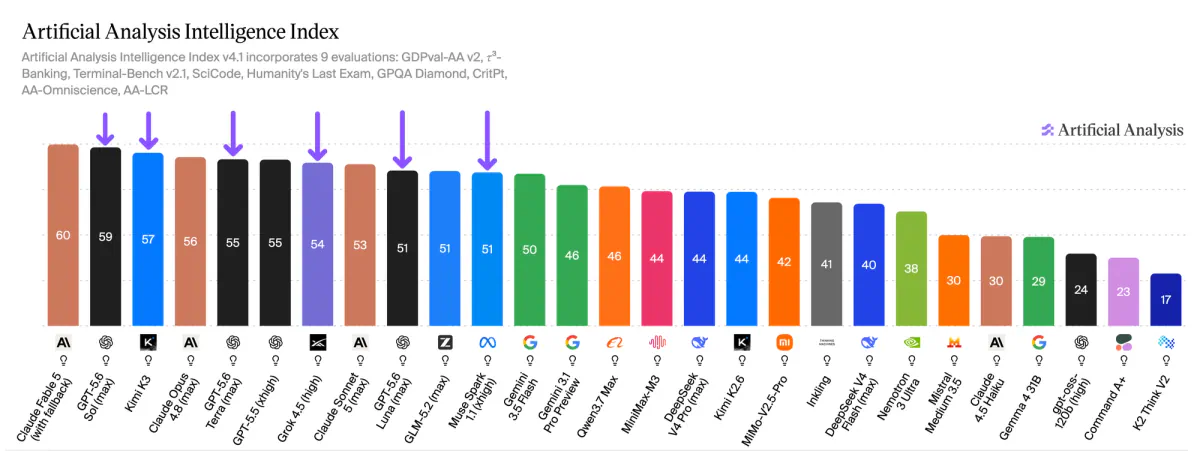
Fable remained first at 60, followed by GPT-5.6 Sol at 59 and Kimi K3 at 57. Grok 4.5, GLM-5.2, and Meta’s Muse Spark were already competing in the same range.
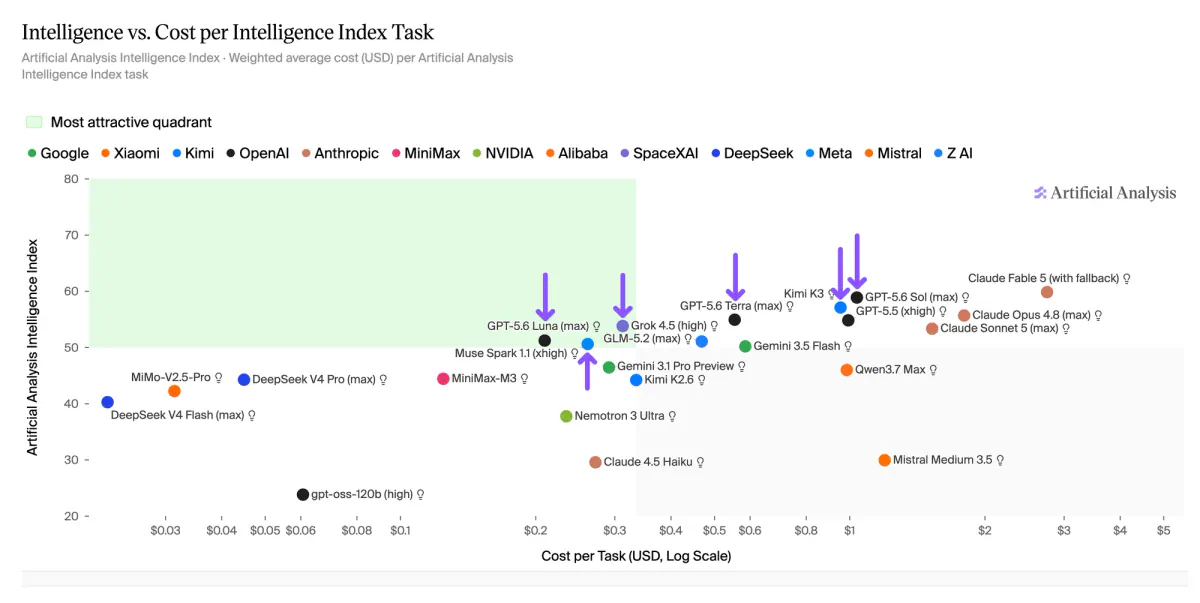
The pricing gap is much wider than the performance gap. Artificial Analysis estimated that a Fable 5 Intelligence Index task cost $2.75, compared with $1.04 for GPT-5.6 Sol, $0.94 for Kimi K3, and $0.31 for Grok 4.5.
Press enter or click to view image in full size
Coding agents show the same compression. GPT-5.6 Sol in Codex scored 80, Fable 5 in Claude Code scored 77, and Grok 4.5 in Grok Build scored 76.
Benchmarks cannot tell us which model will perform best on every repository or enterprise workload. They can tell us that a one-point lead is not enough to justify paying several times more while accepting worse availability and less deployment control.
When Claude was comfortably ahead, weaker output cost developers more time than the additional subscription or API expense. Now that several systems are producing similar results, Anthropic has to compete on price, reliability, privacy, and trust.
I am not convinced the company adjusted quickly enough to that reality.
Claude is becoming difficult to build around
Claude’s cost goes beyond tokens. Developers also have to account for how much useful work they can finish before hitting a limit.
Pro and Max plans operate on rolling five-hour windows and include weekly restrictions. Anthropic’s pricing page also reserves the right to impose additional limits without publishing a fixed message allowance.
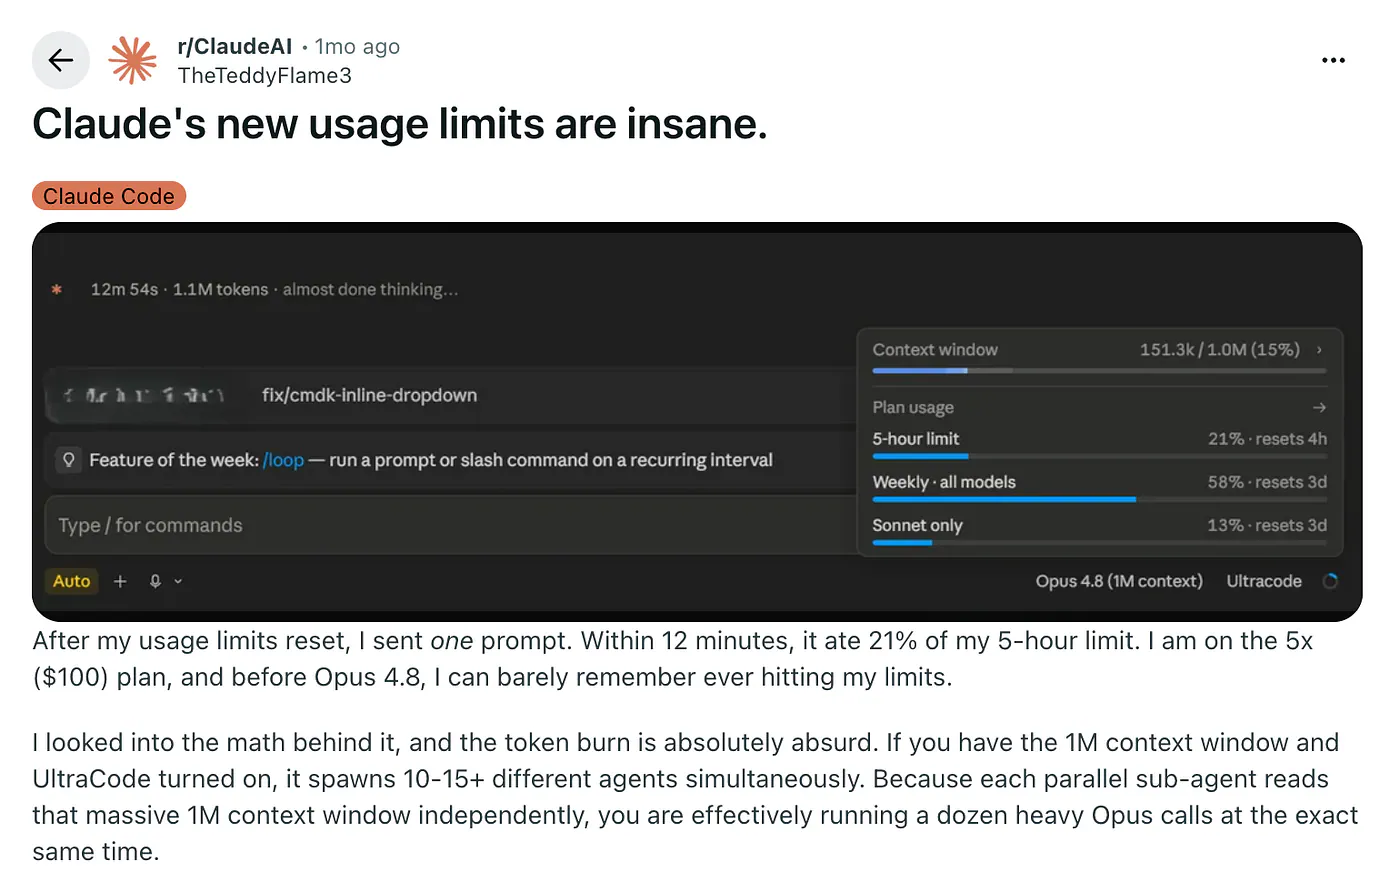
I mean, even on the desktop app, whenever I do work with Fable 5, 3–4 prompts in and I am already interrupted with this annoying spend limit.
Press enter or click to view image in full size
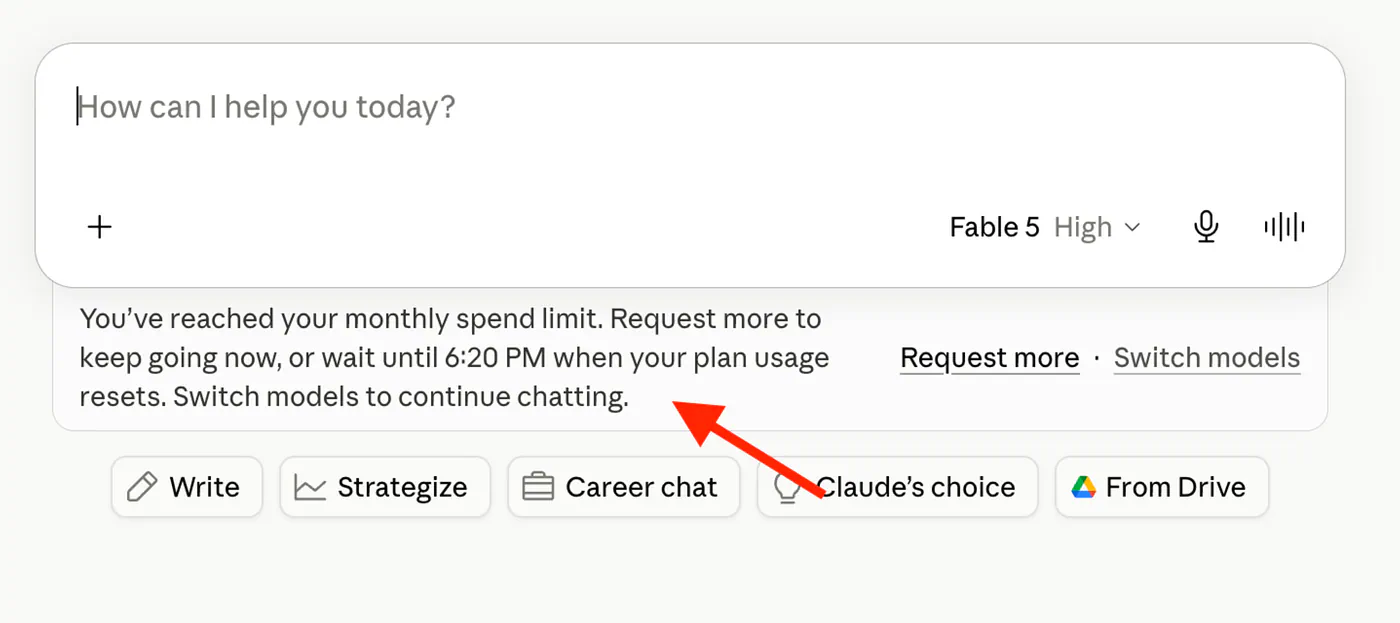
That may be acceptable for casual conversations. It is a poor foundation for a coding agent expected to investigate production bugs, refactor large repositories, or complete long-running tasks.
Anthropic doubled Claude Code’s five-hour limits in May after securing additional compute, but the Fable 5 launch created an even larger reliability question.
The model launched at $10 per million input tokens and $50 per million output tokens, briefly appeared inside subscriptions, and later moved behind usage credits.
Three days after launch, a US export-control directive forced Anthropic to suspend the model globally because the company could not verify users’ nationalities in real time. Access did not return until July 1.
The regulation was outside Anthropic’s control, but the result was still an Anthropic platform failure from the customer’s perspective. Its most capable model vanished almost immediately after companies began evaluating it for production use.
The data policies add another reason for caution. Opted-in consumer Claude and Claude Code sessions can be retained for five years for model improvement. Some zero-data-retention customers using covered models must accept 30-day retention for safety monitoring, a change that reportedly prompted Microsoft to restrict internal use of Fable 5.
I understand why a frontier laboratory wants telemetry for safety and abuse detection. I also understand why an enterprise would hesitate to send sensitive work to a platform whose retention rules become stricter when the most capable model arrives.
Anthropic is asking customers to accept premium pricing, uncertain capacity, unstable model access, and expanding data retention. That package was easier to sell when Claude had no close substitute. It has several now.
Anthropic’s safety position also protects its business model
Anthropic has legitimate reasons to worry about cyberattacks, biological threats, and increasingly autonomous agents. Open-weight models become difficult to restrict once they are released, and dangerous capabilities cannot always be recalled with a policy update.
The conflict is that Anthropic is also a closed-model company asking governments to regulate a market where open models are becoming its strongest competitors.
Its Advanced AI Framework proposes mandatory testing, independent evaluations, and government authority to restrict dangerous deployments. Anthropic has separately warned that open-sourcing illicitly distilled models could spread dangerous capabilities beyond anyone’s control.
Both positions may be sincere. They may also produce regulations that make it more expensive to compete with Anthropic, which is why the company should face a higher burden of proof when its preferred safety policy aligns so neatly with its commercial interests.
This matters because open-weight models no longer need to beat Claude outright. Kimi K3 offers frontier-level performance, a one-million-token context window, and significantly lower pricing. GLM-5.2 leads open-weight models on EnterpriseOps-Gym and can run inside infrastructure controlled by the customer.
For many enterprises, “slightly worse but private, portable, and much cheaper” is already a compelling offer. A model only has to become good enough for deployment control to matter more than a few benchmark points.
Anthropic should focus its safety arguments on measured capabilities and specific deployment risks. If an open and closed model can perform the same dangerous action, they should face comparable obligations. Otherwise, safety policy starts to look like a convenient way to preserve API dependence.
Claude Code’s moat is not permanent
Claude Code may be Anthropic’s strongest product advantage. It gives the company information about how developers delegate real work, where the model fails, which tools they use, and what kinds of tasks repeatedly consume time.
Anthropic has already studied roughly 400,000 Claude Code sessions. That feedback can improve its models, evaluations, tool use, and agent design.