SpliceAI2 Predicts Full Transcripts Directly From DNA
Illumina released code, weights and billions of variant scores, but its reported gains come with licensing restrictions and a tissue-dependent prediction weakness.
Listen
AI narration
11:23
0:00 / 11:23
AI SummaryGenerated from this article
Illumina released SpliceAI2, a machine learning model that predicts how DNA variants alter RNA splicing and reconstructs full transcript isoforms directly from DNA sequence without requiring tissue samples. The company reported that SpliceAI2 identified 17 percent more disease-relevant variants than competing models in a rare-disease dataset, though this represents a prioritization result rather than confirmed diagnoses.
Researchers can install the model locally via PyPI or access precomputed predictions covering approximately four billion single-nucleotide variants and 150 million indels. The pretrained weights and predictions carry non-commercial licensing restrictions, with commercial users directed to contact Illumina. Illumina acknowledges that while the model captures tissue-specific splicing patterns, it remains less effective at predicting how variant effects change between tissues.
Illumina has released SpliceAI2’s source code, pretrained weights and large collections of precomputed variant scores. Researchers can use the model to predict how DNA variants alter RNA splicing and reconstruct potential transcript isoforms without first generating RNA sequencing data from the relevant tissue. The release offers both local inference and an annotation route.
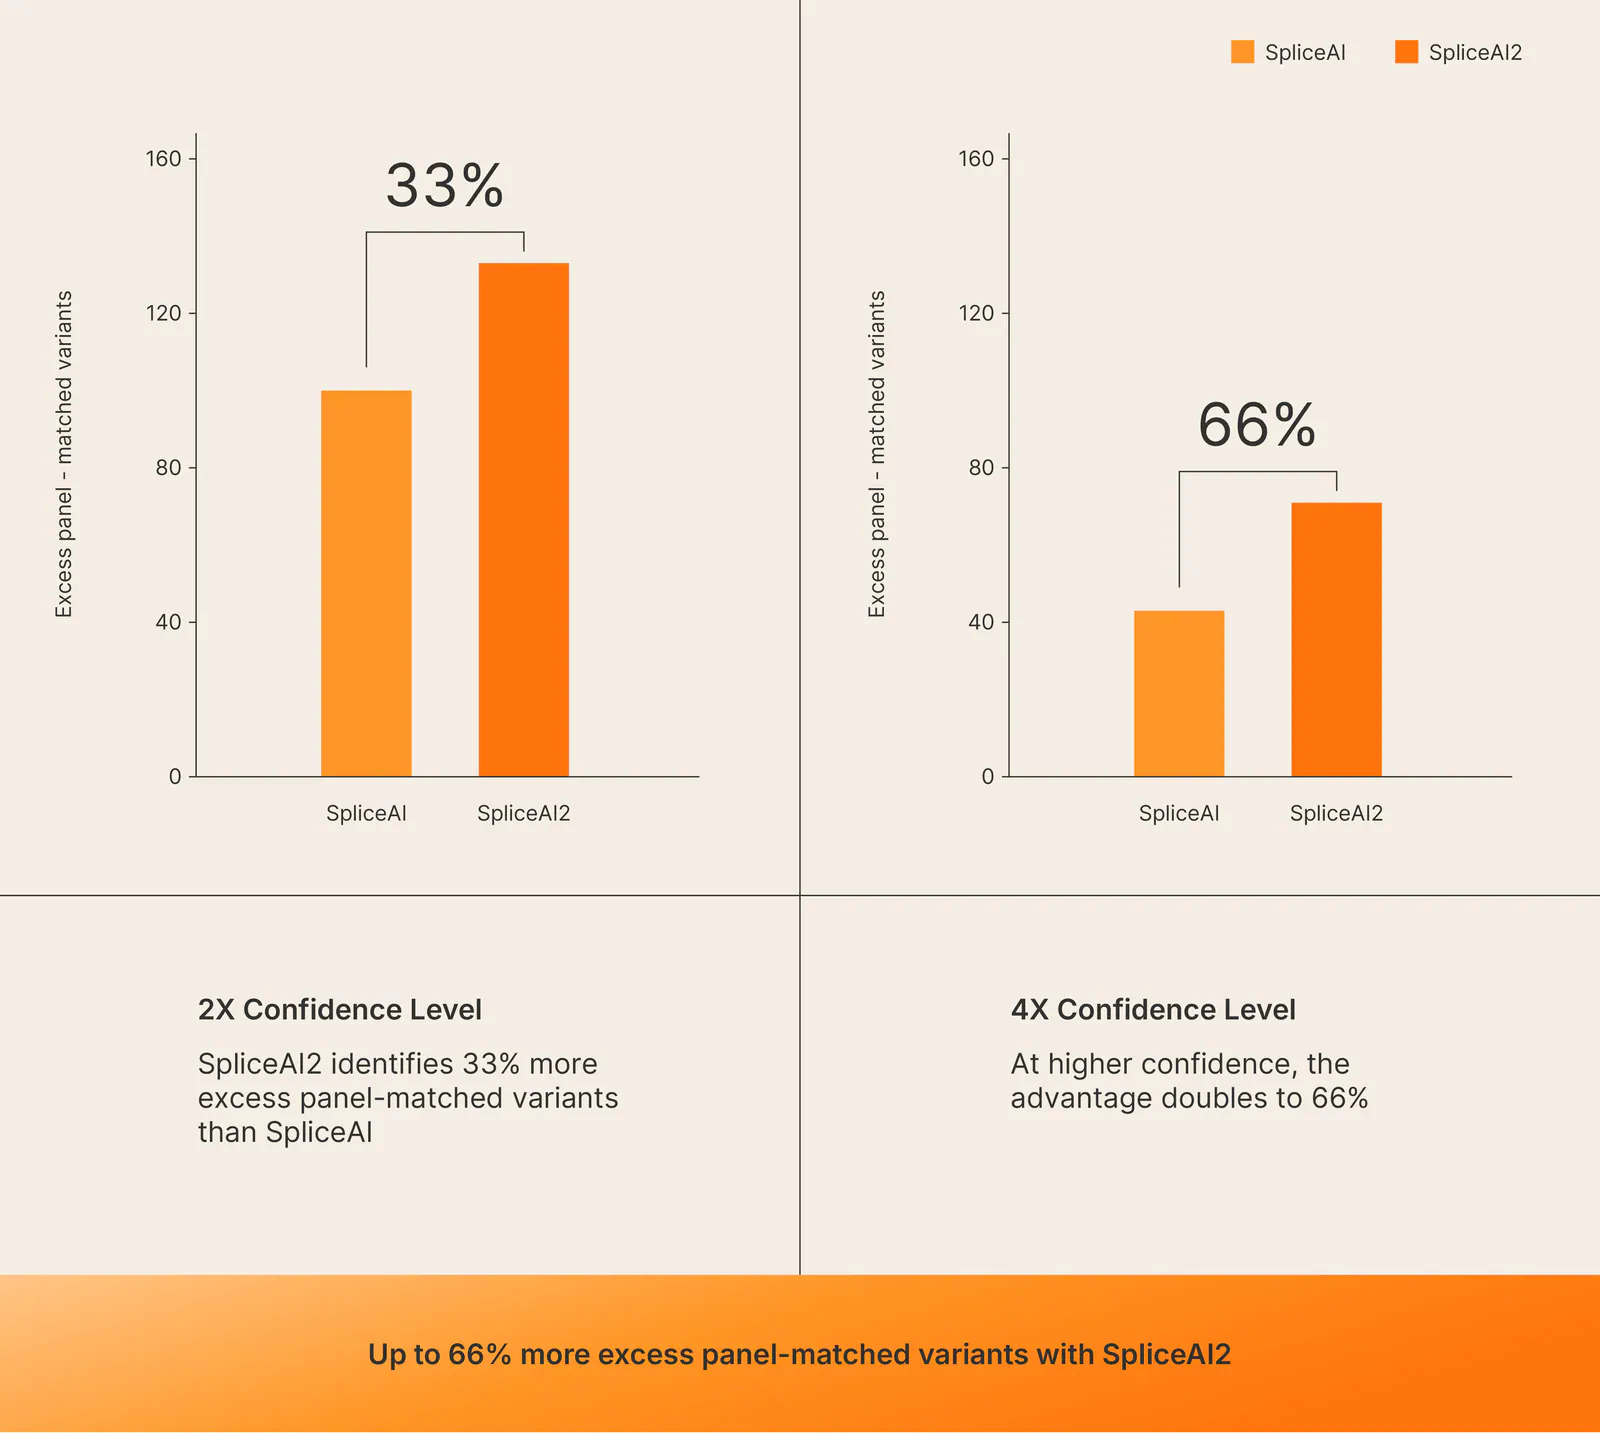
In its October 8 announcement, Illumina reported that SpliceAI2 identified 17% more disease-relevant variants than other tested splicing models in a rare-disease research dataset. This is a company-reported prioritization result, not evidence of a 17% increase in confirmed diagnoses.
Beyond ranking variants, SpliceAI2 predicts splice-site usage, connections between splice sites and complete transcript isoforms directly from DNA. These remain research predictions, and Illumina acknowledges a weakness in estimating how a variant’s effect changes between tissues.
SpliceAI2 Connects Splice Sites Into Transcripts
RNA splicing determines how segments of a gene are assembled into transcripts. Different combinations can produce different transcript isoforms, so identifying a possible splice site answers only part of the question. Researchers also need to know which sites connect and what transcript those connections produce.
According to Illumina’s technical introduction, the original SpliceAI focused on predicting splice sites. SpliceAI2 adds quantitative site usage, splice-junction predictions and transcript reconstruction.
Each output addresses a different research question. Site predictions identify locations where splicing may occur and how strongly those locations are used. Junction predictions connect donor and acceptor sites, while transcript predictions assemble those relationships into candidate full-length isoforms. When interpreting a mutation, researchers can investigate a predicted splice-site change alongside the altered junction and resulting transcript structure.
Illumina says the training data included 314,745 RNA-seq samples across ten species and more than 46 million filtered splice junctions. Transcript prediction additionally used 330 long-read ENCODE samples. Long reads provide information about which splice events occur together in a transcript, beyond the individual events observed in fragments.
The model accepts DNA sequence for inference, removing the requirement to generate tissue RNA before producing a computational prediction. The predicted transcript is still not an observed transcript.
Work with Zeniteq
Let’s work together
We’re open to thoughtful collaborations with teams building in AI. Explore the ways we can work together.
Researchers who want to work directly with the released code can instead clone and install the repository in editable mode:
git clone https://github.com/Illumina/SpliceAI2.git
cd SpliceAI2
pip install -e .
A CUDA-capable GPU is required for the documented local inference workflow. The repository also advises installing a compatible PyTorch build if CUDA errors occur. Installing the package successfully does not, on its own, establish that a machine is ready to run predictions.
For variant scoring, the command-line workflow requires pretrained model weights, a reference genome FASTA and a tab-separated variant file. The variant columns are chrom, pos, ref, alt and strand. For insertions and deletions, the reference and alternate fields contain nucleotide sequences.
If the gene strand is unknown, the instructions recommend evaluating both strands separately and aggregating predictions. The optional --no_compile flag skips torch.compile, which the repository suggests for small variant sets or compilation failures.
For covered variants, researchers can avoid rerunning inference. Illumina has released precomputed predictions covering approximately four billion possible single-nucleotide variants and 150 million population-observed indels within protein-coding genes, using GENCODE v48 and GRCh38.
The files are not an unrestricted catalog of every possible variant throughout the genome. Researchers need to check annotation scope, genome assembly and whether their particular allele is covered. According to the repository, precomputed scores are also available through DRAGEN Annotation.
Transcript reconstruction uses a separate workflow. The repository provides a Python example that takes DNA sequence, predicts sites and junctions, and decodes candidate transcripts. To examine a variant’s transcript consequences, the instructions call for separate predictions from reference and alternate sequences.
The Summary Score Ranks Splicing Effects, Not Disease Risk
SpliceAI2 produces a spliceai2_summary_score between zero and one, with higher values indicating larger predicted effects on splicing. The repository recommends three operating thresholds:
SpliceAI2 threshold
Recommended interpretation
0.1
High recall
0.25
Balance of precision and recall
0.5
High precision
These thresholds guide screening; they are not diagnostic boundaries. A high score is not a probability that a variant causes disease, and researchers should not automatically carry numeric thresholds over from the original SpliceAI.
The summary score is the maximum predicted change among the strongest donor-gain, donor-loss, acceptor-gain and acceptor-loss effects. SpliceAI2 also predicts junction effects, but those do not enter this calculation.
The output contains 260 additional columns describing site and junction changes, including reference and alternate probabilities, distances and multiple ranked effects. Researchers can use that detail to investigate what the model expects to change instead of retaining only a single annotation number.
The summary score is convenient for a first-pass screen. For an unusual candidate, the underlying site, junction and transcript predictions provide a more useful basis for designing follow-up experiments.
The Rare-Disease Result Is an Enrichment Test
Illumina’s reported benchmark analysis examined 7,504 Genomics England participants with extensive phenotype information. The researchers asked whether predicted splice-altering variants occurred preferentially in genes associated with each participant’s observed phenotype.
They repeatedly shuffled phenotype assignments to estimate the association expected by chance. At matched confidence thresholds, Illumina says SpliceAI2 identified 17% more disease-associated variants than any other tested splicing model.
The enrichment in genes connected to participants’ phenotypes provides relevant evidence for variant prioritization. It does not establish that every additional candidate was experimentally confirmed, pathogenic or responsible for an otherwise unresolved case.
Illumina reports comparisons against the original SpliceAI, Pangolin and Google DeepMind’s AlphaGenome. It says University of Oxford academic collaborators independently ran the AlphaGenome comparisons. That contribution should not be confused with independent reproduction of the entire study or validation of every release claim.
The repository cites the underlying work as an unpublished 2026 manuscript. The results should therefore be presented as reported findings, with the Oxford contribution identified specifically, rather than as a settled performance consensus.
For transcript prediction, Illumina also reports reconstructing the most common transcript for previously unseen genes 82% of the time, compared with 78% when training used short-read data alone. This supports the contribution of long-read training data to the stated evaluation task, without showing that the model recovers every isoform or all tissue-dependent transcript changes.
Released Weights Have Non-Commercial Restrictions
The repository’s availability terms specify that the pretrained weights and precomputed predictions are available for academic and non-commercial research. Commercial users are directed to contact Illumina at AI_licensing@illumina.com.
Source-code availability does not make every released asset unrestricted. Researchers should distinguish access to the code from the permissions attached to the weights and prediction files. A commercial team cannot infer permission to use those assets simply because the software can be installed from PyPI.
Illumina also labels SpliceAI2 for research use only, not for diagnostic procedures. Its rare-disease benchmarks do not remove that restriction. The immediate use is research prioritization and hypothesis generation; a model score should not be treated as a clinical determination.
Tissue-Dependent Variant Effects Remain a Weak Spot
Illumina reports that SpliceAI2 captures tissue-specific splicing patterns, but is less successful at predicting how the effect of a particular variant changes between tissues.
Predicting that a splice junction is used differently across tissues is a separate task from establishing how a mutation will alter its usage in each tissue. Researchers investigating a tissue-dependent disease mechanism need to preserve that distinction.
DNA-only prediction is especially useful when the relevant tissue is difficult to obtain or a gene is insufficiently expressed in accessible samples. It allows researchers to rank candidates and propose transcript consequences before committing to RNA experiments. Tissue measurements have not become unnecessary.
The most defensible near-term workflow is to use SpliceAI2 to narrow the search, inspect the predicted structural changes and select candidates for appropriate validation. With the released code and weights, other researchers can also test whether Illumina’s reported gains transfer to their cohorts. That combination of immediate access and testable claims is more consequential than the headline benchmark alone.