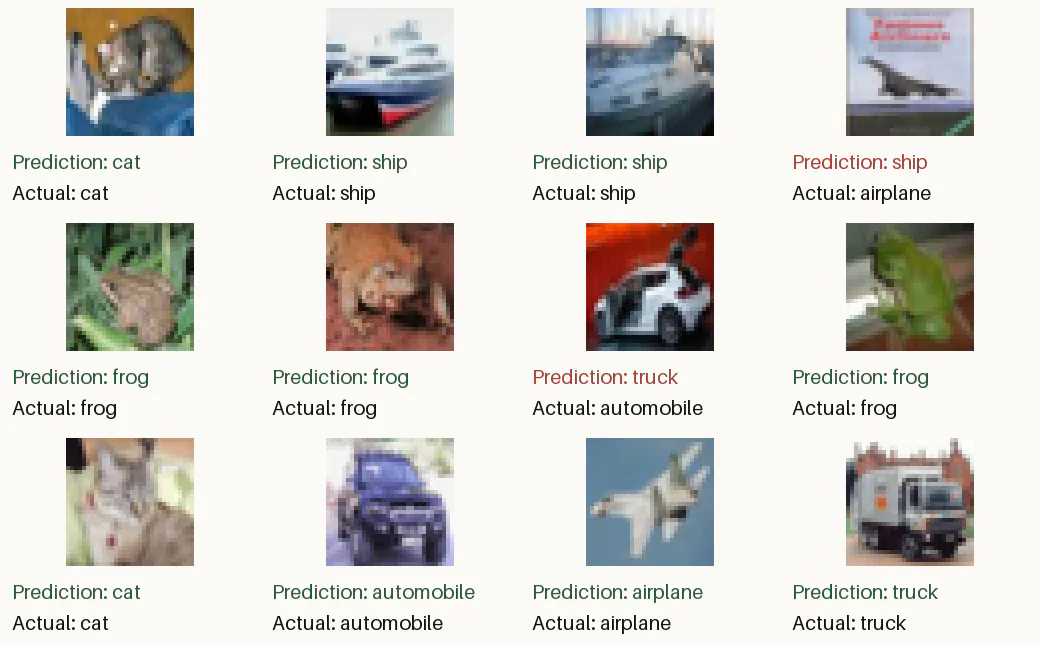
Lex Toumbourou gave an LLM-driven agent a training job without supplying a dataset URL, script, or model architecture. The agent found CIFAR-10, trained an image classifier, and reported 81.41% accuracy on 10,000 held-out images. His reported model-token bill for the final attempt was about $0.0085.
The result wasn’t entirely hands-off. Toumbourou explicitly allowed the dataset hosts through the sandbox’s network restrictions and gave the agent one nudge toward a faster download.
His agent-harness walkthrough, published October 11, 2026, presents the experiment as an attempt to satisfy a challenge Ian Goodfellow discussed in a 2019 interview. It also offers a step-by-step explanation of the software surrounding a coding model, which is more useful than a declaration about intelligence.
That software determines what an agent can execute, which information it retains, where its credentials live, and when a human must intervene. The CIFAR-10 run makes those responsibilities concrete. It remains one author-documented experiment, however, rather than an independently reproduced benchmark.
The Challenge Was to Complete a Training Job
Toumbourou’s test asked the finished agent to find CIFAR-10, train a classifier, report held-out accuracy, and leave both the code and the trained model behind. He did not supply a dataset URL, training script, or model architecture.
A plausible explanation of convolutional networks wouldn’t satisfy that request. The agent had to obtain data, produce runnable software, execute training, and return a measurable result with artifacts.
After 12 CPU training epochs, the reported outcome was 8,141 correct predictions out of 10,000 held-out images. Two models had different roles: the LLM organized and wrote the work; the resulting image classifier performed the CIFAR-10 predictions.
Toumbourou’s Goodfellow framing supplies historical motivation, not a standardized pass/fail protocol. Completing this particular workflow provides evidence of useful coding-agent behavior. It does not, by itself, establish general intelligence.
Four Tools Make the LLM’s Decisions Executable
The walkthrough defines a harness as everything in an agent that isn’t the model. Its smallest version builds context, calls the LLM, executes a requested tool, and returns the tool’s output to the conversation.
Conceptually, the loop looks like this:
while True:
    reply = model(context)
    if not reply.tool_call:
        break
    result = run_tool(reply.tool_call)
    context.append(result)
Those simple-looking operations contain much of the engineering work.
Toumbourou puts the model behind an adapter, allowing the rest of the harness to use a common interface instead of a vendor client directly. His example retains provider-specific response items for subsequent turns and tracks token cost. Retaining that state preserves the conversation structure the API expects in the next request.
For local actions, he implements four tools: read_file, write_file, search_replace, and bash. Together, they let the model inspect files, create programs, modify existing code, and run commands.
The shell tool delegates to Python’s subprocess.run, with captured output and a timeout. It returns an exit code, standard output, and standard error, giving the LLM evidence to correct a failed command instead of guessing what happened.
Tool output is also truncated. An unrestricted training log could consume the model’s available context without helping it decide what to do next. Details like these distinguish an executable agent from a chat interface with a terminal attached.
Memory, Skills, and Sub-Agents Add Structure Around the Loop
The guide covers context management, safety controls, skills, orchestration, and extension surfaces alongside tool execution. These components solve different problems and shouldn’t be treated as interchangeable additions.
As a task grows, context management determines what the model can still see. Tool results provide feedback, but preserving every byte indefinitely is neither necessary nor practical. A harness needs to retain information relevant to the next decision while controlling the volume of accumulated output.
Skills supply reusable task guidance and procedures without requiring the harness itself to encode every workflow. Sub-agent orchestration introduces a delegation boundary: each assignment must be explicit and return something the coordinating agent can use.
The model adapter also exposes optional web search. External information can help an agent locate resources, though access to that information does not grant permission to download or execute something.
The implementation guide covers these capabilities; it does not establish that every component contributed to the CIFAR-10 success. A single end-to-end result cannot isolate the contribution of memory, skills, search, or sub-agents. For developers, the value is in making those responsibilities visible and separable.
The Permission Gate Is Not the Sandbox
The walkthrough’s shell tool can execute commands on the machine where it runs. The permission gate and execution environment are therefore central design decisions.
A permission gate is the harness’s decision point for whether a requested action may proceed. The LLM proposes an action; software outside the model must apply the relevant policy. Asking the model to behave safely does not replace an enforceable check.
Isolation addresses a different question: what resources can an approved or mistakenly permitted action reach?
For the reported CIFAR-10 run, Toumbourou used a Docker sandbox and mounted the harness read-only. He kept the OpenAI API key on the host through Docker’s proxy instead of placing it inside the agent’s execution environment. He also explicitly allowed only the dataset hosts.
Each boundary has a distinct purpose:
- The read-only harness mount restricts changes to the mounted implementation.
- Host-side credential handling avoids handing the API key directly to generated training code.
- The network allow-list limits external destinations available to the workload.
- The permission gate controls whether requested actions proceed.
The allow-list also affects task completion. Finding a dataset address does not make that destination reachable, so a network restriction can produce an apparent agent failure even when the proposed download is reasonable.
None of this proves arbitrary generated code is safe. A coding agent’s security cannot be judged solely by its system prompt: the model’s instructions, action permissions, filesystem access, credentials, and networking are separate controls.
Reproducing the Run Means Recording the Human Help
Toumbourou’s published code directory includes , , , and a directory. Developers have an implementation to inspect, not only a screenshot of a successful answer.
Sources
- agent-harness walkthroughnotesbylex.com
- published code directorygithub.com
- 2024 CIFAR-10 researcharxiv.org