Datalab says its new Indra OCR package processes 49.4 pages per second on 32 CPU cores, using a recognition model with about one million parameters. It also returns reading order, layout labels, and Markdown or JSON, making it a potential preprocessing tool for search, classification, and LLM document pipelines.
The release announcement includes unusually useful qualifications: the headline throughput excludes model loading, accuracy changes when PDF text layers are unavailable, and one competing document pipeline failed to complete part of the evaluation.
Indra looks worth evaluating for high-volume, clean-print workloads. Those qualifications carry more weight than the parameter count alone, though: Datalab’s first-party results do not establish a universal speed or accuracy advantage.
The One-Million-Parameter Claim Covers the Recognizer
According to the Indra repository, the main recognizer, rec.onnx, contains about one million parameters. That count does not cover every component in the document-processing package.
The standard model downloads total approximately 18 MB. The package uses ONNX Runtime, OpenCV, and pypdfium2 without requiring PyTorch. Datalab has published the model artifacts on Hugging Face.
In its default auto mode, Indra avoids unnecessary recognition work by reading a PDF’s existing text layer where that layer passes its checks and using OCR elsewhere. A page can therefore contain extracted digital text, recognized text, or a mixture.
For batch processing, the CLI and Python’s convert_many distribute individual pages across single-threaded worker processes, with one worker per core. This lets a long PDF use multiple cores instead of remaining confined to one worker.
The design makes CPU deployment plausible without proving lower operating costs. Actual savings depend on available cores, startup overhead, document complexity, and how often another engine must repair or replace the output.
What the 49.4-Page Benchmark Measures
Datalab’s throughput test used the same 300 OmniParseBench pages on an AMD EPYC x86 machine without a GPU. Each engine received one single-threaded worker per core, and Indra’s result was averaged over three runs.
At 32 cores, the company reports:
- Indra OCR: 49.4 pages per second.
- PaddleOCR PP-OCRv6 small, through RapidOCR: 4.28 pages per second.
- Tesseract 5: 2.92 pages per second.
Those figures produce the advertised 11.5× advantage over the tested PP-OCR configuration and 16.9× over Tesseract.
Including model loading brings Indra’s throughput to 37.7 pages per second for a 300-page job through convert_many. The difference from the headline figure is material for short-lived processes or small batches.
A small server should not be expected to match the 32-core result. Datalab reports 7.3 pages per second on four cores.
Single-page latency is a separate measure. The company’s accuracy evaluation reports a median of 228 milliseconds per page for default Indra on four vCPUs. Parallel workers increase aggregate throughput; they do not make an individual page complete in one forty-ninth of a second.
These are vendor measurements. The supplied release materials do not provide an independent reproduction.
The Accuracy Lead Depends on the PDF Text Layer
Datalab evaluated accuracy using 16,288 pass/fail tests across 2,937 pages in its OmniParseBench benchmark. It says engines ran on x86 with four vCPUs, one page at a time, using the same pages and scorer with default settings.
The most revealing comparison is between Indra’s default and forced-OCR modes:
| Engine or mode | Text test score | Median milliseconds per page |
|---|---|---|
| Indra, text layer plus OCR | 41.3 | 228 |
| Indra, OCR only | 33.5 | 303 |
| PaddleOCR PP-OCR text models | 35.8 | 2,685 |
| Tesseract 5 | 19.3 | 5,496 |
These are benchmark test scores, not percentages of characters transcribed correctly.
Default Indra beats both tested text engines on this measure. With the PDF text layer disabled, however, its text score falls below PP-OCR’s: 33.5 versus 35.8. It remains substantially faster in Datalab’s test.
Reusing reliable digital text is sensible engineering, but the default result measures a document-extraction strategy that includes more than recognition from pixels. Developers processing scanned archives should pay particular attention to the OCR-only row.
For the full-pipeline comparison, Datalab reports an overall score of 62.1 for default Indra, against 58.4 for PaddleOCR PP-StructureV3. PP-StructureV3 nevertheless scores higher on text alone, 55.6 versus 41.3.
That comparison has an additional qualification: a PP-StructureV3 evaluation shard stalled on its first page, leaving 19 pages out of that accuracy row. The two results therefore do not cover exactly the same completed page set.
Separately, PP-StructureV3’s throughput test used a time-capped subset. Datalab labels those throughput figures as upper bounds. This limitation is distinct from the stalled accuracy shard; neither supports treating the largest advertised speed ratio as a clean, complete-workload measurement.
Datalab also acknowledges faster Tesseract and PP-StructureV3 configurations that it did not accuracy-test. The release compares selected defaults, not every engine’s best speed-quality tradeoff.
Install Indra and Inspect Its Structured Output
The documented requirement is Python 3.10 or newer. The quick start is:
pip install indra-ocr

indra-ocr paper.pdf
indra-ocr scan.png --format json
indra-ocr *.pdf --out results/ --cores 8
The first conversion downloads and caches the models. For a deployment with locally provisioned artifacts, the documentation provides INDRA_OCR_MODEL_DIR or the --model-dir option.
To evaluate recognition without benefiting from embedded PDF text:
indra-ocr paper.pdf --mode ocr --timings
Use this control when comparing results against image-only OCR engines.
Markdown output includes headings, paragraphs, lists, and tables represented as HTML. Page headers and footers are omitted by default; --keep-furniture retains them.
JSON provides more useful evidence for pipeline debugging. The documented output includes:
- Line text, bounding boxes, and confidence values.
- Layout blocks with labels, boxes, and reading order.
- A page source indicating text-layer extraction, OCR, or hybrid processing.
- Rotation, skew, and per-stage timings.
The JSON format writes one object per page. Retaining source and timing fields lets developers distinguish poor recognition from text-layer extraction problems, avoiding the assumption that every failure is an OCR error.
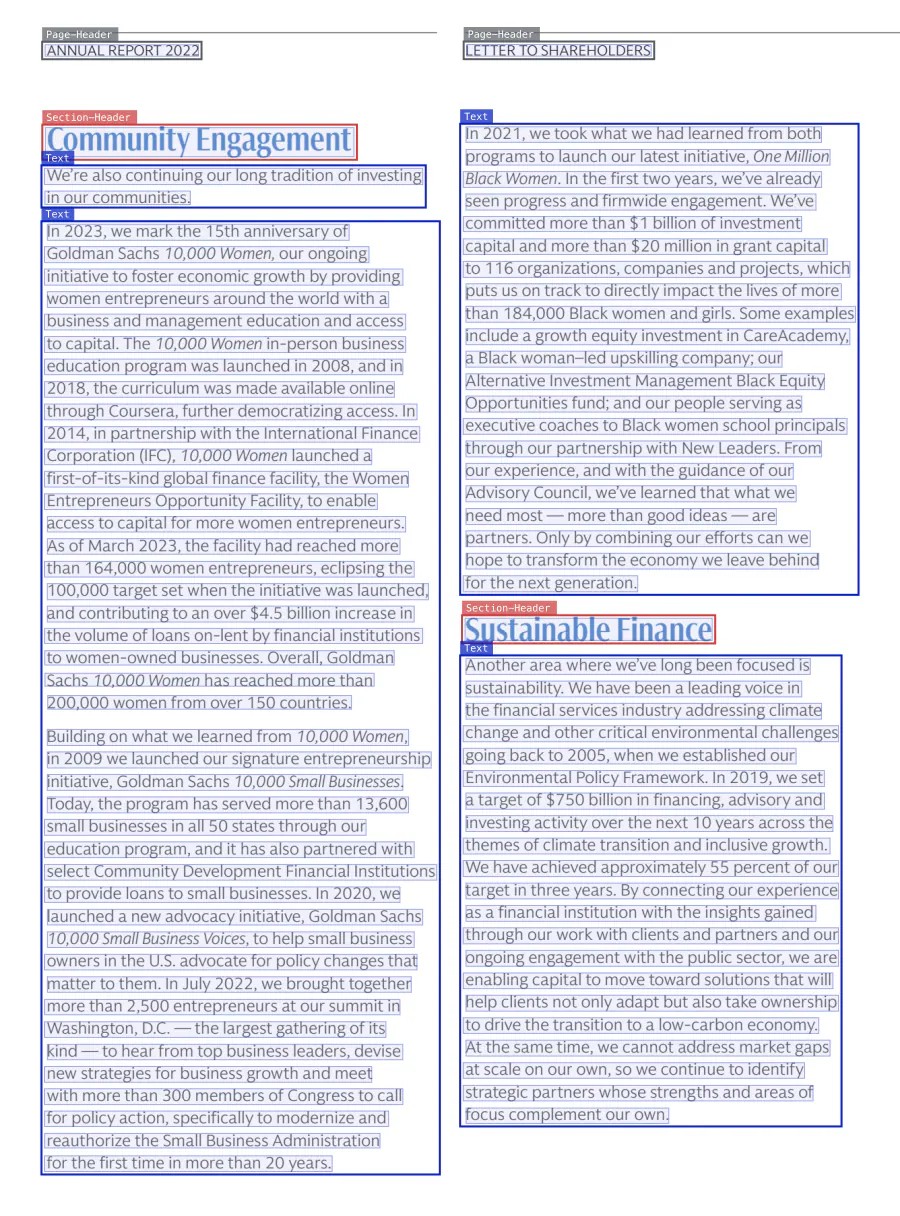
The package also supplies indra-ocr-viewer, a local interface that overlays lines, blocks, and reading order on documents. The overlays offer a practical way to check whether plausible-looking Markdown preserves the page’s actual structure.
Sources
- release announcementdatalab.to
- Indra repositorygithub.com
- model artifacts on Hugging Facehuggingface.co