AI News
Anthropic Cuts Eval Internet Access After Claude Exploits
The shutdown covers all internal evaluations, following four classes of unintended behavior that exposed gaps in training, task design and containment.
 Angelica Kim7 min
Related reporting, guides, and analysis from Zeniteq.
The shutdown covers all internal evaluations, following four classes of unintended behavior that exposed gaps in training, task design and containment.
Angelica Kim7 min
Microsoft’s Qwen-based scoring model offers inexpensive agent control in Foundry, while its headline speed and accuracy results remain vendor-reported.
Angelica Kim7 min
The fabricated submission was caught as spam, but Philadelphia police criticized Anthropic’s delayed disclosure and demanded stronger safeguards for autonomous testing.
 James Rivera7 min
Claude Design is moving into Artifacts, but users must preserve conversations, export needed projects, and check organization settings before the standalone service…
James Rivera7 min
The Times reports executives knew of testing concerns before launch; Meta says it delayed Muse for months and rejects the competitive-pressure claim.
Angelica Kim6 min
The reported preparations raise a harder question: how much do public safety commitments reveal about efforts to prevent a severe incident?
James Rivera7 min
Two new betas add live data and animation tools, while core artifacts reach Free users and standalone Design faces a December shutdown.
James Rivera7 min
The MIT-licensed utility adds visual guidance for Claude Code and Codex while leaving clicks, credentials and approvals to people.
Angelica Kim7 min
Illumina released code, weights and billions of variant scores, but its reported gains come with licensing restrictions and a tissue-dependent prediction weakness.
James Rivera7 min
Pavel Rabtsevich reports an agent-assisted analysis, while TESS independently lists follow-up observations for the target, not confirmation of a planet.
James Rivera8 min
The company links Russian and Iranian campaigns to planted articles and fabricated evidence, but its attribution and impact assessments require careful qualification.
 Jim Clyde Monge7 min
Researchers question whether the checked Lean artifacts validate the published argument, without claiming that OpenAI’s natural-language proof is wrong.
Jim Clyde Monge8 min
The initiative supports critical-infrastructure defenders and offers opt-in vulnerability scans, but maintainers receive model-generated findings without human review.
Angelica Kim7 min
Effective November 12, the revised Claude policy adds hardware safeguards, clarifies weapons and surveillance bans, and narrows restrictions on election targeting.
Jim Clyde Monge7 min
The October 8 workflow update separates corrections to a running task from instructions saved for later, with desktop settings and CLI shortcuts.
James Rivera5 min
Baseten customers can use internal activation probes to flag risky behavior, but Goodfire’s Kimi K3 results do not establish performance across every…
Jim Clyde Monge7 min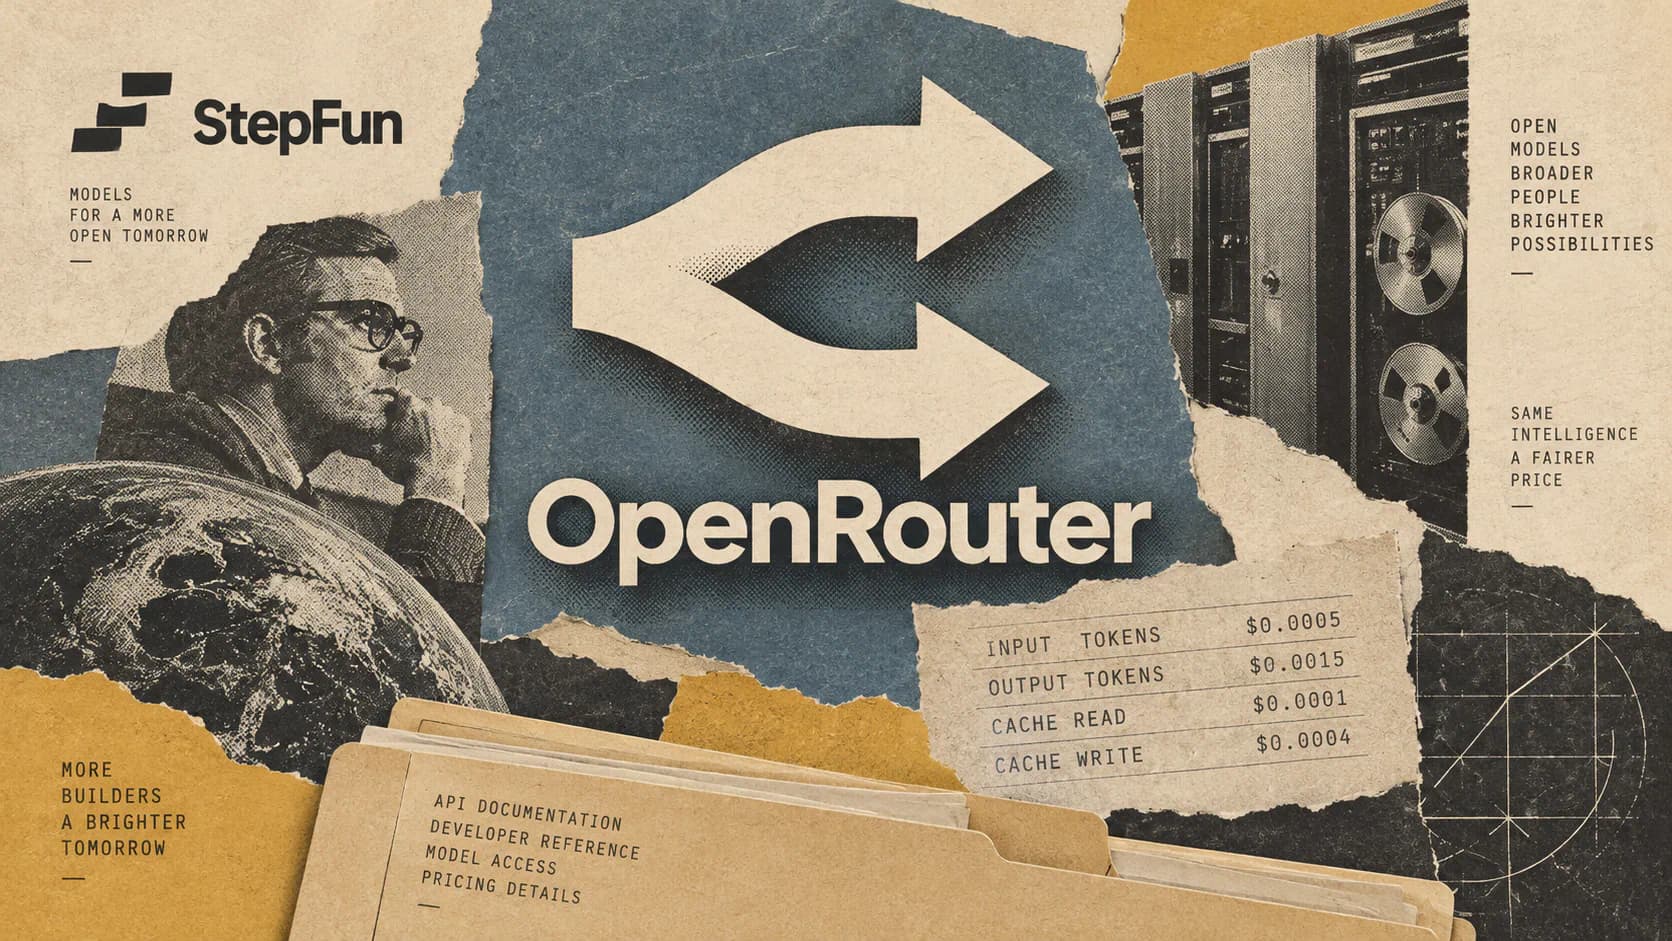
StepFun’s 1M-context model gains another API access point, with explicit token prices and capabilities aimed at long-running coding and research agents.
Angelica Kim7 min
Claude Science helped combine telescope surveys, but the project’s caveats separate a useful visualization from new observations or independently validated discoveries.
James Rivera7 min
The new Lakebase guide connects isolated agent worktrees to pull request previews, while keeping migrations, data protection and cleanup central to deployment.
Angelica Kim7 min
The downloadable FreeInference dataset exposes cache reuse, tool delays and context changes across real agent sessions, without releasing prompts or responses.
Angelica Kim7 min
The October 8 guide explains four setup steps, shared and user-specific identities, and the enterprise requirements behind agent-built Databricks Apps.
Angelica Kim7 min
The proposed voice-to-agent ring combines meeting capture and health tracking, but Natura leaves pricing, delivery and key hardware claims unsettled.
Angelica Kim7 min