Mistral Large 4 Launches Before Its Open Weights Arrive
The trillion-parameter LLM is available through a public API preview, with downloadable weights promised for late October after cybersecurity testing.
Listen
AI narration
12:53
0:00 / 12:53
AI SummaryGenerated from this article
Mistral launched a public API preview of Large 4, its largest model to date with one trillion total parameters and 49 billion active parameters, on October 6. The company promised to release downloadable weights by the end of October 2026 after conducting cybersecurity red-teaming with vetted partners and state authorities.
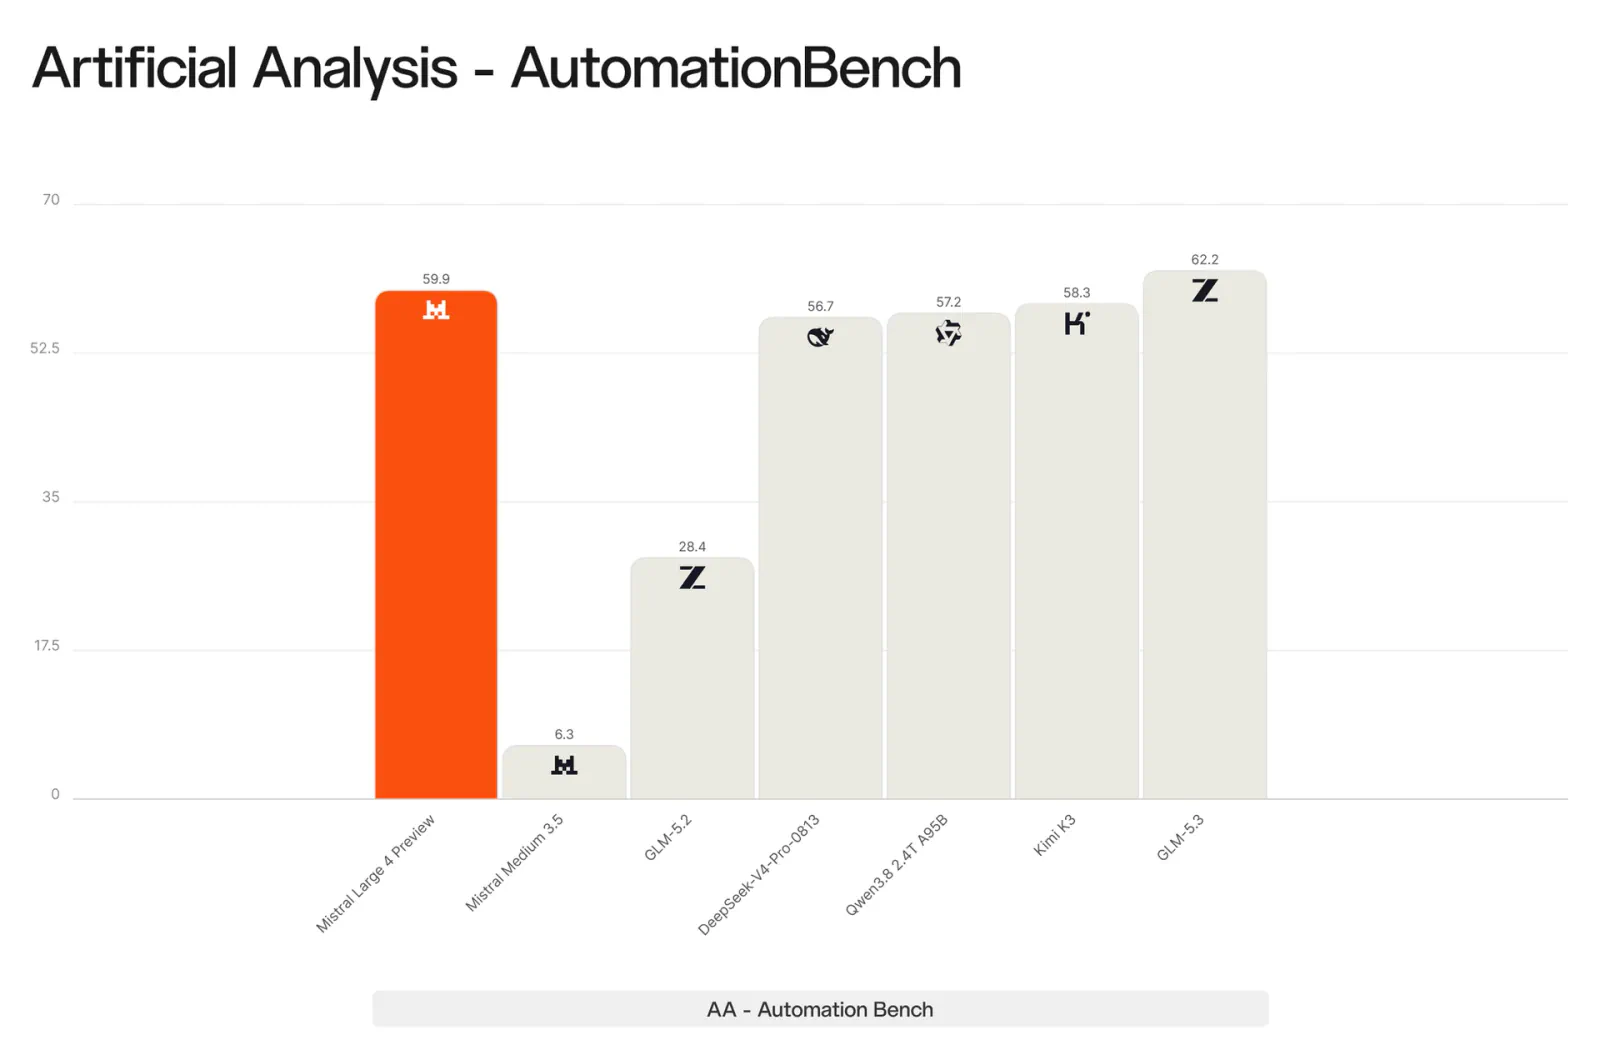
Large 4 is a natively multimodal mixture-of-experts model positioned for coding, tool-using agents, visual understanding, and enterprise work. Mistral reports 59.9% on AutomationBench, 61.7% on DeepSWE v1.1, and 28.3% on Terminal-Bench 4, though these are company-reported evaluations requiring independent validation. The model was trained on 3,800 NVIDIA Grace Blackwell GPUs in European data centers. API preview pricing is $1.36 per million input tokens and $4.18 per million output tokens through Mistral Studio and Vercel's AI Gateway.
Mistral Large 4 is available to developers now, but its weights are not. In its October 6 announcement, Mistral launched a public API preview of its largest model to date and promised to release downloadable weights by the end of October 2026.
That distinction matters. The preview lets developers evaluate the model through a hosted service. The promised weight release would give organizations a path to operating it themselves, subject to licensing terms that Mistral has not yet disclosed.
Large 4 is a natively multimodal mixture-of-experts model with one trillion total parameters and 49 billion active parameters. Mistral is positioning it for coding, tool-using agents, visual understanding, and specialized enterprise work. Cybersecurity receives particularly strong emphasis, including an argument that defenders need models they can run under their own policies rather than depend on a provider’s changing refusal rules.
The release is consequential, but the evidence is uneven: API availability is concrete, self-hosting remains a promise, and the performance comparisons still need broader independent validation.
API Access Is Live; Self-Hosting Must Wait
Developers can try the preview through Mistral Studio. Mistral lists preview API prices of $1.36 per million input tokens and $4.18 per million output tokens. Those are hosted inference prices, not estimates of what operating the eventual downloadable model will cost.
Vercel’s AI Gateway announcement provides a second access route. Developers can call mistral/mistral-large-4 through the AI SDK or supported interfaces including OpenAI-compatible Chat Completions, Responses, and Anthropic Messages APIs, without creating a separate Mistral account.
Gateway availability does not change the model’s release status. Although Vercel describes Large 4 as open-weight, Mistral’s announcement makes clear that the weights are scheduled for later this month. It is more accurate to describe today’s product as a public preview of a model intended for an open-weight release.
Until then, Mistral says it is conducting real-world red-teaming with cybersecurity leaders, vetted partners, and state authorities. Those participants receive access with reduced moderation and expanded cyber capabilities, unlike the guarded public endpoint.
For enterprises, these are two separate evaluation stages. Teams can test application behavior now; they cannot yet assess the downloadable artifact, its final license, or the practical requirements of self-hosting.
Work with Zeniteq
Let’s work together
We’re open to thoughtful collaborations with teams building in AI. Explore the ways we can work together.
One Trillion Parameters Does Not Mean One Trillion Active
Large 4’s headline size describes its total parameter count. Its mixture-of-experts, or MoE, design activates a smaller portion of the model during processing: 49 billion parameters, according to Mistral.
In an MoE system, routing mechanisms direct work through selected expert components rather than using every parameter for every token. That allows a model to maintain a large pool of learned capacity without performing the computation of an equivalently sized dense model on each token.
It does not make a trillion-parameter model small to deploy. Storage, memory, interconnects, serving software, and the placement of experts still matter. The active count helps explain computational efficiency, but it is not a hardware specification or a guarantee of cheap inference.
The increase over Large 3 is also worth separating into two dimensions. Vercel’s Large 3 release notice listed 675 billion total parameters and 41 billion active. Large 4 therefore expands the total model considerably while making a smaller increase in active parameters.
That is an architectural comparison, not proof of a proportional quality improvement. Mistral says fuller architecture and post-training details will accompany the weights. Until then, the parameter counts explain the design’s broad shape, not its complete operating characteristics.
Multimodal Understanding Meets Tool-Using Agents
Mistral’s multimodal pitch centers on understanding images alongside text, particularly in complex documents, charts, engineering drawings, and geospatial imagery. The announcement does not establish that Large 4 generates images, audio, or video, so “natively multimodal” should not be read as support for every modality.
The more useful enterprise proposition is combining visual interpretation with agentic behavior. A model could inspect a technical drawing, zoom into a relevant region, use tools to investigate, and check its conclusion. Mistral presents demonstrations of such workflows, but demonstrations do not establish reliability across unfamiliar production data.
The company reports 59.9% on AutomationBench, which it describes as 657 business workflows across applications including Gmail, Google Sheets, Slack, and Salesforce. For software engineering, it reports 61.7% on DeepSWE v1.1 and 28.3% on Terminal-Bench 4.
Those are Mistral-reported evaluation results. Their practical relevance depends on the agent framework, tool access, execution environment, and testing budget, not only the underlying LLM.
Visual grounding illustrates why narrow comparisons need care. Mistral reports 42% on Dense 200 against 41% for GPT-6 Astra. Visual grounding involves locating the content referred to in an image. A one-percentage-point lead on that task supports a specific comparison under the reported conditions, not a conclusion that Large 4 is generally better at vision.
Cybersecurity Is Both the Sales Pitch and the Release Constraint
Mistral gives cybersecurity unusually prominent treatment. Its argument is that legitimate defensive work often requires reproducing vulnerabilities, analyzing suspicious code, or demonstrating an exploit before fixing it. A provider’s safety filters can interrupt those tasks, even when the organization performing them has authorization.
The company’s cybersecurity results include a reported top-five position on the Artificial Analysis Cyber Index. Mistral describes that index as an independent evaluation of finding and fixing security flaws in real software. It also reports an 82% score on a vulnerability-reproduction-and-patching test and 93% on Cybench, a set of 40 security competition challenges.
These should be distinguished carefully. The index is presented as a third-party evaluation, but the results here are being relayed through Mistral’s announcement. Other capability claims, including usefulness for malware analysis, vulnerability prioritization, and writing detection rules, come from Mistral’s internal testing. They are not equivalent forms of evidence.
Mistral also attributes some competing closed models’ low scores on the vulnerability test to refusals. That complicates the comparison. A model that declines a task may score worse without necessarily lacking the technical capability to complete it. The evaluation captures both capability and willingness under the tested safety policy.
For defenders, that combination can be operationally important. It also creates dual-use risk: capabilities useful for proving and fixing a vulnerability can help someone seeking to exploit it.
TechCrunch’s reporting reinforces that the current release is guarded rather than downloadable. The remaining red-team period is therefore central to the story, not an incidental delay. Mistral still needs to explain how its eventual license, release policy, and safety findings address the tension between defensive autonomy and potential misuse.
The Sovereignty Pitch Has a Concrete Infrastructure Basis
Mistral says it trained Large 4 from scratch on 3,800 NVIDIA Grace Blackwell GPUs in its own European data centers. It says the public preview runs on that same infrastructure.
That provides a more concrete basis for its sovereignty pitch than the model’s European origin alone. Mistral describes a European deployment operated end-to-end by the company, independently of other digital service providers and under European law. It also plans availability across multiple regions.
The training data included more than 160 languages, according to Mistral, including every official European Union language. That describes multilingual training coverage; it does not establish equal performance across those languages.
For buyers, several forms of control need separate scrutiny. A European hosted endpoint concerns where inference runs and who operates it. Downloadable weights concern whether an organization can retain and serve the model itself. Licensing determines what it may legally do with those weights. None automatically resolves every compliance, security, or procurement requirement.
Large 4 could offer an alternative to both Chinese open-weight models and closed U.S. services, but that alternative is not fully available today. The API enables evaluation. The pending weights and license determine how much deployment independence customers actually gain.
The Weight Release Will Be the More Revealing Milestone
Mistral’s announcement makes an ambitious case for Large 4 across cybersecurity, coding, finance, law, and multimodal work. It cites evaluations involving Artificial Analysis, Surge AI, and vals.ai alongside its own testing. Those third-party contributions are useful evidence, but they are not the same as broad independent reproduction of the model’s performance.
The missing details matter: evaluation configurations, tool scaffolding, inference budgets, safety settings, and the final model version can all affect comparisons. Mistral also says the preview continues to improve, so results obtained now may not describe the eventual weight release exactly.
The sensible near-term use is to test Large 4 against real organizational workloads rather than purchase decisions based on a leaderboard position. Cybersecurity teams should pay particular attention to authorized task completion, refusal behavior, auditability, and failure modes. Other enterprises should examine document accuracy, tool-use reliability, latency, and total workflow cost.
The end-of-October release will test Mistral’s strongest promise: that frontier-level capability can come with meaningful operational control. Downloadable weights alone will not settle that question. A usable license, adequate technical documentation, reproducible evaluations, and a workable deployment path will determine whether Large 4 becomes a sovereign AI option or remains chiefly an impressive hosted preview.