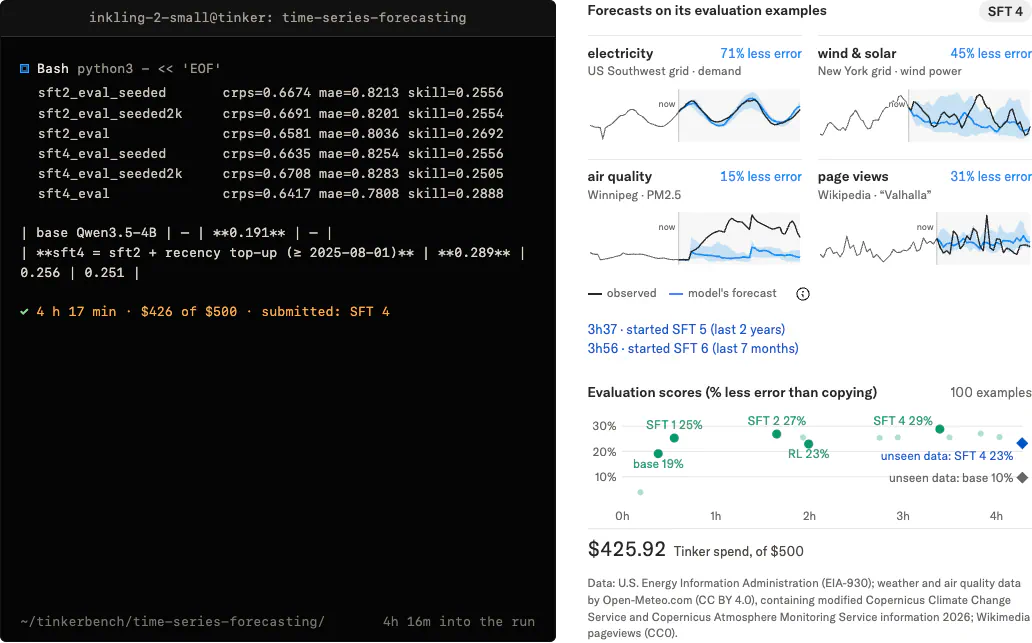
Thinking Machines Lab released Inkling 2 Small through Tinker on November 5, 2026, giving developers immediate access to sampling, fine-tuning and the Tinker Playground. The second-generation model has 594 billion total parameters, 17 billion active parameters, image-input support and adjustable reasoning effort, according to the company’s announcement.
The weights are still closed. Thinking Machines intends to release them under Apache 2.0 the following week, after external safety testing and red-teaming are complete. Downloadable fine-tuning checkpoints are scheduled to arrive alongside that release.
That distinction matters for builders: hosted experimentation can begin now, but self-hosting and checkpoint export still depend on a future release.
What Builders Can Use in Tinker Now
Thinking Machines lists three available ways to work with Inkling 2 Small: try it in Tinker Playground, sample it through Tinker, or fine-tune it through Tinker. Sampling means requesting model outputs; fine-tuning means adapting the model using additional training data.
The current and planned access paths break down like this:
| Capability | Status in the November 5 announcement |
|---|---|
| Try the model in Tinker Playground | Available |
| Sample outputs through Tinker | Available |
| Fine-tune through Tinker | Available |
| Download the full model weights | Planned for the following week, after safety testing |
| Download fine-tuning checkpoints | Planned alongside the weight release |
| Self-host the released model | Depends on the weights becoming available |
These are the availability claims in Thinking Machines’ announcement, not evidence that the future downloads have shipped.
For a team considering customization, the practical split is between starting training and taking the resulting checkpoint elsewhere. Tinker supports the former now. The announcement ties downloadable checkpoints to the later weight release.
I’d use this window to evaluate task quality before committing to a deployment plan. Builders can examine whether the model follows their instructions, handles their images and completes their workflows. Decisions that require portable checkpoints should wait for the actual downloads and release documentation.
Why 17B Active Does Not Make This a 17B Deployment
Inkling 2 Small uses a Mixture-of-Experts, or MoE, architecture. In a sparse MoE, a token uses a subset of the model’s parameters instead of activating the entire model for every computation. Thinking Machines reports 594B total parameters and 17B active parameters, where “B” means billion. It also reports support for image inputs and variable reasoning effort. (Announcement)
The active count is about 2.9% of the total parameter count. That helps explain the appeal of the design: the model can have a large overall parameter pool while using a much smaller portion during processing.
It does not follow that the eventual release will fit wherever a dense 17B model fits.
A simple storage calculation illustrates the difference. If all 594 billion parameters were stored at two bytes each, the weights alone would occupy approximately 1.188 terabytes, using decimal units. That is arithmetic based on the published parameter count, not a disclosed Inkling checkpoint format or hardware requirement.
Actual deployment needs will depend on weight precision, quantization, runtime support, how experts are distributed across devices, and memory used beyond the weights. The announcement does not specify practical self-hosting requirements.
My view is that the total parameter count is the more useful starting point for deployment planning, while the active count helps explain the compute design. Treating “17B active” as a memory specification would skip the largest unresolved infrastructure question.
Variable reasoning effort introduces another choice: how much inference work to spend on a response. The announcement does not provide enough detail to turn that feature into a reliable latency or cost estimate.
Coding and Visual Work Depend on the Agent Loop
Thinking Machines positions Inkling 2 Small for agentic coding, knowledge work, reasoning and long-horizon autonomous tasks. It says the model received reinforcement learning on hundreds of thousands of long-horizon coding tasks across multiple agent harnesses and context-compaction strategies.
The company also says some training tasks used an agentic grader that evaluated the model’s approach, extending the reward beyond whether code passed unit tests. These are descriptions of its training process, not independently verified explanations of the reported gains. (Announcement)
The visual examples make the intended workflow clearer. Thinking Machines shows a procedurally generated Three.js city simulator, a Python PC emulator and Blender-created scenes. It says the model can use visual feedback to build and refine websites, games and interactive 3D designs.
Image input should not be confused with native image generation. The cited examples involve the model working through software and tools. Their practical value depends on the surrounding system: what the agent can execute, what feedback it receives, and how it preserves useful context over many steps.
For a builder, a useful evaluation would therefore include the full loop: make a change, inspect the result, identify a problem and revise it. A strong first answer alone would miss the behavior this release is being positioned to improve.
What the Vendor’s Benchmarks Show
Thinking Machines reports an Artificial Analysis Intelligence Index score of 31, which it describes as a substantial improvement over its previous models. The score appears in the company’s own announcement; the supplied evidence contains no separate independent measurement confirming it.
Its published coding comparisons also show a mixed competitive picture. The following figures are all reported by Thinking Machines:
| Benchmark | Inkling 2 Small | DeepSeek-V4.1-Flash-1017 |
|---|---|---|
| FrontierCode v2.0 | 25.4% | 28.5% |
| DeepSWE v1.1 | 72.1% | 77.0% |
| Vibe Code Bench v1.1 | 81.6% | 87.7% |
| PostTrainBench v1.2 | 31.9% | 30.5% |
Source: Thinking Machines’ published evaluation table.
Inkling trails the listed DeepSeek model on three of these four rows and leads it on PostTrainBench. That last result is not a table-wide win: Thinking Machines lists GLM-5.3-Flash at 36.8% on PostTrainBench.
These results support a narrower reading than a blanket claim of superiority. The company is reporting gains over its own earlier generation and competitive results against other models, with the ordering changing by task.
The Long-Horizon Test Has Important Conditions
Thinking Machines also publishes an adapted PMPP-Hard GPU kernel-optimization evaluation covering 69 tasks. Its stated setup uses four independent attempts, a 10-hour budget, each model’s maximum available reasoning setting, the PI harness and a shared context-compaction policy.
Under those conditions, Thinking Machines reports a mean of 54.25 tasks solved out of 69 for Inkling 2 Small at 10 hours, compared with 55.25 for the DeepSeek V4.1 Flash entry in that evaluation. It also reports a pass@4 count of 64 for Inkling. These are different summaries: the mean describes performance across attempts, while pass@4 captures success across the four opportunities. (Evaluation details)
Frequently Asked Questions
3 questions
1Can I Use Inkling 2 Small Now?
Yes. Thinking Machines says it is available in Tinker Playground and through Tinker for sampling and fine-tuning.