A request asking for the capital of France returned “violin violin violin violin violin violin” in a test reported by Chainguard. The response arrived as a normal success, and the company says nothing was logged to indicate a problem.
A cross-request state-management flaw in vLLM caused the failure. One client’s restriction on which tokens the model could generate could remain in shared serving state and constrain another client’s answer. No misleading prompt was needed.
Chainguard’s October 13 disclosure describes the issue as the first public finding from its Mythos-based vulnerability-hunting harness. The vLLM security advisory lists versions below 0.31.0 as affected and 0.31.0 or later as patched.
Operators should upgrade, especially where mutually untrusted clients share an inference engine. The disclosure concerns a specific, patched infrastructure flaw and is separate from the Chainguard Harness product offering.
How One Request’s Token Restriction Reached Another
vLLM is an open-source engine for LLM inference and serving, with features including continuous batching of incoming requests. The vulnerability affects its V1 worker’s handling of request-specific token restrictions.
A request can supply allowed_token_ids, a list of tokens the model is permitted to generate. This is useful when an application wants a tightly constrained answer, such as a response drawn from a fixed vocabulary.
Internally, vLLM represents those restrictions in a shared mask table, with rows associated with running requests. The advisory identifies the failure in InputBatch.condense, which moves request state as the batch changes.
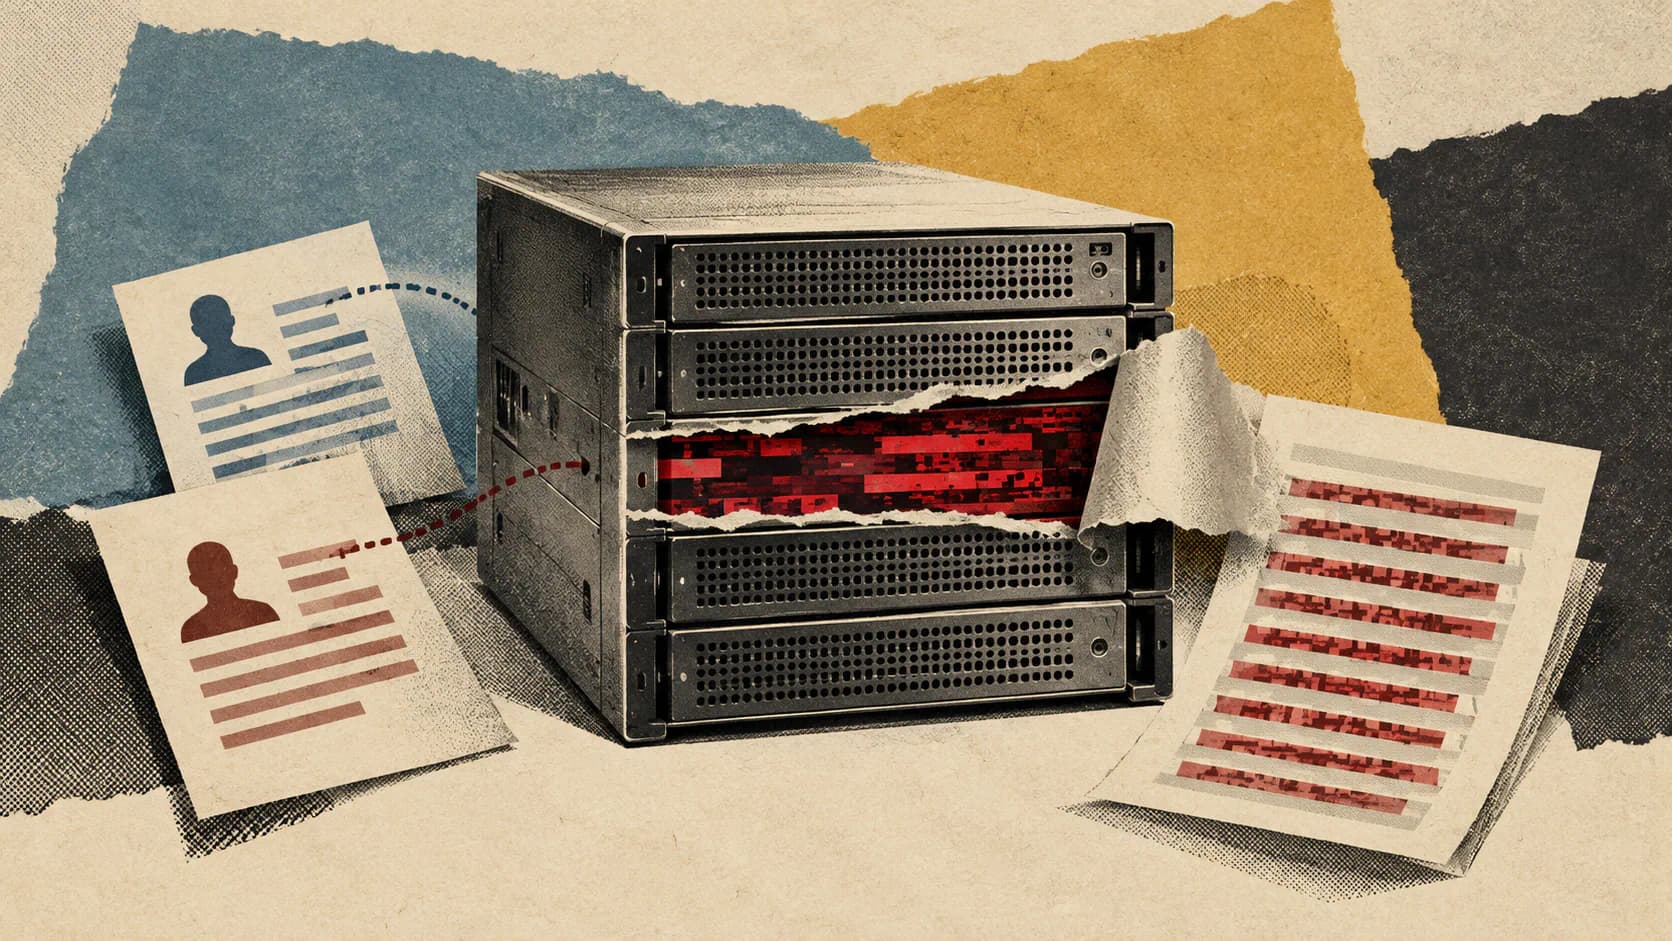
When a constrained request moved, vLLM copied its token mask to another row but failed to clear the source row. A later request could reuse that row. If the incoming request did not specify its own allowed_token_ids, the request-addition code did not overwrite the stale restriction.
Under the required concurrent-batching conditions, that leftover mask reached the sampling process. The new request then generated tokens according to another client’s allowlist instead of its own unrestricted settings.
Chainguard describes keeping a long-running request active with an allowlist containing exactly one token. If another request landed on the stale row while the constrained request remained active, its output could be limited to that token.
The advisory calls this vocabulary steering: an attacker can constrain the available tokens, but the disclosed flaw does not provide general control over an entire response or allow unrestricted replacement with arbitrary attacker-written text.
The patch clears the vacated mask row. The advisory also identifies a related fix for mask aliasing in InputBatch.swap_states.
A Low Severity Rating Does Not Make Corrupted Answers Harmless
vLLM rated the issue Low, with a CVSS score of 3.7. The advisory assigns high attack complexity because exploitation requires concurrent requests and a particular batch-slot reuse condition while the attacker’s constrained request remains active.
The attack also has important limits. Chainguard says the attacker cannot choose the victim or see the victim’s prompt or response. The advisory identifies an integrity impact, with no confidentiality or availability impact. The findings do not establish prompt theft, model-weight access or a general ability to take over the serving process.
In Chainguard’s demonstration, however, the victim received an HTTP-successful answer without an error indication. An application checking only whether inference completed successfully could therefore accept a corrupted result.
A repeated word is conspicuous to a person. A constrained answer inside an automated workflow may be less obvious. Chainguard highlights moderation checks, classifiers and numerical outputs as possible downstream consumers. A small vocabulary can be legitimate in those settings, making an incorrectly imposed restriction harder to distinguish from an ordinary answer.
Those downstream consequences are risk scenarios, not demonstrated compromises of specific applications. The published evidence establishes cross-request token restriction and a successful-looking response.
Chainguard reports reproducing the issue three times in three attempts. That supports reproducibility in its test setup; it does not establish a universal success rate across deployments or show that an attacker can reliably select a particular customer.
Upgrade, Then Review the Shared Serving Boundary
The highest exposure is where clients outside an operator’s control can submit requests to the same engine. Chainguard specifically points to hosted APIs and multi-tenant platforms.
If only trusted internal services can reach an engine, the attack would require access through an insider or compromised service. A deployment without a separate client to target does not present the same cross-client scenario, but Chainguard recommends upgrading regardless.
Operators should address both the patched bug and the conditions that make cross-client interference possible.
- Upgrade to vLLM 0.31.0 or later. This is the stated patched baseline. Confirm the version actually running in serving workers; a dependency update may not yet have reached production.
- Separate mutually untrusted clients. Chainguard recommends giving untrusted clients their own engines and says vLLM does not provide tenant isolation within a single process. Fixing this particular row-clearing bug should not be treated as proof that sharing a process creates a strong security boundary.
- Authenticate and restrict traffic through a gateway. Expose only the routes the application needs, and apply authentication consistently before forwarding requests.
- If an upgrade must wait, block the attack input where possible. Chainguard recommends rejecting or stripping
allowed_token_idsfrom untrusted requests when applications do not need the feature. That is a temporary mitigation for this output-corruption path, not a replacement for patching.
Both the disclosure and advisory identify a gap in authentication coverage: the SageMaker-compatible /invocations route sits outside the protection of vLLM’s --api-key checks. If that route is reachable, setting an API key elsewhere does not necessarily prevent an unauthenticated client from submitting the traffic needed for this flaw.
Actual exposure depends on routing, network access, request handling and batching behavior. Operators should not assume that an authenticated /v1 endpoint means every inference route is protected.
Detection also needs more than error monitoring. Where completion records are available, Chainguard recommends checking for answers that ignore their prompts and repeat a single token or stay within an unusually small vocabulary. Such patterns can guide investigation, but they are not conclusive evidence of exploitation: constrained output can also be intentional.
A dashboard showing healthy HTTP responses would not, by itself, reveal the demonstrated failure.
Sources
- Chainguard’s October 13 disclosurechainguard.dev
- vLLM security advisorygithub.com
- vLLMgithub.com
- Chainguard Harness product pagechainguard.dev