AWS is giving PyTorch developers a new device target: neuron. Its announced TorchNeuron backend lets supported models run on Trainium2 and Trainium3 using familiar PyTorch execution, compilation, and distributed-training APIs.
AWS is trying to reduce the engineering work involved in moving AI workloads away from Nvidia hardware, where CUDA-specific code and established workflows can make switching expensive. This is a software-ecosystem announcement, not a new chip launch.
Announced on October 19, TorchNeuron is scheduled for an Apache 2.0 public-beta release on October 20 at PyTorch Conference North America. Until that release happens, it remains an announced beta, not generally available software.
The technical scope is substantial: eager execution, torch.compile, distributed APIs, profiling, and custom kernels. AWS’s “no rewrite” message still needs boundaries. Broad PyTorch compatibility does not mean every operator, numerical format, attention implementation, or CUDA-dependent extension will work unchanged.
Trainium Becomes a Native PyTorch Device
According to the TorchNeuron launch post, the backend registers Trainium through PrivateUse1, PyTorch’s official extension point for custom hardware. It also integrates with the device-agnostic torch.accelerator APIs.
Developers can therefore address Trainium through PyTorch’s own device and execution abstractions, without treating it as a separate destination requiring a different model-programming workflow.
The announced public-beta scope includes:
- Hardware: Trainium2 and Trainium3.
- Execution: Native eager mode and
torch.compile, plus experimental adaptive eager execution. - Data types: BF16, FP32, FP16, integer types, and boolean types.
- Framework APIs: Standard neural-network, tensor, mixed-precision, distributed, and profiling interfaces.
- Lower-level optimization: Custom operators through the Neuron Kernel Interface, or NKI.
“Native” describes integration with PyTorch. TorchNeuron still depends on the Neuron backend, compiler, and Trainium execution infrastructure; much of that hardware-specific work sits below the application-facing APIs.
The Apache 2.0 release is also distinct from hardware access. Open-source backend code does not remove the need to provision supported Trainium capacity and configure a compatible environment.
What Developers Actually Change
For a model written against ordinary PyTorch operations, AWS illustrates device selection with:
model = MyModel().to("neuron")
The launch post says modern code using torch.accelerator can run unmodified. Code that explicitly selects another device needs its placement logic changed.
Compiled execution adds a backend choice:
model = MyModel().to("neuron")
compiled_model = torch.compile(model, backend="neuron")
Alternatively, developers can set torch.compiler.set_default_backend("neuron") once before compilation and use subsequent compilation calls without a backend argument.
These examples cover execution, not a complete migration. A working application must place its inputs and other relevant tensors on the correct device, establish its software environment, and check that its operations are supported.
The useful distinction is between device selection and hardware assumptions. A model expressed through supported, device-agnostic PyTorch APIs is the strongest candidate for a small change. An application containing explicit CUDA calls, Nvidia-specific extensions, or custom GPU kernels has additional work to assess.
Changing the model’s device does not make those dependencies portable. NKI provides a route to implement or optimize custom operators for Trainium, though an existing CUDA kernel cannot be assumed to execute unchanged.
For developers considering a move, the first task is an inventory: which parts of the application are standard PyTorch, and which depend on a particular accelerator?
Eager Mode Preserves Debugging, Not Performance Parity
TorchNeuron supports PyTorch’s eager workflow, where operations execute as Python reaches them. The launch post says developers can use Python control flow, print statements, and breakpoints without first tracing or compiling an entire model.
Researchers debugging a new architecture can keep that familiar workflow. Requiring every experiment to begin with adapting the model to graph capture would make a hardware platform harder to adopt.
Ordinary eager mode does carry performance costs. TorchNeuron compiles operations individually into Neuron Executable File Format files, launches them on the device, and moves intermediate results through high-bandwidth memory. Whole-graph optimization can reduce those costs.
AWS is also introducing experimental adaptive eager mode, intended to reduce launch overhead and create more opportunities to fuse operations while retaining an interactive workflow. It remains experimental and offers no guarantee of compiled performance.
For production-oriented execution, torch.compile captures a graph that the Neuron compiler can optimize. The documented path uses TorchDynamo, AOTAutograd, Torch-MLIR, and StableHLO before producing a Trainium executable.
Developers can begin with familiar debugging tools, then evaluate compilation. Successfully running a model in eager mode establishes compatibility for that workload, without establishing its eventual throughput or cost.
Compatibility Extends Beyond a Single-Device Demo
The announced coverage includes the infrastructure needed to train larger models, beyond moving an isolated tensor to Trainium.
AWS lists support for DistributedDataParallel, FSDP2, SimpleFSDP, tensor parallelism, and pipeline parallelism. DTensor and DeviceMesh provide the abstractions for tensor sharding and process-group organization. Collective operations such as all_reduce, all_gather, and reduce_scatter, along with point-to-point communication, are also supported.
Underneath those APIs, communication uses Trainium’s collective cores within a node and Elastic Fabric Adapter between nodes. The programming interface stays familiar while the transport is hardware-specific.
AWS says torch.profiler, together with Neuron Explorer, can trace execution from framework operations to hardware and connect events to source lines. That diagnostic path remains useful even when a model is portable: developers still need to investigate performance on the new hardware.
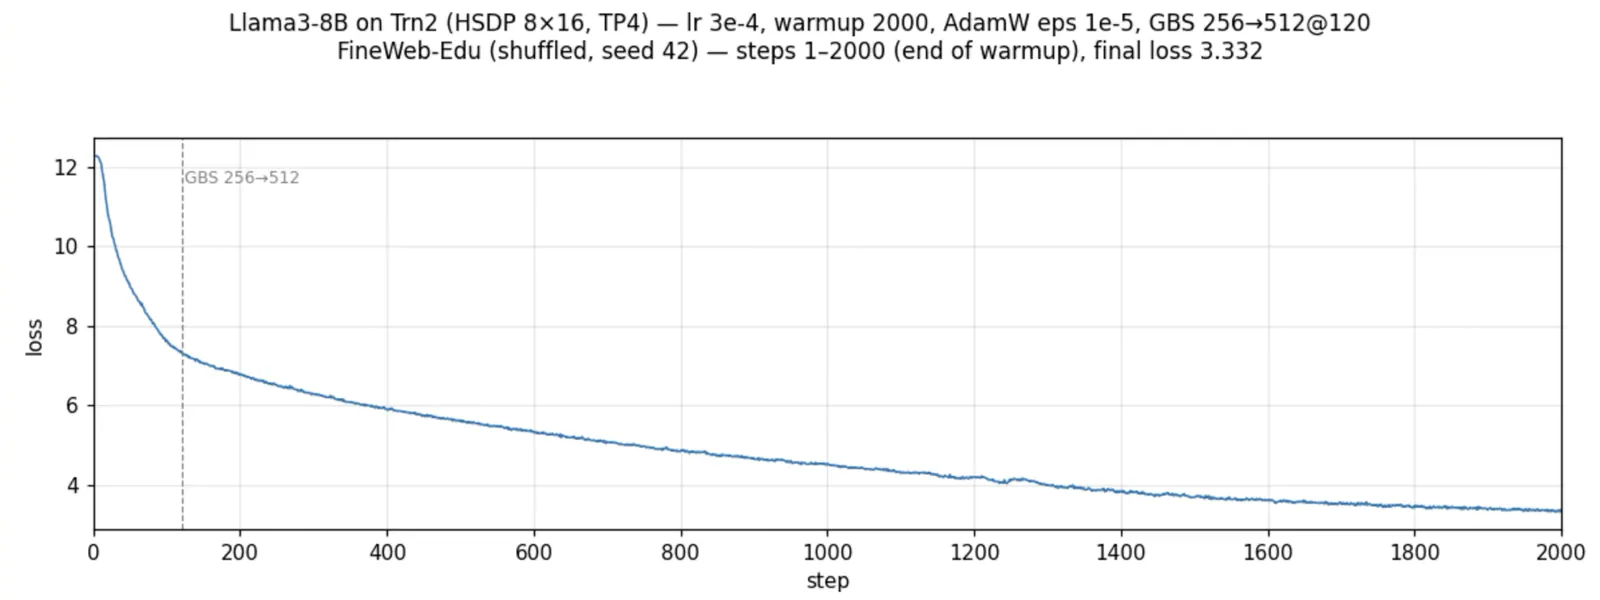
Operator coverage needs a closer look. AWS describes broad ATen support across language, multimodal, vision, diffusion, state-space, and world-model workloads, but does not promise that every implementation in those categories works.
The launch post names native FlexAttention support and Trainium-optimized NKI kernels for workloads including attention and mixture-of-experts models. Developers can use those paths where appropriate, while validating their exact architecture instead of inferring compatibility from a model-family label.
The First Beta Has Material Compatibility Limits
Check the first-release limitations before provisioning a migration experiment. The launch material lists unsupported features including sparse tensors, forward-mode automatic differentiation, arbitrary attention masks, and dynamic or symbolic shapes.
Sources
- scheduled for an Apache 2.0 public-beta releaseaboutamazon.com
- TorchNeuron launch postpytorch.org
- TechCrunch frames TorchNeurontechcrunch.com