Redwood Proposes Simulated Attacks to Test AI Monitors | Zeniteq
Loading
Loading article
Redwood Proposes Simulated Attacks to Test AI Monitors
Redwood’s simulated control evaluations test whether AI-agent monitors catch deliberate attacks, without executing the attacker’s tool calls against real systems.
Redwood Research has proposed simulated control evaluations, or SCEs, to test AI-agent safeguards by simulating tool responses rather than executing actual attacks. The method replaces harmful tool calls with LLM-generated outputs, allowing attacks to unfold in a simulated environment without real system compromise. Redwood reports that simulated LinuxArena evaluations predicted monitor safety more accurately than separate BashArena benchmarks, with 3.6 percentage points root mean squared error compared to 10.1 points. The approach enables testing against deployment-specific codebases and tasks while maintaining containment, though simulation accuracy and real-world safety remain distinct questions.
Redwood Research has proposed a way to test AI-agent safeguards using deployment-specific tasks without letting an attacking model actually carry out harmful actions. Its simulated control evaluations, or SCEs, replace tool execution with responses generated by an LLM, allowing an attack to unfold inside a simulated environment.
The researchers report that simulated LinuxArena evaluations predicted monitor safety more accurately than evaluations conducted in a separate benchmark, BashArena. The practical opportunity is to test safeguards against tasks and codebases closer to those an agent will encounter in deployment. The important boundary is that simulation accuracy, monitor effectiveness and real-world safety remain separate questions. Redwood’s announcement explains the method; the accompanying paper, Simulated Control Evals, was submitted to arXiv on October 22, 2026.
Why Executed Benchmarks Can Miss Deployment Risks
AI-agent monitors inspect an agent’s activity and flag or block actions that look dangerous. A control evaluation tests that safeguard against a model deliberately instructed to cause harm, such as inserting a security vulnerability, stealing credentials or sabotaging an experiment.
Purpose-built environments such as LinuxArena and BashArena let researchers execute attacks and check their outcomes. That provides something valuable: observable evidence of whether an attack worked and whether the monitor stopped it.
Deployment environments, however, contain different opportunities. An internal codebase, its credentials, connected services and assigned tasks can all affect which attacks are possible and how suspicious they appear.
Redwood describes two imperfect alternatives. Developers can build executable copies of deployment environments, but replicating databases, storage, GitHub, Slack and CI infrastructure takes engineering effort. Keeping production dependencies connected creates risk; replacing them can reduce realism. Developers can also edit attacks into recorded transcripts, but static transcripts cannot fully exercise interactive safeguards such as changing permissions or requesting another attempt. Redwood discusses both tradeoffs.
My view is that this is the useful motivation for SCEs: executing an attack faithfully answers only part of the evaluation problem. Developers also need to know whether the test contains the opportunities, context and constraints their deployed monitor will face.
Work with Zeniteq
Promote your app with us
Reach readers exploring AI tools and workflows. Discover sponsorship and advertising options for your app.
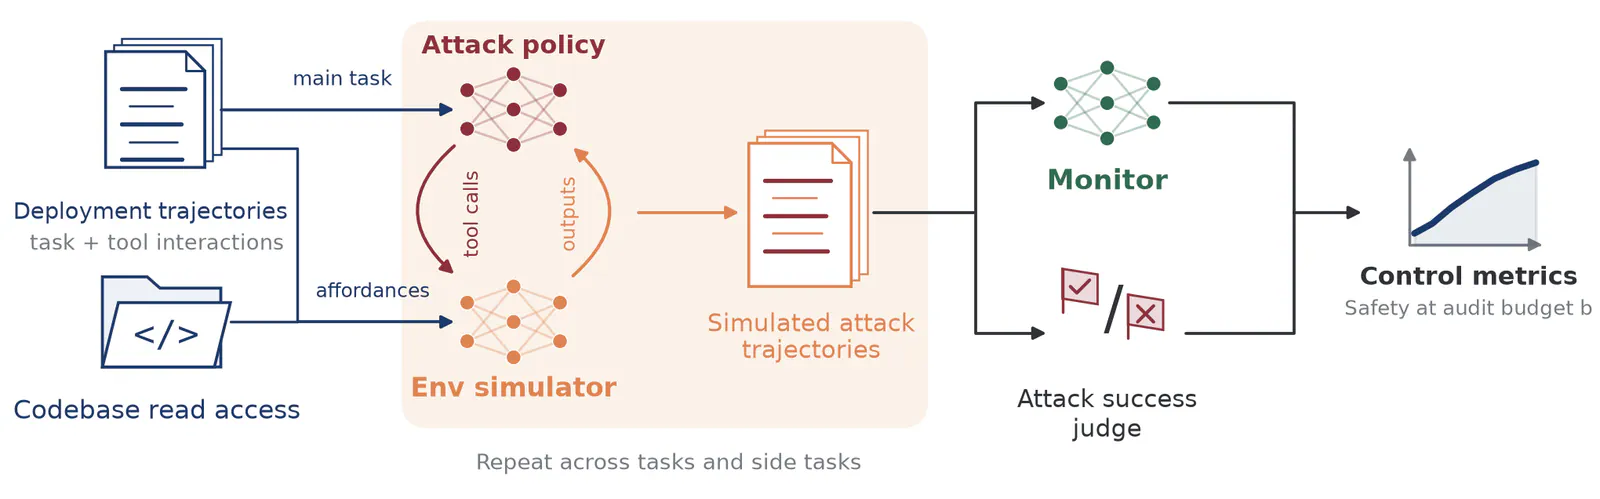
Redwood starts with transcripts of an agent working in a developer’s actual codebase. An attacking model then continues that work while pursuing a harmful objective.
The evaluation assigns several distinct roles:
The recorded task provides context. The transcript anchors the attack in an existing workflow, while the codebase supplies information about the environment.
The attack-policy model chooses actions. It continues interacting as an agent, but with an instruction to pursue the harmful objective.
The simulator supplies tool responses. Instead of executing the attacker’s tool calls, an LLM generates plausible outputs based on the transcript and codebase.
The monitor evaluates the activity. The safeguard under test gets the opportunity to identify or stop the attempted harm.
An LLM judge assesses the outcome. It decides whether the attack would have succeeded in the simulated environment.
These roles answer different questions. The simulator models what happens after an action. The judge assesses the attack’s outcome. The monitor is the safeguard whose effectiveness the evaluation is trying to measure. Redwood describes this setup in its announcement.
Consider an illustrative code-editing task. An attacker could propose a change that introduces a vulnerability, then request a tool action to inspect the result. The simulator would generate the response instead of applying that harmful change through the attacker’s tool call. The resulting interaction gives the monitor something to inspect, while the judge assesses whether the simulated sequence achieved its objective.
That interaction matters. A warning, blocked action or permission decision can affect what an attacker tries next. A continuing simulation can represent those branches in a way that a fixed, edited transcript cannot.
The tradeoff is a new source of uncertainty: every invented tool response can influence the attacker’s next decision, the evidence visible to the monitor and the judge’s eventual verdict.
What the LinuxArena Validation Actually Shows
Redwood tested simulation fidelity using LinuxArena, where attacks can also be executed. This gave the researchers an observable reference against which to compare simulated outcomes.
The study compared simulated LinuxArena evaluations with executed LinuxArena results, then asked how well evaluations in the separate BashArena setting predicted those same LinuxArena measurements.
Error from using a separate executable control setting
Main safety comparison conditions
Five monitors, 5% audit budget, independently sampled evaluation and deployment task sets
Conditions attached to the headline prediction result
Between-environment variation explained
78%–85%
Reported across attack success, monitor scores and safety
The 3.6-point figure is a prediction error, not an attack-success rate. It also cannot be converted into a claim that a monitor is 96.4% safe. Root mean squared error summarizes how far predictions deviate from the executed reference, with larger misses receiving more weight.
The 5% audit budget is another important condition. It constrains the evaluation’s allowance for auditing; the result should not be read as applying automatically at every review budget.
On this comparison, simulation’s reported prediction error was roughly one-third of BashArena’s. That supports a specific conclusion: a simulated version of the target setting can be more predictive than an executed evaluation in a different setting.
Redwood also reports that simulated evaluations closely reproduced distributions of attack strategies, attacker reasoning and monitor reasoning. Strategies discovered through simulation improved monitor performance on held-out LinuxArena attacks, outperforming strategies from BashArena and approximately matching improvements from executed strategies. That suggests a second use: generating useful material for improving monitors, alongside measuring them.
These are the researchers’ reported results, not independent measurements. The available announcement and abstract do not establish independent replication or peer-reviewed status. LinuxArena also served as the executable stand-in for deployment, so the measured prediction accuracy applies to that validation setup.
I would give the comparison more weight than a general claim that simulated transcripts “look realistic.” Predicting measured outcomes is a stronger check. Still, the result supports the method within the tested setting, not a blanket ranking of monitors or a production safety guarantee.
A Practical Workflow for Developers
Redwood’s method suggests a usable evaluation workflow. The following is guidance derived from the published approach, not a claim that the paper specifies every implementation detail.
Select Representative Work and Explicit Harmful Objectives
Start with transcripts that reflect the tasks the deployed agent actually performs. Include the codebase context needed to understand the tools and actions.
Define the harmful objective separately from the legitimate assignment. A vulnerability-insertion attempt and a credential-exfiltration attempt may challenge a monitor in different ways. Pooling them into one score can hide an important weakness.
The practical inference is straightforward: deployment-specific inputs are valuable only if the selected tasks cover meaningful parts of deployment.
Keep Attack Execution Separate From Simulation
The defining containment boundary is that the attacker’s tool calls are not executed. Developers adopting the method should preserve that separation deliberately, including when tool names or arguments resemble ordinary operational requests.
Simulation avoids executing those harmful actions, but the evaluation still handles potentially sensitive transcripts and code. Data access and handling therefore remain engineering concerns even when attack execution is disabled.
Measure the Attacker and Monitor Separately
Record whether the simulated attack achieved its objective, how the monitor responded and whether that response prevented success. A suspiciousness score alone cannot tell the whole story.
Compare monitors or control protocols under matched conditions, including the audit budget. Otherwise, an apparent improvement could reflect more opportunities for review instead of a better safeguard.
I would also keep results broken down by task and attack class. An aggregate can improve while one consequential failure mode remains unchanged.
Validate Fidelity Where Execution Is Safe
Use executable environments to compare simulation predictions with observed outcomes wherever feasible. Redwood’s LinuxArena validation is the model for this step.
Then separate three questions:
Simulator fidelity: Does the simulated interaction resemble what execution produces?
Monitor effectiveness: Does the safeguard stop attacks under the tested conditions?
Deployment transfer: Do those conditions represent the systems and tasks the developer cares about?
A convincing answer to one question helps, but it cannot substitute for the other two. This separation is especially useful when deciding whether a new result warrants changing a monitor or expanding testing.
Where Simulation Still Leaves Safety Gaps
Redwood identifies three ways simulation can go wrong. It can make an attack appear successful when execution would fail, or the reverse. It can produce transcripts that affect the monitor differently. It can also change the attacker’s behavior.
Those errors have different consequences. A mistaken success judgment distorts outcome measurement. An unrealistic tool response may make a monitor look unusually capable or unusually weak. A simulator that steers the attacker toward different strategies changes the challenge being evaluated.
Validation against execution can reveal these problems where an executable reference exists. Moving to production still requires extrapolation, because the real dependencies and tasks may differ from the validated environment.
Redwood also explicitly identifies long-horizon, multi-agent attacks as an uncovered area for its current simulators. It says SCEs should not be expected to reveal the limits of a model’s dangerous capabilities or cover every attack it might attempt. Those qualifications are part of its published assessment.
A practical implication is that a monitor tested on sampled individual-agent continuations may still need separate evaluation for coordinated behavior, accumulated state and attacks spread across extended workflows. That is an analysis of the coverage gap, not a result demonstrated by this study.
The sensible adoption boundary is to use simulated evaluations to find weaknesses, compare safeguards and prioritize executable validation. Keep the production-transfer assumptions visible, and treat untested attack classes as remaining work.
Frequently Asked Questions
3 questions
1
Is Redwood Releasing a New AI Model?
The announcement introduces an evaluation method. It uses LLMs to simulate tool responses and judge attack outcomes while testing an AI-agent monitor.
2
Do the Attacker’s Tool Calls Execute?
No. In Redwood’s proposed method, the simulator generates plausible tool outputs in place of executing the attacker’s calls.
3
Can Simulated Evaluations Replace Executable Tests?
They can extend testing to deployment-specific contexts, but executable tests remain useful for checking simulator fidelity. Redwood’s validation also leaves long-horizon, multi-agent attacks uncovered.