OpenAI’s legacy Evals platform becomes read-only on October 31, 2026, ahead of the scheduled shutdown of its dashboard and API on November 30, 2026. Teams that depend on the service for model-quality checks now need to remove write dependencies and complete their migration during November. OpenAI lists Promptfoo as the recommended migration path in its deprecation schedule.
October 31 is an access-change milestone in an existing deprecation schedule. The immediate job is to preserve what the old system knows and make sure its replacement catches the same failures.
OpenAI’s official migration guide describes manually recreating evaluations in Promptfoo. That distinction matters: moving the configuration is only part of the work. Teams also need to check whether recreated graders still make trustworthy release decisions.
What Changes on October 31
OpenAI’s Evals documentation confirms that existing content remains available during the transition window, with read-only access beginning October 31 and shutdown scheduled for November 30.
| Milestone | Documented change | Practical response |
|---|---|---|
| October 31, 2026 | Existing Evals become read-only | Stop depending on operations that create or change platform state. |
| November transition window | Existing content remains available ahead of shutdown | Capture definitions, data, and useful historical results while rebuilding workflows. |
| November 30, 2026 | Evals dashboard and API are scheduled to shut down | Complete the cutover before this date. |
The published dates do not specify a cutoff time or time zone. Neither midnight UTC nor access through the end of November 30 should be treated as guaranteed.
Read-only access also changes how teams should think about the remaining month. It is a retrieval and migration window, not a period for continuing normal development on the legacy platform. Review anything that creates evaluations, modifies criteria, or launches and records new runs. The cited notice does not provide an endpoint-by-endpoint account of write failures, so avoid building a workaround around assumed error behavior.
My recommendation is to separate two deadlines internally: preserve essential records immediately, then finish validation and cutover comfortably before November 30. Otherwise, an unexpectedly difficult grader migration could consume the time needed to recover historical context.
Inventory and Preserve the Existing Evals
OpenAI’s migration guide says:
“This guide covers manually recreating an evaluation in Promptfoo.”
The guide does not document a complete history-export procedure or an automated transfer. That is narrower than saying no export capability exists anywhere. Teams should use available retrieval or export mechanisms where supported, then manually capture whatever the replacement needs.
Create an inventory with an owner and migration status for each evaluation. Include:
- Evaluation purpose: The behavior being checked, the application it protects, and whether it blocks a release.
- Prompts: Message roles, instructions, templates, variable names, and relevant saved-prompt versions.
- Test data: Input rows, reference answers, annotations, and important edge cases.
- Model configuration: Provider, model identifier, generation settings, and any required tools.
- Grading rules: Rubrics, judge prompts, reference fields, scoring scales, thresholds, and aggregation rules.
- Historical evidence: Useful outputs, per-case scores, known failures, run identifiers, and dates.
- Dependencies: CI jobs, scheduled scripts, dashboards, and deployment checks that consume the results.
Store enough material outside the retiring platform to explain a past pass or failure. A copied dashboard URL will have limited value after shutdown.
For example, a historical score of 92% is hard to interpret without its dataset, prompt, model, and grading criteria. Preserving that context makes the score useful as a baseline. Preserving only the percentage leaves future maintainers guessing.
Prioritize release-blocking suites and evaluations that contain hard-to-recreate reference data. Large collections of experimental runs may deserve a lighter archive, depending on their value and your retention requirements.
Map Each Evaluation Into Promptfoo
Promptfoo is an open-source CLI and library for evaluating and red-teaming AI applications and agents. OpenAI’s guide describes a configuration-centered workflow that can run locally or in continuous integration.
The documented migration mapping preserves familiar building blocks, but changes where they live and how they run:
| Legacy Evals component | Promptfoo destination | What to verify |
|---|---|---|
| Evaluation definition | Portable configuration, such as promptfooconfig.yaml | The same task and cases are represented. |
| Prompts and input variables | Prompt configuration and test cases | Roles, substitutions, and reference fields retain their meaning. |
| Provider and model | Provider configuration | The intended model and required settings are selected. |
| Graders | Assertions and metrics | Rubrics, thresholds, and pass/fail behavior remain appropriate. |
| Platform-managed runs | CLI or CI execution | Results reach the people and systems that need them. |
OpenAI explicitly distinguishes this workflow from reproducing the old dashboard in another tool. Evaluation configuration can sit alongside application code, while execution becomes part of development and deployment processes.
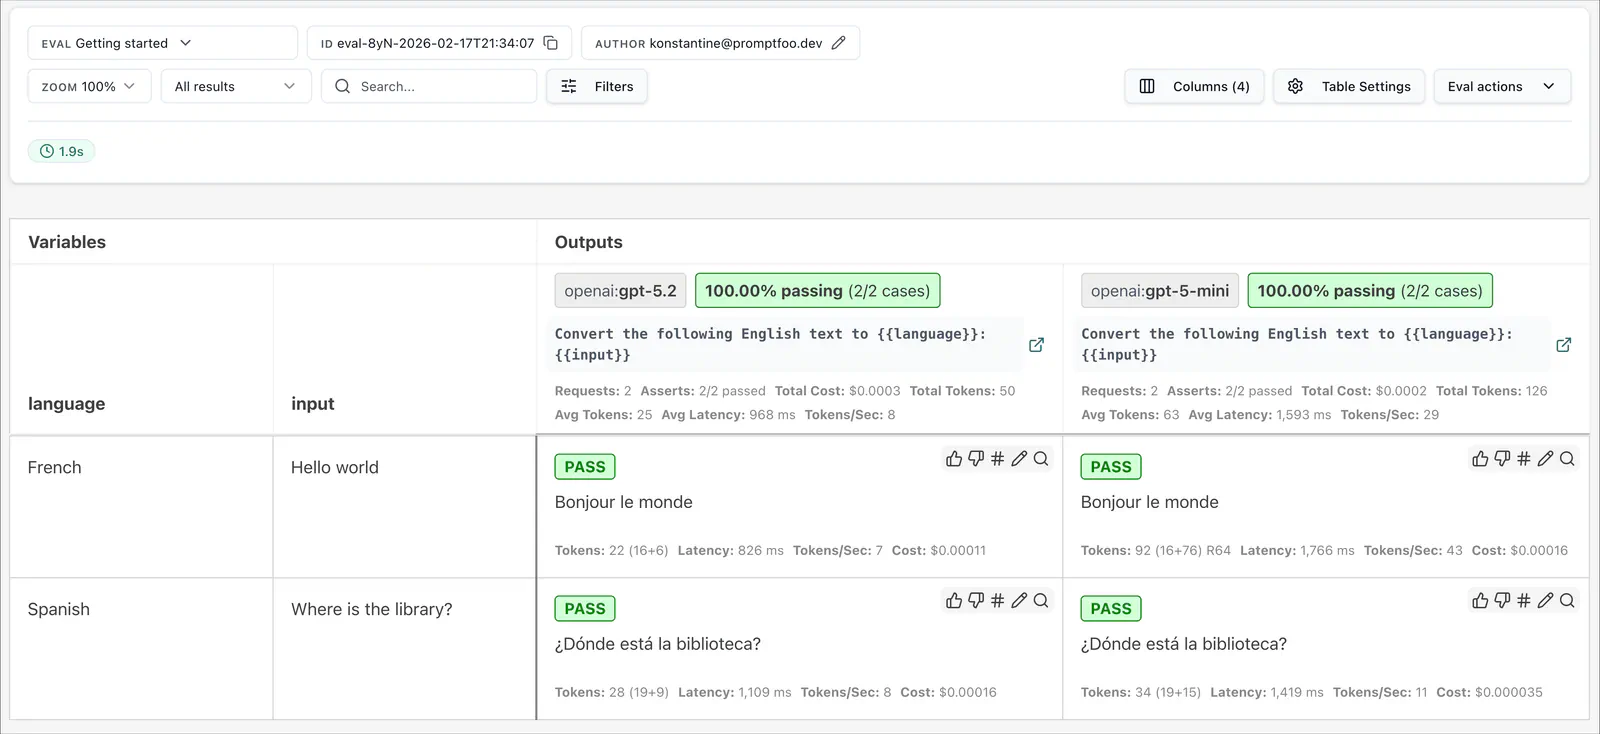
That is useful for reviewing prompt and grader changes together. It also means teams must decide where credentials are supplied, who maintains the configuration, and how results affect a build.
Tool-using applications need particular attention. OpenAI’s guide says agent, tool, or custom-provider workflows require additional configuration when they are not represented in the recreated suite. A successful migration of a plain-text prompt does not demonstrate that a tool-enabled workflow has been preserved.
OpenAI also says platform features such as dataset review and prompt iteration remain in OpenAI. Those features should not be treated as proof that every legacy Evals dashboard or API dependency has a direct replacement.
Validate Behavior, Not Only the YAML
OpenAI lists three prerequisites for its migration walkthrough: an installed Promptfoo environment, an existing evaluation, and a model-provider API key, such as OPENAI_API_KEY.
After recreating the evaluation in promptfooconfig.yaml, the guide documents this configuration-validation command:
promptfoo validate config -c promptfooconfig.yaml
The command checks the configuration. It is a useful preliminary step, but a valid configuration cannot tell you whether a recreated rubric measures the intended behavior.
The guide then provides commands for a fresh evaluation and the local results viewer:
promptfoo eval -c promptfooconfig.yaml --no-cache
promptfoo view
The first command creates a new Promptfoo evaluation run using the specified configuration without using cached results. The second opens the results locally. OpenAI notes that this run is separate from previously completed OpenAI Evals runs.
Frequently Asked Questions
3 questions
1When Does OpenAI Evals Shut Down?
The legacy Evals dashboard and API are scheduled to shut down on November 30, 2026. Existing Evals become read-only on October 31. OpenAI does not specify a cutoff time or time zone.