Developers can use Kimi K3.1 Pro through Moonshot’s products and API now, but the downloadable model will have to wait. The company’s K3.1 Pro announcement promises full weights by November 4, 2026.
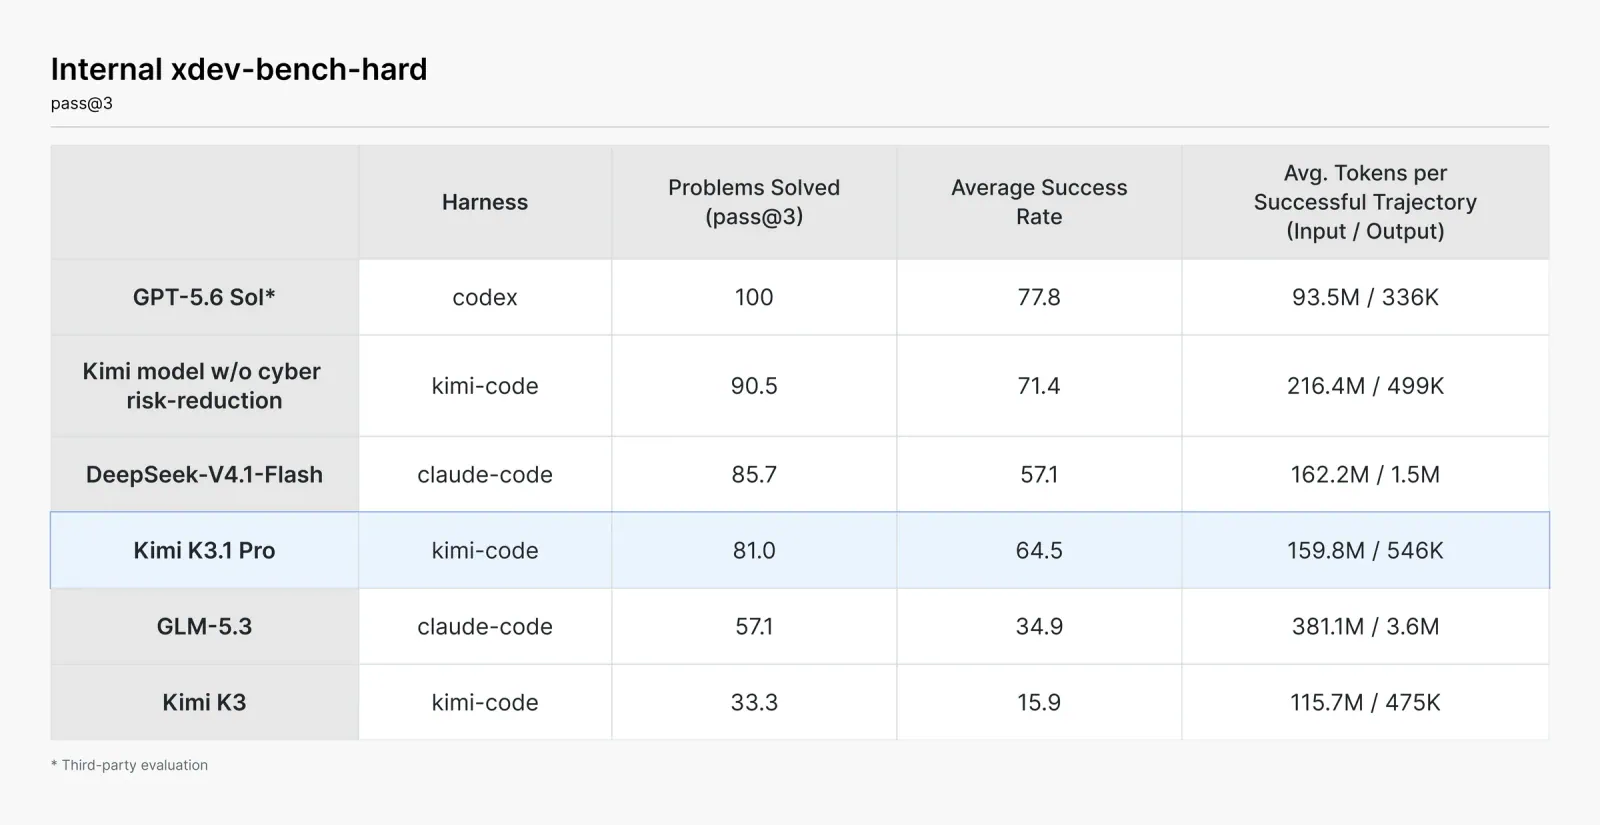
The October 23 release brings a one-million-token context window and listed API prices of $2 per million input tokens and $10 per million output tokens. Moonshot also claims coding performance close to leading proprietary models.
Hosted access, downloadable weights and benchmark performance deserve separate scrutiny. The weights remain a promise. Moonshot’s headline benchmark comparison is vendor-reported, although a separate evaluation provides additional evidence of competitive performance. Its cybersecurity disclosure describes reduced offensive capability, not proof that the planned open release is safe.
Hosted Access Arrives Before Downloadable Weights
Moonshot describes K3.1 Pro as the first model in its K3.1 series and its most capable “3T-class” model. It builds on Kimi K3 through substantially expanded post-training, including joint reinforcement learning across hundreds of downstream domains.
K3.1 Pro and K3.1 Pro Highspeed are available through Kimi.ai, Kimi Work, Kimi Code and the Kimi API. Vercel’s listing also documents image input, tool use and structured outputs. This is a multimodal LLM release, with capabilities beyond text-only coding.
Highspeed delivers two to three times Pro’s speed, according to Moonshot. The available evidence does not establish an independent, controlled comparison of latency and answer quality.
The November 4 deadline falls 12 days after the announcement. Until the weights arrive, developers can evaluate hosted behavior but cannot independently deploy the promised downloadable checkpoint.
The license remains another open question. “Open-weight” should not be treated as a confirmed open-source license, and the cited launch material does not establish the eventual terms. Teams planning self-hosting, modification or redistribution need those terms before committing.
A Million-Token Window Is Capacity, Not a Flat Fee
Vercel’s API listing gives K3.1 Pro three distinct token rates:
- Uncached input: $2 per million tokens.
- Output: $10 per million tokens.
- Cached reads: $0.20 per million tokens.
One million uncached input tokens costs $2 before output charges. A complete million-token request, however, will not always cost $2.