BeelineBench Finds Decision Models Still Take Detours
The open benchmark tests seven search domains, with modest aggregate scores and unfinished runs complicating claims that specialized AI models can plan efficiently.
Listen
AI narration
11:23
0:00 / 11:23
AI SummaryGenerated from this article
BeelineBench, an open benchmark testing decision models across seven search domains, found that Mercury Decide and Perplexity's pplx-decider 1.0 achieved the highest overall score of 0.28 compared to a 0.25 heuristic baseline, though incomplete runs complicate rankings. No specialized decision model consistently chose efficient paths across all domains—some excelled in Wikispeedia and Keys and doors while classical heuristics outperformed them in 8-puzzle, Blocksworld, and Word ladder. The benchmark measures search efficiency by counting explored nodes relative to shortest-path length, with constraints like a 2,500-node exploration limit and 255-state frontier cap that artificially inflate efficiency scores and prevent definitive conclusions about model planning capabilities.
Mercury Decide and Perplexity’s pplx-decider 1.0 share the highest published overall score in BeelineBench 1.0: 0.28, compared with 0.25 for its classic heuristic baseline. All three figures carry a warning, though. At least one run failed to finish before the benchmark’s search limit.
Some specialized decision models outperform the supplied heuristics in several domains, yet none comes close to consistently choosing a direct route across the full suite.
BeelineBench asks whether a model can make efficient choices throughout a multi-step problem, beyond answering an isolated classification question. Its open, configuration-driven harness puts Jev, Liquid d1, GPT-6 Luna Decisions, Mercury Decide, and Perplexity deciders through the same search procedure.
Introduced through a Show HN submission, the benchmark offers a check outside vendor launch claims. It remains the benchmark author’s evaluation, not an independently replicated consensus. Reading the leaderboard requires attention to the implementation details.
The Score Counts Search Detours, Not Just Correct Answers
BeelineBench uses each decision model to rank the frontier of a best-first search: the collection of discovered states that the search has not yet explored. At each step, the harness sends the available states to the model and uses its ranking to choose what to explore next.
The harness manages states and legal transitions; the model decides which available state looks most promising. This separates the model’s choice from the mechanics of the problem.
Before that search begins, breadth-first search establishes a shortest path to the goal. The efficiency score is:
The extra one converts the shortest path’s number of moves into its number of nodes, including the starting state.
A score of 1 means the search went directly along a shortest path without exploring unnecessary states. For an individual completed run, 0.25 means it explored four times as many nodes as that direct route required. Eventually finding a correct solution is insufficient for a strong score.
The seven domains test different kinds of choices:
8-puzzle: rearranging numbered tiles on a 3 × 3 board.
Blocksworld: moving blocks into a target arrangement.
Countdown: combining four numbers arithmetically to reach a target.
Work with Zeniteq
Let’s work together
We’re open to thoughtful collaborations with teams building in AI. Explore the ways we can work together.
Word ladder: changing one letter at a time through valid words.
Wikispeedia: navigating links between Wikipedia articles.
Rush Hour: moving vehicles until the designated car can exit.
Keys and doors: navigating rooms while obtaining keys needed to open doors.
The overall score is the geometric mean of the seven domain scores. It is not a success rate: 0.28 does not mean that a model solved 28% of problems. Its reciprocal should not be treated as a simple average of search overhead across all trials either.
The Leaders Win Four Domains, Not the Whole Suite
The repository’s published results show a relatively tight aggregate ranking, with much larger differences between domains.
Model or baseline
Overall score
Domains above the heuristic
Mercury Decide
0.28*
4 of 7
pplx-decider 1.0
0.28*
4 of 7
pplx-decider 1.1
0.27*
4 of 7
Jev 1.13
0.26*
3 of 7
Classic heuristic
0.25†
Baseline
Liquid d1
0.22*
3 of 7
GPT-6 Luna Decisions
0.19*
2 of 7
Random choice
0.01
Not reported
An asterisk marks an aggregate containing at least one capped model run; the dagger marks the same issue for the heuristic. These are optimistic upper bounds, not exact final efficiency values.
Mercury Decide and both Perplexity variants exceed the reported heuristic scores in Countdown, Wikispeedia, Rush Hour, and Keys and doors. Jev and Liquid d1 exceed them in Countdown, Wikispeedia, and Keys and doors. GPT-6 Luna Decisions does so in Wikispeedia and Keys and doors.
Wikispeedia produces the clearest numerical separation. The heuristic scores 0.12, while the models range from 0.61 to 0.74. Every listed model also beats the heuristic in Keys and doors, scoring between 0.65 and 0.72 against its 0.58.
In 8-puzzle, Blocksworld, and Word ladder, the heuristic leads every model. Its Blocksworld score is 0.71, compared with 0.63 for Mercury Decide and 0.25 for GPT-6 Luna Decisions.
Rush Hour is a particularly fragile “win.” Mercury and the Perplexity variants record 0.05 against the heuristic’s 0.04, but all those entries include capped runs. That nominal advantage deserves less weight than an uncapped comparison.
The results support domain-specific strengths without establishing a broadly efficient planner. The small aggregate gaps should not be read as a decisive competition between providers.
A* Remains the Right Reference Point
The benchmark author explicitly cautions that classical state-space search, including A*, will almost certainly remain the most efficient approach for most of these classic problems. BeelineBench is intended to diagnose decision-model planning, not demonstrate that models should replace established solvers.
These tasks already have explicit states, legal moves, and goals, which classical search can exploit directly. An existing search method is therefore the relevant comparison; comparing only AI models would leave it out.
A heuristic supplies a rule for estimating which states are promising. BeelineBench tests whether model rankings guide its best-first search more efficiently than the supplied domain heuristic. This is not equivalent to benchmarking each model against every suitable A* implementation. The table labels its comparator “Heuristic,” and the harness imposes constraints on that comparator too. Exceeding one heuristic’s score does not establish superiority over a well-tuned classical solver.
The metric counts explored nodes, not elapsed time or money. A better node-efficiency score alone cannot establish lower latency or lower operating cost when model requests are involved.
Two Search Limits Complicate the Rankings
Each run stops after 2,500 explored nodes. If it remains unsolved, the benchmark records 2,500 as the denominator and flags the result. Finishing the search would require additional exploration, so the recorded efficiency overstates the eventual value.
Every model’s aggregate and the heuristic aggregate are affected. Without uncapped results, the leaderboard cannot settle their final ordering.
A second constraint limits the frontier to 255 states, reflecting the maximum number of options in a Jev question. When the frontier grows larger, the harness randomly drops states until it fits. It applies the same restriction to the heuristic and the shortest-path oracle.
Equal treatment makes the comparison consistent within the harness, but changes the search problem. A discarded state might lie on a shortest path. Even the oracle, which knows the true distance to the goal, can consequently score below 1. The benchmark measures planning under a restricted, potentially lossy frontier, so its results do not describe unrestricted search performance.
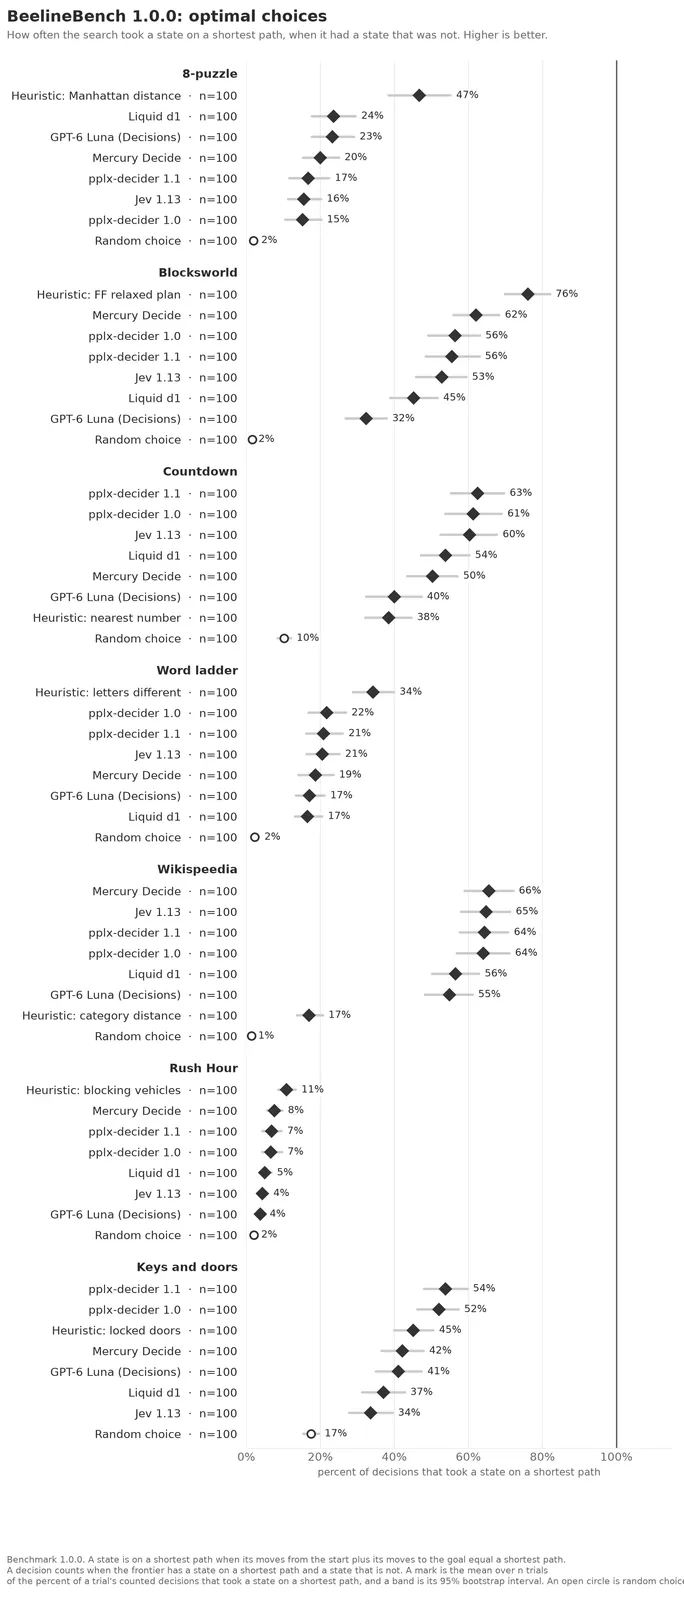
Additional diagnostics help distinguish those effects. BeelineBench reports the proportion of eligible decisions that select a shortest-path state, along with a separate path score comparing the solution found with a shortest solution. A search can eventually return an optimal-length path while wasting substantial effort exploring alternatives first. The headline efficiency score captures that wasted exploration.
An Open Harness Is Not a Deterministic Experiment
BeelineBench provides a configuration-driven harness, a portable container image, and support for models using the Jev protocol or OpenAI’s Decisions API. An optional master seed reproduces the generated trials across machines.
The procedure is inspectable and repeatable, though identical model results are not guaranteed. The harness fixes its own randomness, including trial generation, option ordering, and discarded states. It cannot fix the models’ responses. The repository reports that identical API requests can yield different probabilities, and a changed early choice can redirect the remaining search. Its displayed 95% intervals do not include that model-response variation.
Presentation also matters. The author reports Jev favoring options near the beginning of a list, so the harness randomizes option order. Text representation can affect choices too. These sensitivities warrant inspection through sensitivity studies before treating a leaderboard entry as an intrinsic planning score.
Developers can start with the baseline command, which sends no model requests. The mini benchmark runs the first 20 trials per domain with pplx-decider 1.0 and 1.1 and requires a Perplexity API key. Model runs send paid requests as the search proceeds.
For a meaningful reproduction, record the model configuration, seed, benchmark version, caps, and API behavior. Inspect domain results and unfinished trials before relying on the aggregate.
BeelineBench’s strongest use is as a diagnostic for a component embedded in a search system. It gives readers evidence beyond single-pass decision tests, without delivering a verdict on production agents. Before claiming efficient multi-step planning, a model needs to show where it saves exploration, how reliably it does so, and whether that advantage survives less restrictive search conditions.