DeepSeek’s DeepInfer release gives infrastructure teams an official engine for running DeepSeek-V4.1-Flash offline on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. DeepSeek says the framework powers its large-scale production services. The public release leaves several components of a complete hosted service to the operator.
The Apache 2.0-licensed engine includes distributed inference primitives, speculative decoding, structured outputs, and controls for reproducible generation. A companion release, deepseek-recipe, supplies MIT-licensed Rust libraries and Python bindings for converting API requests into DeepSeek prompts and parsing generated output back into protocol responses.
The repositories address two separate deployment problems: executing the model efficiently and translating application requests into the format it expects. DeepSeek’s performance and production-scale statements remain company claims unless independently reproduced.
Offline Inference Is the Starting Point
DeepInfer currently lists one supported model: DeepSeek-V4.1-Flash. The documentation starts with a source build and an offline inference example, not a ready-made public API server.
The prerequisites are specific:
- Linux, GCC 13 or newer, and Python 3.12.
- CUDA 13 for the NVIDIA backend.
- CANN 9.2 for the Huawei Ascend backend.
From a repository checkout, with an empty Python 3.12 environment activated, the documented NVIDIA path is:
export DEEPINFER_ACCELERATOR=nvidia
./build.sh
python examples/offline_inference.py
Ascend users select ascend instead. The accelerator variable must remain exported in the environment used to run DeepInfer.
The example downloads deepseek-ai/DeepSeek-V4.1-Flash-1017 into the Hugging Face cache on its first run. Operators with a local checkpoint can point DEEPINFER_HF_MODEL_DIR at that directory instead.
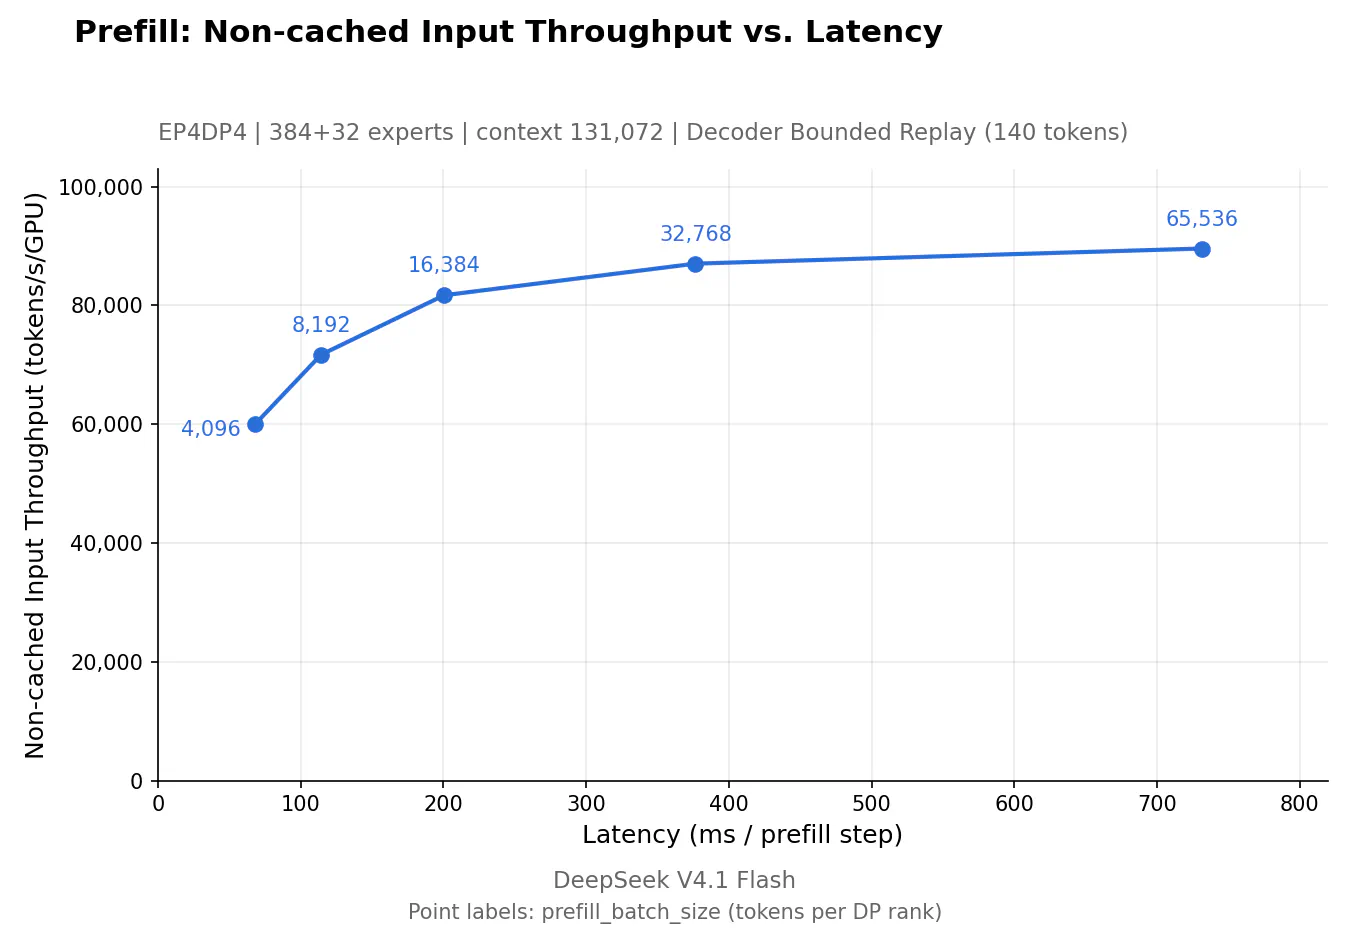
This is concrete, runnable deployment code, with a specific hardware target. The listed NVIDIA target is SM100, not the entire CUDA-capable GPU range. The benchmark configurations also do not establish a minimum hardware requirement for every supported workload.
The Missing Components Matter for a Hosted Service
DeepSeek explicitly identifies three components needed for a complete inference service that are not included:
- A KV-cache system.
- Prefill/decode disaggregation, although DeepSeek says most required engine functionality is already implemented.
- Load balancing across data-parallel replicas for both prefill and decode.
Prefill processes the input prompt; decode generates subsequent tokens. Disaggregating those stages means running and coordinating them separately, which requires more than having kernels capable of performing each operation.
The repository’s expert-parallel load balancing addresses a different scheduling problem from distributing incoming work across service replicas. It cannot substitute for that service-level scheduling.
For an infrastructure team with existing routing, cache management, and cluster operations, DeepInfer could become an execution layer inside that architecture. A team starting without those systems still has substantial integration work ahead. Publishing an engine used in production does not publish every component, operating policy, or deployment arrangement surrounding DeepSeek’s own service.
The Optimizations Include Reproducibility Controls
DeepInfer combines optimized kernels with attention data parallelism, balanced context parallelism, and mixture-of-experts expert parallelism with expert load balancing. These mechanisms distribute different portions of inference work instead of treating the model as a single-device workload.
The kernel stack includes FlashMLA, DeepGEMM, DeepEP, and additional specialized components. Their inclusion makes the release more substantial than an API wrapper around model weights.
For decoding, DeepSeek documents DSpark and confidence-scheduled verification. The mechanism drafts tokens and uses confidence estimates to schedule their verification. Its configurable maximum draft length defaults to five; that setting is not evidence of a fivefold speedup.
Sliding-window-attention bounded replay reduces decoder prefill work by replaying a limited suffix. DeepSeek documents a default retained suffix of 140 tokens for V4.1, with the requirement that it cover the attention window plus maximum backtracking length. Asynchronous scheduling, enabled by default, overlaps CPU batch scheduling with device execution.
The reproducibility settings deserve particular attention. DeepSeek describes batch-invariant inference as keeping model results identical across different batch compositions. Deterministic sampling additionally requires disabling variable-length multi-token prediction and supplying a fixed seq_seed, alongside identical input tokens and sampling parameters.
Both features are marked NVIDIA-only.
For regression testing, a fixed seed alone is therefore insufficient under the documented recipe. Deterministic output under these settings also does not guarantee identical results across hardware backends, software versions, or DeepSeek’s hosted service.
Recipe Handles the Boundary Between APIs and Prompts
Deepseek-recipe translates between application-facing request formats and DeepSeek’s model-facing conversation representation, leaving model execution to DeepInfer or another inference backend.
Its documented flow is:
- Convert a Messages, Chat Completions, or Responses request into a shared
Conversationformat. - Render that conversation into a DeepSeek V4 or V4.1 prompt.
- Encode it into token IDs when a tokenizer is attached.
- Parse generated output into the corresponding response format, including streaming responses.
The supported scope includes reasoning content, client tool calls, thinking mode, generation settings, and Chat Completions prefix continuation.
For self-hosters, this provides a reference implementation for behavior that otherwise requires reconstruction: prompt formatting, tool-call representation, reasoning separation, and response parsing. It can help reproduce the request and response conventions expected by applications, beyond accepting JSON with familiar field names.
It does not establish full equivalence with DeepSeek’s hosted API. The caller must supply model inference, tool execution, and HTTP transport. The included FastAPI and Axum server examples use mock inference, so they are not integrated V4.1 Flash serving endpoints.
Developers can explore the conversion layer before a cluster is ready. The repository’s encoding-and-decoding demo renders prompts, highlights special tokens, and parses complete model output into the supported response formats. It lets developers inspect how their requests become prompts and how model output is expected to become application data without running the model.
Structured Outputs Require Enforcement in the Backend
Describing an output constraint and enforcing it during generation are separate responsibilities in these releases.
Deepseek-recipe validates supported JSON Schemas and renders them into prompts. It also selects an OutputConstraint for the inference backend, including applicable tool-call or response-format constraints. Its structured-output documentation explicitly leaves constrained-decoding enforcement to the caller.
DeepInfer documents constrained generation using a regex, JSON Schema, or EBNF grammar through SamplingParams. An integration needs to carry the relevant constraint from the protocol conversion layer into the execution backend. Merely accepting a field does not demonstrate that the generated output will obey it.
Sources
- DeepInfergithub.com
- deepseek-recipegithub.com