
Z.ai has released GLM-5.3-Flash, a natively multimodal AI model designed to deliver high-end coding, agentic, and visual reasoning performance without the usual inference bill. It accepts text, image, and video inputs, supports a one-million-token context window, and activates 18 billion parameters from a total model size of 320 billion.
The standard API price is $0.15 per million input tokens, $0.50 per million output tokens, and $0.03 per million cached input tokens. Z.ai has also released the model’s open weights under the MIT License, giving developers an alternative to using the hosted API.
Performance is the more consequential claim. Z.ai’s testing shows GLM-5.3-Flash beating GLM-5.2 across multiple coding and agentic evaluations. On the company’s own Code Bench, its highest-effort result narrowly exceeds Claude Opus 4.8. Those numbers are promising, although the in-house results still need independent reproduction.
A 320B Model That Activates Only 18B Parameters
The “320B-A18B” description refers to a mixture-of-experts design. GLM-5.3-Flash contains 320 billion total parameters, but it selects approximately 18 billion active parameters for each token rather than running the entire network every time.
That distinction is central to the model’s economics. Z.ai has reduced the active parameter count from 32 billion in the earlier GLM-4.5 series while cutting the number of layers from 92 to 45. The resulting model is not simply small. It retains a large pool of specialized parameters but tries to use less computation during each inference step.
Active parameter count should not be confused with memory footprint. A self-hosted deployment still needs to store and distribute the much larger set of model weights. The A18B figure mainly describes how much of the network participates in computation for a given token, not how much hardware is required to load the model.
Competitive Pricing
Z.ai’s standard API pricing places GLM-5.3-Flash well below the usual rates for frontier-class models:
| Token type | Standard price per 1M tokens |
|---|---|
| Input | $0.15 |
| Output | $0.50 |
| Cached input | $0.03 |
A request using one million fresh input tokens and producing one million output tokens would cost $0.65 at list prices. Reusing a cached one-million-token prompt lowers the input portion to $0.03, which is particularly relevant to coding agents repeatedly working with the same repository, instructions, or tool definitions.
Z.ai is also offering a temporary 50% launch discount through September 9, 2026, at 24:00 UTC+8. During that period, input costs $0.075 per million tokens, output costs $0.25, and cached input costs $0.015. The company’s cost-per-task benchmark figures use this discounted pricing, so they should not be mistaken for the permanent rate.
Low token prices are only useful if a model can complete tasks without excessive retries or unusually long reasoning traces. Z.ai is therefore positioning GLM-5.3-Flash around cost per successful task rather than token price alone.
Coding Results Approach Claude Opus 4.8, With Caveats
On the Artificial Analysis Intelligence Index v4.1.1, GLM-5.3-Flash received a score of 57. Z.ai calculates a discounted cost of $0.045 per task, placing it near the cost-performance frontier and at an intelligence level the company says previously cost roughly ten times as much. Artificial Analysis lists the model with a one-million-token context window and open-weight availability.
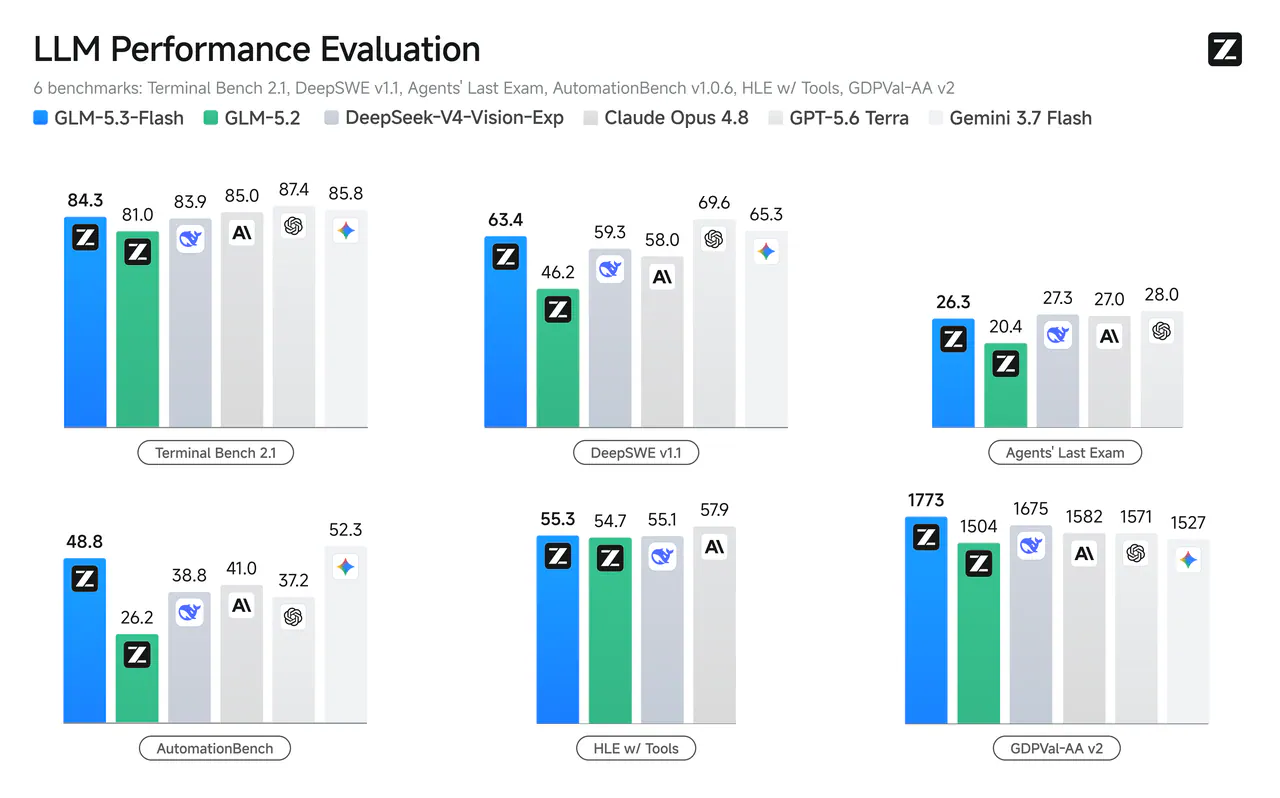
The gains over GLM-5.2 are clearer on Z.ai’s reported coding and agentic benchmarks. GLM-5.3-Flash scored 63.4 on DeepSWE v1.1, compared with 46.2 for GLM-5.2. On AutomationBench, the difference was 48.8 versus 26.2. It also posted smaller improvements on SWE-bench Verified, Terminal-Bench 2.0, PaperBench, and FRAMES.
The headline Claude comparison comes from Z.ai Code Bench v1.0, which evaluates real-world coding tasks through Claude Code. GLM-5.3-Flash surpassed GLM-5.2 at every tested effort level and reached 71.3 at maximum effort, narrowly ahead of Claude Opus 4.8 at 70.6.
That result supports Z.ai’s argument that the model is competitive for coding agents. It does not establish general parity with Opus across writing, research, tool use, or every software engineering workflow. Code Bench is also Z.ai’s in-house evaluation. Independent testing will matter, especially for long-running tasks where reliability, recovery from failed tool calls, and code quality are harder to capture in a single score.
Native Multimodality Extends Beyond Image Prompts
GLM-5.3-Flash takes text, images, and video as native inputs while producing text output. Z.ai lists screenshot interpretation, chart and diagram analysis, long-video understanding, web browsing, computer use, and visual coding among its intended workloads.
This makes the model more useful for agents that operate through graphical interfaces. A coding agent could inspect a rendered webpage, compare it with a reference design, identify layout problems, and then modify the underlying code. A computer-use system could interpret application states visually instead of depending entirely on structured accessibility data.
The one-million-token window also gives those workflows room for source code, documentation, screenshots, tool histories, and long media transcripts. Context capacity alone does not guarantee that the model will retrieve every relevant detail accurately, but it removes a common mechanical limitation for repository-scale and document-heavy tasks.
Hybrid Attention Makes the 1M-Token Context Practical
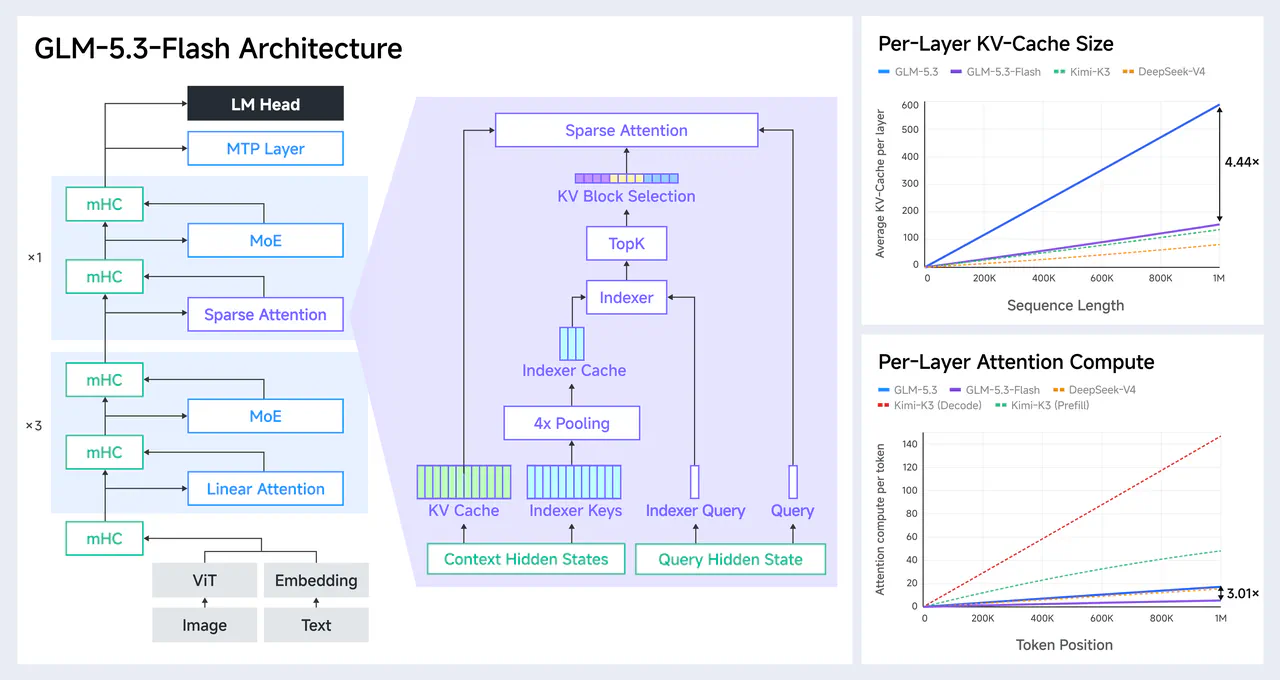
Processing one million tokens with conventional full attention would be expensive, so GLM-5.3-Flash uses a hybrid design with a 3:1 ratio of linear-attention layers to sparse-attention layers. Linear attention handles local dependencies through state modeling, while sparse attention uses an indexer to retrieve relevant information from the wider context.
Z.ai also introduced IndexPool, which compresses four indexer keys into one. The company says this reduces indexer forward-pass latency and memory use by 75% at the maximum context length. For generation, a multi-token prediction module forecasts the next three tokens and reportedly achieves 2.6 times the speculative decoding acceptance rate of GLM-4.5-Air.
The training recipe is equally important. According to Z.ai, text pre-training covered 28.5 trillion tokens. The company then added 900 billion interleaved vision-text tokens for native multimodality and 200 billion long-context text tokens before post-training the text and vision components.
Frequently Asked Questions
4 questions
1What is GLM-5.3-Flash?
GLM-5.3-Flash is a natively multimodal mixture-of-experts AI model from Z.ai. It contains 320 billion total parameters while activating approximately 18 billion per token. The model accepts text, images, and video, supports up to one million tokens of context, and is designed for coding, agentic, visual reasoning, and computer-use workloads.


