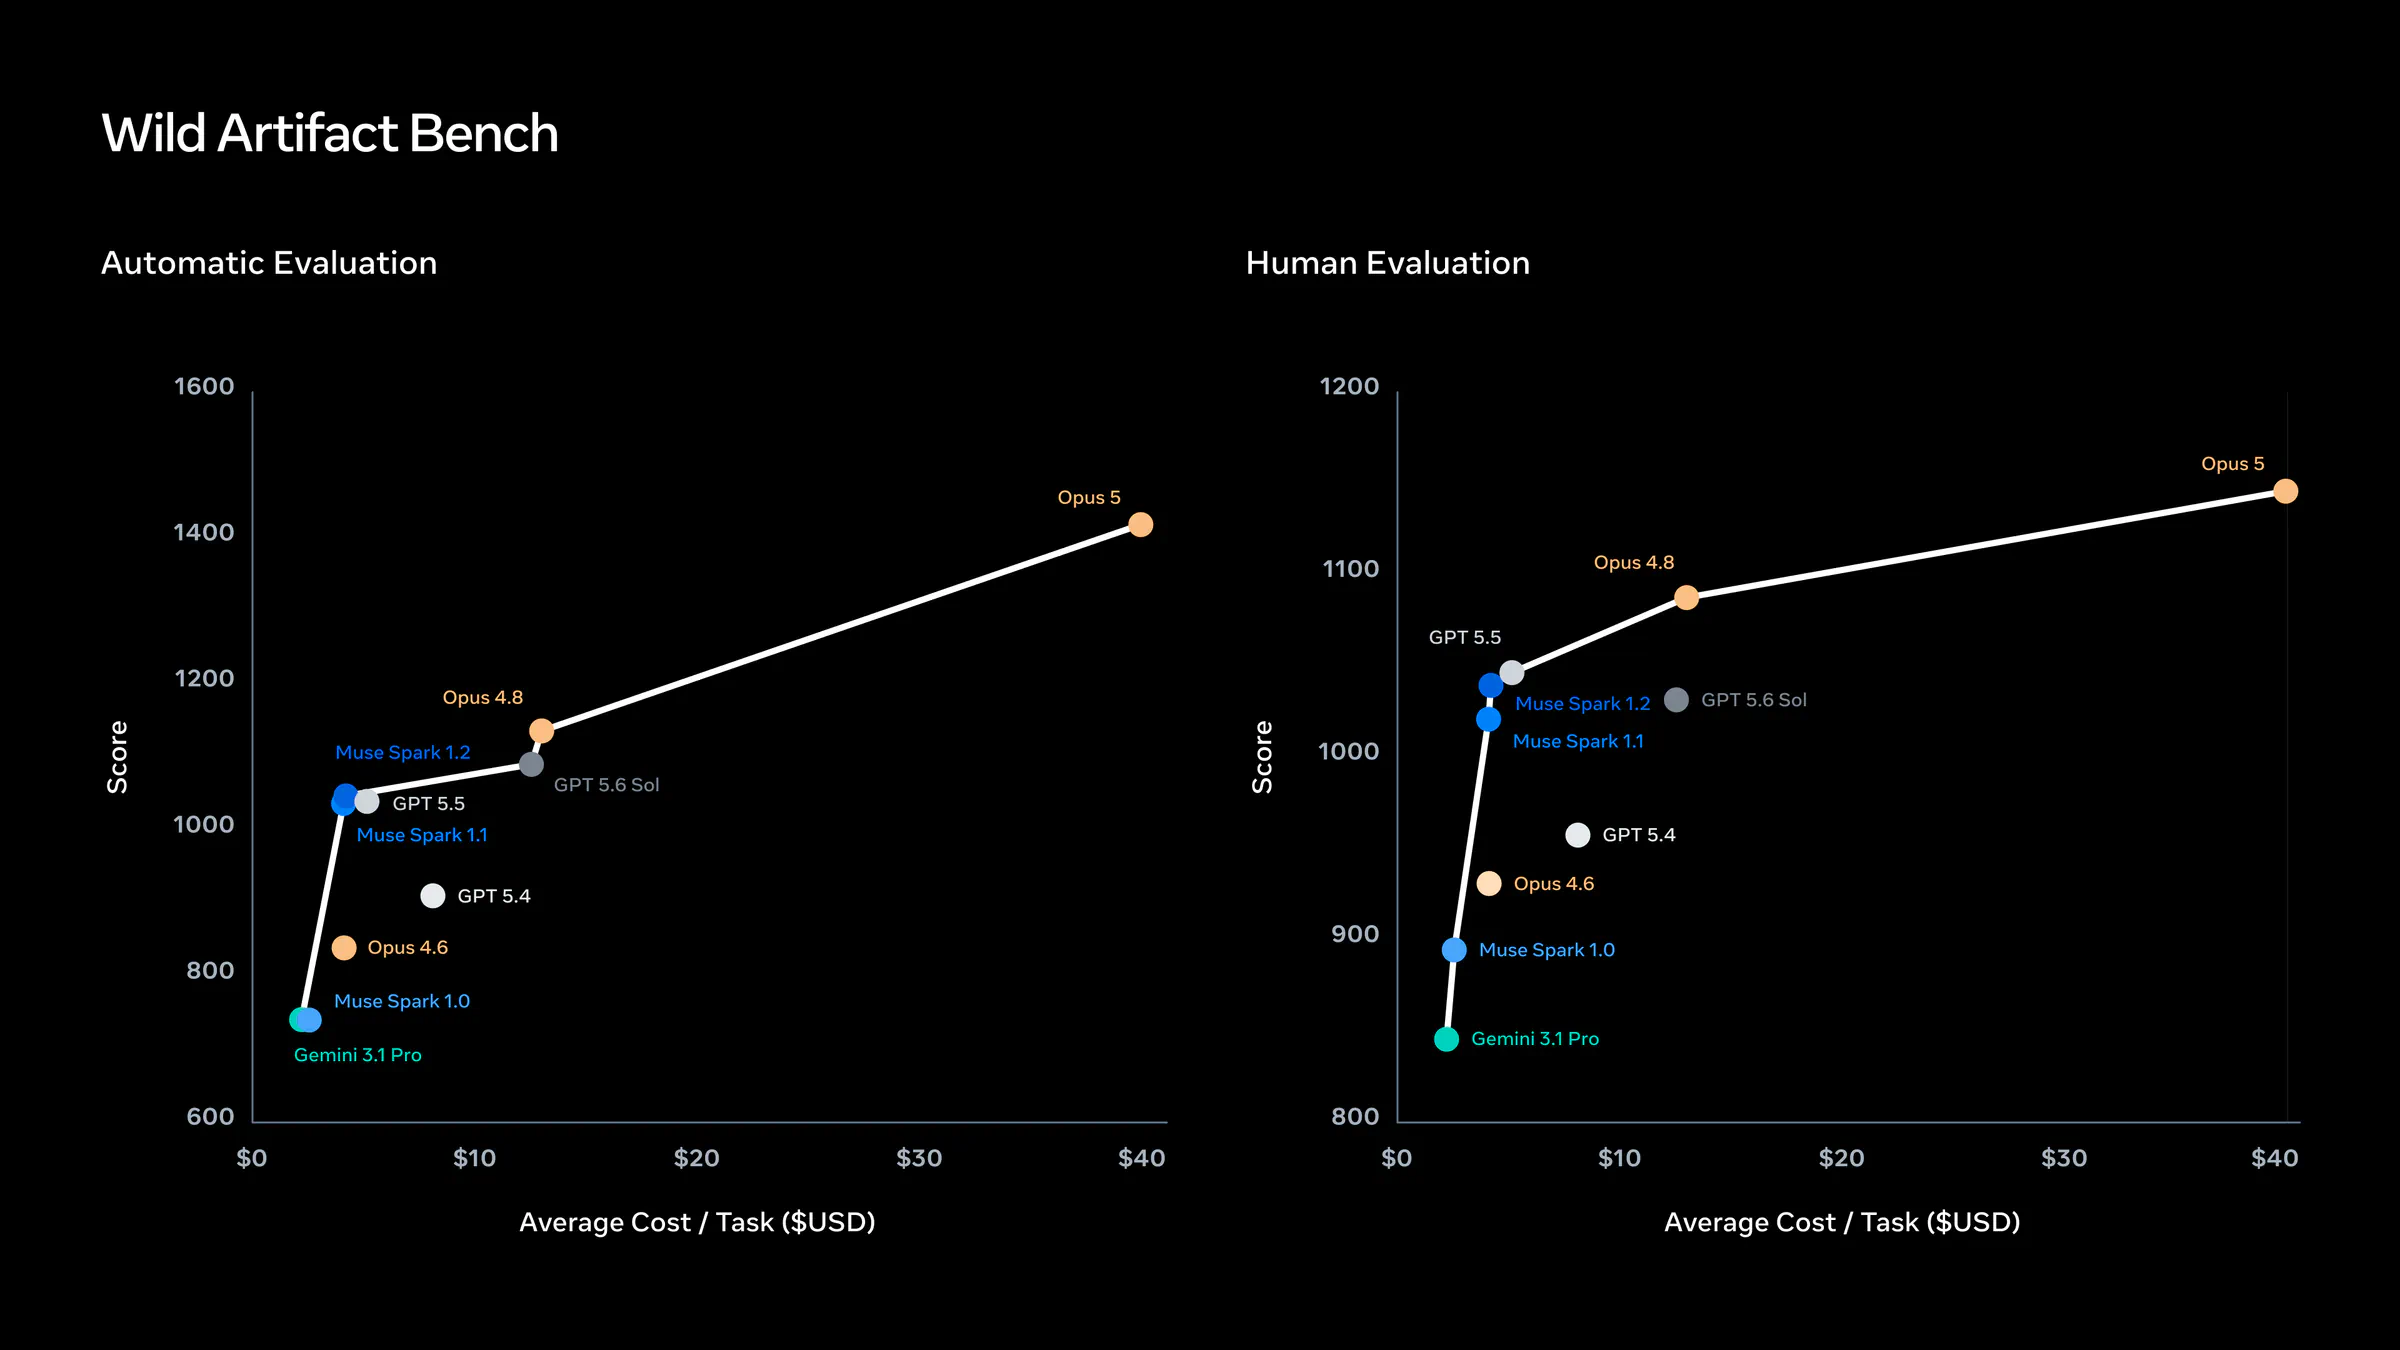
Meta is previewing WildArtifactBench, an internal evaluation framework built around a difficult question: how do you measure an AI agent when its job is to produce a finished piece of work rather than a short text response?
The public WildArtifactBench task viewer currently exposes 10 tasks spanning audio analysis, medical imaging, engineering, machine learning, 3D modeling, digital design, and video editing. Depending on the assignment, an agent may need to return a CSV file, analytical plots, segmentation masks, an interactive browser application, a watertight 3D mesh, a laser-cutting design, or an edited MP4.
Meta’s more consequential choice is how those artifacts are compared. WildArtifactBench uses win rates and Elo scores derived from human and agentic preference judges instead of depending entirely on rigid ground-truth scoring. That expands the range of workflows the Benchmark can cover, but it also makes judge quality and methodological transparency central to whether its rankings can be trusted.
WildArtifactBench Evaluates Finished Work, Not Chat Responses
Most LLM benchmarks end with text, code, a multiple-choice answer, or a deterministic state change. WildArtifactBench asks an agent to assemble deliverables that may require perception, planning, tool use, file manipulation, programming, visual judgment, and validation in the same run.
The preview’s tasks illustrate how far Meta wants to move beyond conventional question answering:
| Task | Agent workflow | Expected deliverable |
|---|---|---|
| Bird Sound | Match 46 audio recordings to species descriptions in a YAML file | CSV mapping audio files to bird species |
| Cardiac Ultrasound | Extract left-ventricle contours across an ultrasound sequence | JSON coordinates, annotated PNG frames, and an area plot |
| DQN Driving | Build and train eight parallel driving environments in a browser | Interactive 3D simulator with training metrics |
| Materials Metrology | Calibrate and analyze an alloy micrograph containing noise and defects | Masks, measurements, overlays, statistics, and a report |
| Microchip Model | Reconstruct a package from drawings, specifications, and reference views | Labeled 3D model, cutaway, exploded view, and renders |
| Video Editing | Turn source footage into a coherent trailer with an intentional audio edit | A 25-to-45-second landscape MP4 |
Other tasks involve mapping coronary stenoses, creating a low-poly cat mesh, integrating furniture into a realistic 3D kitchen, and designing an SVG plywood whale that can be laser-cut and assembled without glue.
These are not isolated perception tests. The bird task, for example, requires an agent to inspect dozens of audio files, interpret textual species descriptions, make repeated classifications, and package the results under an exact filename. A capable audio model can still fail if the surrounding agent loses track of files or produces a malformed CSV.
Preference Judging Makes More Tasks Measurable
WildArtifactBench compares outputs through preferences. Judges are shown competing artifacts and decide which one better satisfies the task. The resulting wins, losses, and ties can be reported directly as win rates or combined into Elo ratings.
A win rate describes performance against a particular opponent or reference set. Elo attempts to produce a broader relative ranking from many pairwise matchups. Similar systems have been used for open-ended LLM evaluation, most visibly in Chatbot Arena, because selecting the better of two responses is often easier and more consistent than assigning each response an absolute score.
Artifact evaluation raises the difficulty. A text-only judge cannot properly determine whether an OBJ file is watertight, a browser simulator runs smoothly, an SVG can be fabricated, or a trailer has coherent visual and audio timing. An agentic judge can potentially use tools to open files, render models, execute applications, inspect metadata, run validation scripts, and gather evidence before choosing a winner.
That approach resembles the broader Agent-as-a-Judge idea, where the evaluator is itself an agent capable of multi-step inspection rather than an LLM making a single judgment from a prompt.
Meta has not yet explained the exact inspection tools, prompts, or decision process used by WildArtifactBench’s agentic judges. Those details will matter as much as the task collection.
Ground Truth Works Until Quality Has Several Valid Forms
Some requirements in WildArtifactBench remain objectively testable. A video can be checked for duration and resolution. A CSV can be parsed. An SVG can be inspected for overlapping paths. A mesh can be tested for non-manifold edges, while masks and coordinates can be compared with held-back annotations.
The public task pages therefore include evaluation criteria even though the overall framework emphasizes preference judging. This suggests a useful division of labor: deterministic checks establish whether an artifact is valid, while preference judges compare the quality of artifacts that pass those checks.
That distinction is essential for open-ended work. There is no single correct low-poly cat model or Big Buck Bunny trailer. Two kitchen renders may contain every requested object but differ substantially in lighting, composition, realism, and faithfulness to the reference. A DQN demonstration may technically run while remaining too slow or confusing to be useful in a classroom.
A strict rubric either misses these differences or requires hundreds of narrowly specified rules. Pairwise judging lets the Benchmark ask a more practical question: which deliverable would a person prefer to use?
The Agent Stack Matters More Than the Base LLM
WildArtifactBench should not be interpreted as a pure test of an LLM’s internal intelligence. Performance will depend on the complete agent system surrounding the model.
An agent may need to:
- understand text, images, audio, video, and technical file formats;
- select and operate domain-specific tools;
- write scripts for processing or validation;
- maintain state across dozens of inputs;
- recover from failed commands or invalid outputs;
- inspect its own work before submission;
- organize multiple related artifacts under precise filenames.
This makes the framework relevant to developers building production agents. A stronger foundation model may lose to a smaller model paired with better tools, planning, memory, and verification. Conversely, an impressive LLM can score poorly if its harness cannot open the source material or validate the final files.
A single overall Elo number could hide those distinctions. WildArtifactBench will be more informative if Meta reports task-level results, modality breakdowns, failure categories, completion costs, and the performance of different agent scaffolds using the same underlying model.
Meta Still Needs to Document the Evaluation Pipeline
Frequently Asked Questions
4 questions
1What is Meta WildArtifactBench?
WildArtifactBench is an internal Meta evaluation framework for testing AI agents on complex, real-world artifact creation. Its public preview contains 10 tasks involving audio, medical images, engineering analysis, browser software, 3D models, vector designs, and video. Agents must produce usable files and finished deliverables rather than only generate text answers.