Google is using AI agents to help researchers develop models, but Sundar Pichai says that work remains “pretty far from the end state of RSI,” or recursive self-improvement, according to Business Insider’s October 23 report.
AI contributing to its successors is different from AI independently directing the research needed to improve itself. Pichai’s reported description supports the former. It neither establishes the latter nor supplies a measurable timeline for reaching it.
Pichai Describes Researchers Working With Agents
Pichai made the remarks in an interview with Alex Kantrowitz for the Big Technology Podcast. The interview’s accompanying article, published October 20, 2026, says the conversation was recorded that week at Google’s Mountain View headquarters. The exact recording date is not given. Business Insider published its account three days later.
The publicly accessible interview excerpt discusses AI helping develop future models, but does not include the specific RSI exchange. The relevant quotations therefore come through Business Insider’s reporting, without a directly verified transcript of that portion.
According to that account, Pichai described agents helping AI researchers work together, with some automation, across aspects of model development. He expected that continuum to keep progressing into the following year.
His description is of collaborative research becoming more automated. The assessment that Google remains far from an eventual end state is an executive judgment, not a benchmark result or a forecast with a defined deadline.
AlphaEvolve Shows a Bounded Improvement Loop
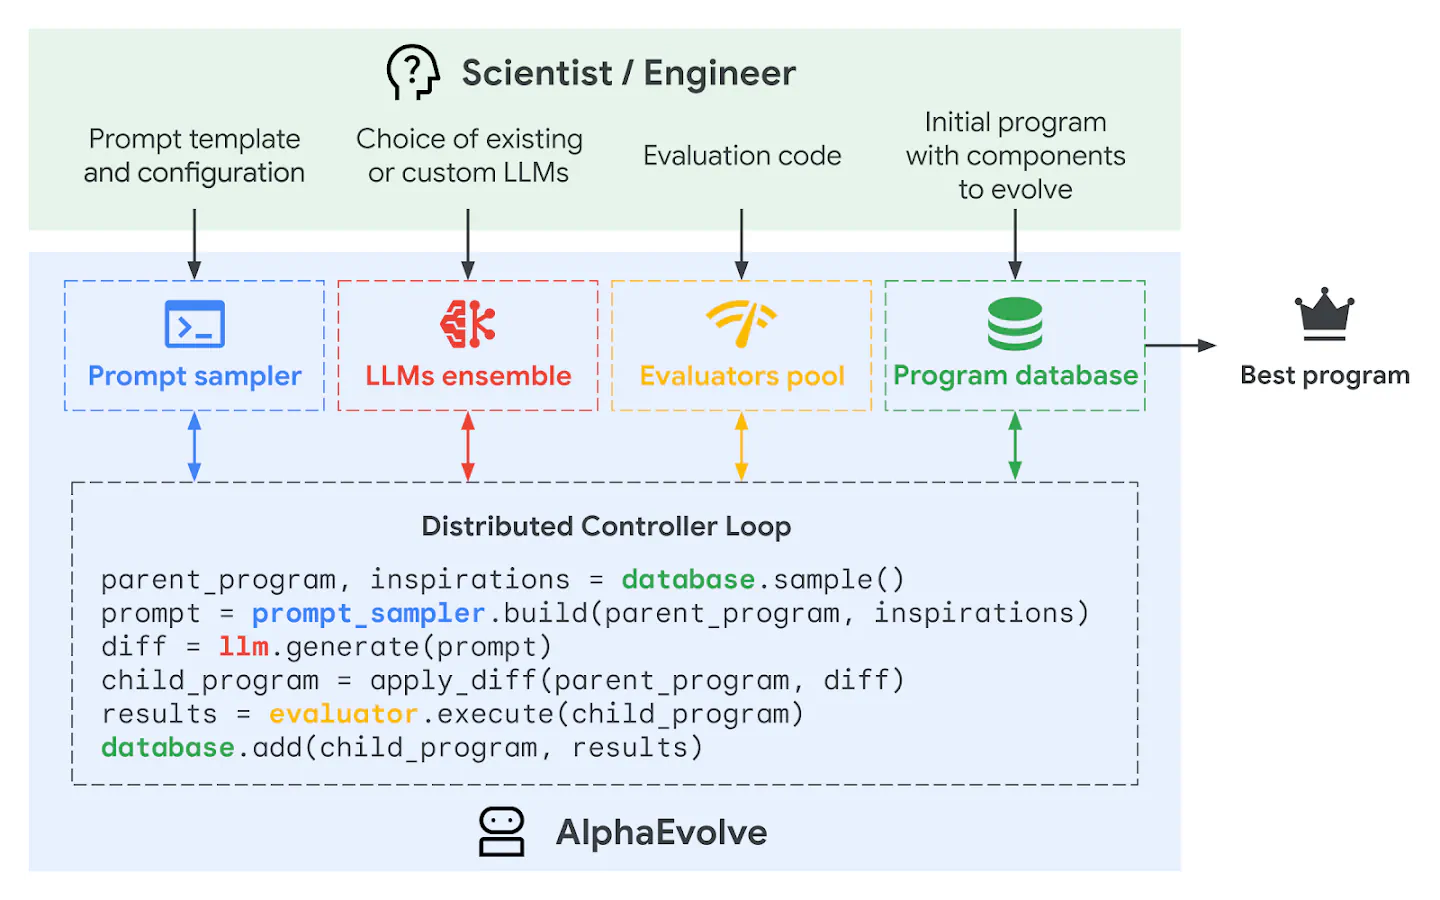
Google has published a concrete example of AI improving processes used to build AI. In its May 14, 2025 AlphaEvolve announcement, DeepMind described a Gemini-powered coding agent that proposes algorithms, tests them with automated evaluators and uses an evolutionary framework to develop promising candidates.
Generating code alone does not establish that an algorithm works or improves performance. AlphaEvolve’s evaluators run and score proposed programs against measurable criteria, allowing the system to select useful changes.