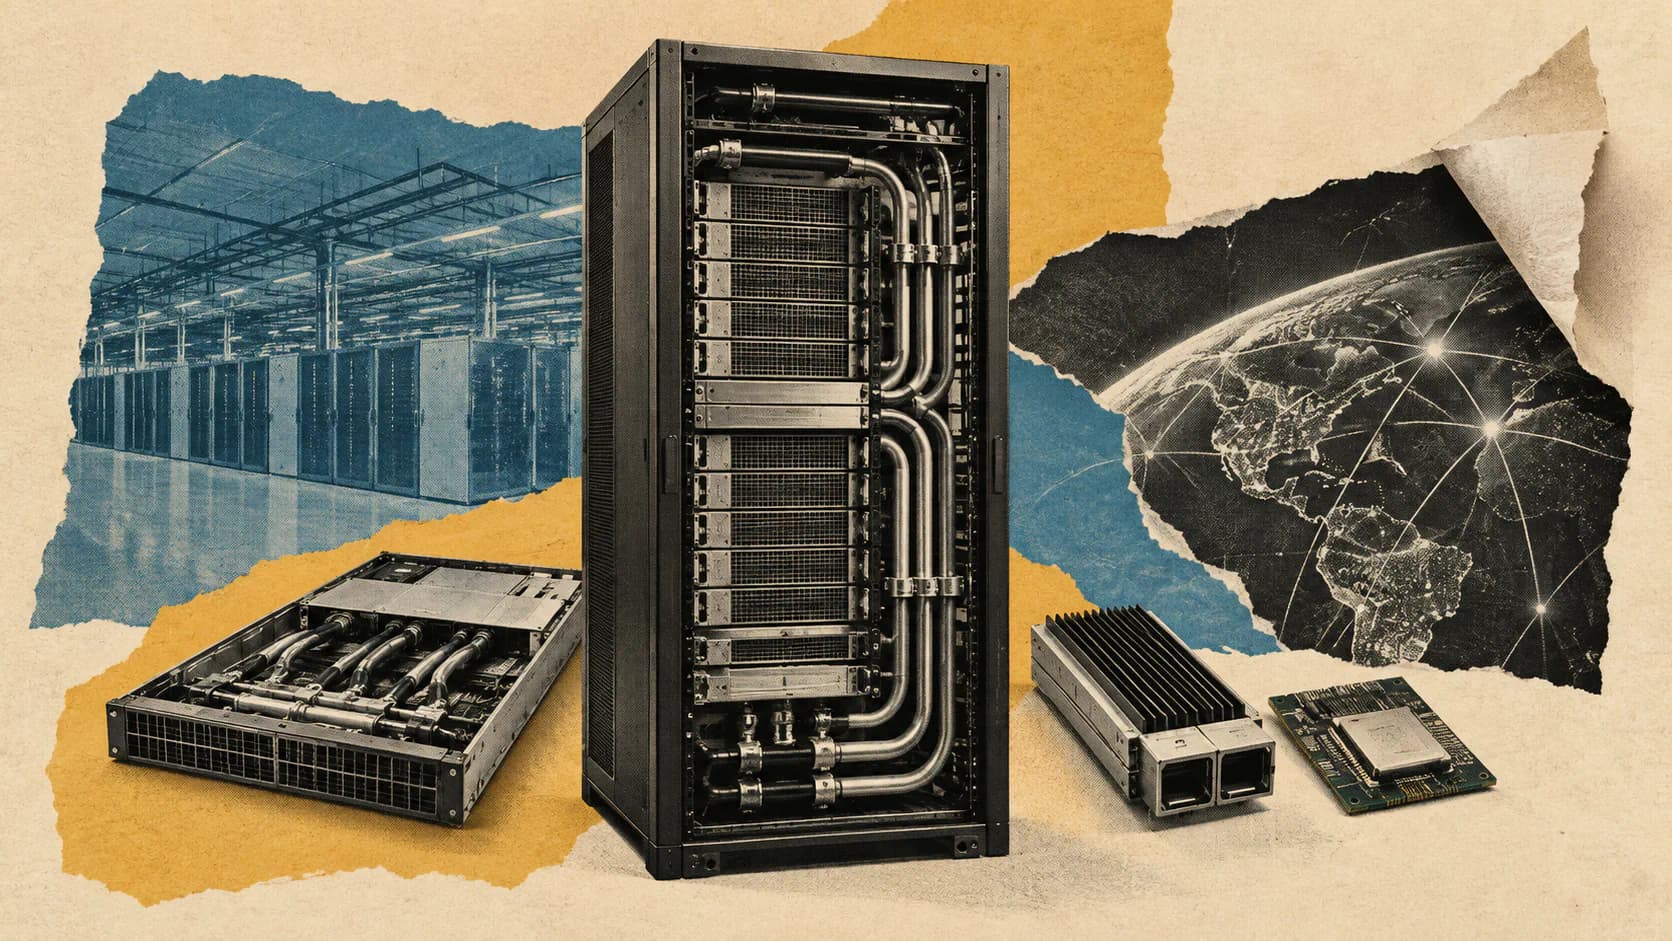
NVIDIA has contributed Vera Rubin rack and compute-tray designs to the Open Compute Project through its MGX architecture, alongside four open-source software components for configuring and operating AI infrastructure. System builders get physical designs to work from; operators get software to evaluate for deployment, validation and management.
The broader announcement covers facilities, utility-grid behavior and partner networking. Across these areas, NVIDIA is working to turn more AI-factory interfaces into shared specifications, reducing the need to negotiate requirements separately with each supplier.
Readiness varies across the announcements. Published designs and released software are available for engineering evaluation. NVIDIA and Cisco’s proposed Ultra-Dense Small Form Factor Pluggable, or USFP, optics still depend on hardware development and an upcoming multi-source specification. The package cannot be treated as immediately deployable.
MGX 1.2 Opens More of the Rack’s Physical Design
The Vera Rubin contributions extend NVIDIA’s MGX architecture into a shared foundation for rack-scale infrastructure. According to NVIDIA, MGX 1.2 includes blind-mate liquid cooling, interoperable rack-scale interconnect infrastructure and a liquid-cooled 5,000A busbar, with support for rack deployments up to 250kW.
Other additions include native 19-inch equipment support, configurable I/O bays, fanless liquid-cooled compute trays, and standardized power and cooling interfaces.
Those interfaces give infrastructure buyers a basis for evaluating how compute trays, networking, cooling and power fit together. When multiple suppliers work against the same requirements, operators can more clearly assess whether their equipment can be integrated and serviced together.
Blind-mate cooling connections engage as equipment is inserted, eliminating the need to attach each connection separately. NVIDIA says the updated architecture improves assembly, testing and service times, though the announcement supplies no independent measurements of those improvements.
Support for deployments up to 250kW describes the architecture’s design envelope. It is not a measured operating load or evidence that an existing facility can accommodate it without changes. Buyers still need to verify their electrical distribution, heat-removal capacity and maintenance procedures against the configuration they intend to install.
NVIDIA also contributed a Vera CPU rack design, which it positions for agentic workloads such as tool calling, orchestration and sandboxed execution. This extends the shared rack architecture beyond GPU training and inference while retaining common design principles for power, cooling and networking.
The contribution covers infrastructure designs and interfaces. It does not make the processors themselves open hardware or establish that every component inside the rack is interchangeable.
Four DSX Components Address Operational Bottlenecks
The software portion targets the work required to turn installed hardware into usable clusters. NVIDIA says it expanded DSX OS, the operating layer of its AI-factory platform, with four open-source components:
- NVIDIA Config Manager automates switch configurations, helping operators deploy, validate and maintain consistent network fabrics.
- NVIDIA Cluster Readiness Engine stress-tests GPU clusters with workload simulations before production training begins.
- NVIDIA Rack Management Service provides a rack-level hardware abstraction and operations layer, including firmware management.
- Cluster API Provider for NVIDIA Infrastructure Controller supports bare-metal provisioning and tenant onboarding.
Each addresses a distinct failure point. Incorrect network configuration can undermine an otherwise healthy cluster. Hardware problems discovered after a training run starts are more disruptive than those caught during acceptance testing. As deployments grow, firmware management and provisioning become harder to coordinate.
The components were developed from NVIDIA’s experience operating DGX Cloud, according to the company. That operational origin does not establish how well each will fit another provider’s hardware, network or tenancy model.
NVIDIA also claims the tools can eliminate costly job crashes and convert hardware into production-ready clusters in hours rather than days. The supplied announcement does not independently demonstrate those results. Readiness testing can expose faults; it cannot establish that a cluster will never fail.
Operators can now evaluate the components against existing workflows, checking which devices they support, what privileges they require, and how they interact with current provisioning and monitoring systems before treating them as production infrastructure.
Facility and Grid Specifications Extend Beyond Compute
Alongside the rack and software contributions, NVIDIA announced specifications for the building and the electrical system supplying it.
The company says it joined AMD, Google and Meta in publishing the Open Data Center Specification v0.7, covering power architecture, cooling infrastructure and physical layout. It separately joined Google, Meta and Microsoft on the OCP Grid Resilience Specification.
The grid specification addresses how large AI facilities should respond to utility disturbances. NVIDIA describes requirements for staying connected, responding automatically and restoring near-full load in less than two seconds. These are specified behaviors; the announcement does not establish that every participating facility has demonstrated them under operating conditions.
An AI factory can be internally healthy yet behave poorly during an external electrical event. Cluster readiness testing and grid resilience address different problems, so operators need acceptance criteria for both.
NVIDIA describes these specifications as compatible with its DSX reference design, connecting the community documents to a vendor implementation. Buyers still need to distinguish that compatibility claim from verified compliance in their own installation.
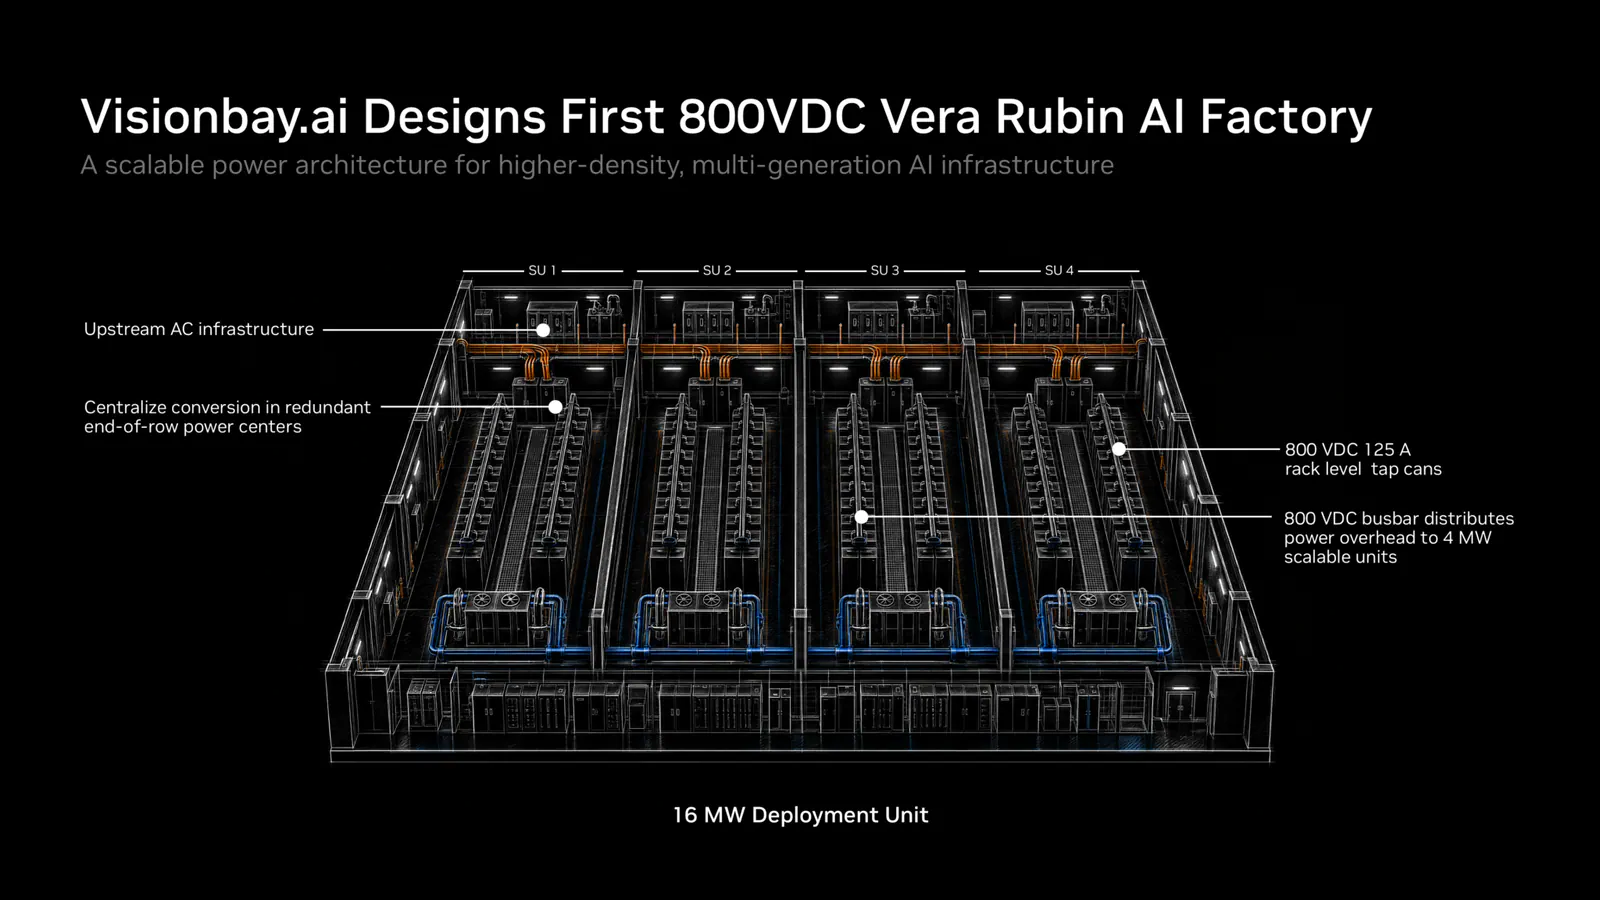
Visionbay’s planned K-1 facility platform is also part of the announcement. Designed around 800V DC distribution and future Vera Rubin deployments, it shows how a partner intends to apply NVIDIA’s architecture. It provides no evidence of a completed facility and sets no requirement for all operators to immediately adopt 800V DC.
Partner Networking Work Has Different Timelines
NVIDIA says Meta is adopting Spectrum-6 102.4Tb/s Ethernet switches for larger Vera Rubin AI factories. It also announced Falcon Transport support with Google on future ConnectX-10 SuperNICs and BlueField DPUs.
An announced adoption and future product support represent different commitments. Neither establishes that every networking feature discussed at OCP is available across current installations.
USFP remains a development plan: a proposed physical module format and supplier ecosystem, with no shipping transceiver described in the announcement.
Grouping these initiatives under open networking helps explain NVIDIA’s direction. Purchasing decisions require more specific information, including product delivery dates, supported configurations and interoperability evidence.
USFP’s Density Claims Are Targets, Not Shipping Results
Sources
- Vera Rubin rack and compute-tray designsblogs.nvidia.com
- October 12 USFP announcementnvidianews.nvidia.com
- OCP ecosystemopencompute.org