NVIDIA Previews Kubernetes Recipes for Vera Rubin | Zeniteq
Loading
Loading article
Zeniteq is now available on mobile for iPhone, iPad and Apple Watch.Download nowLearn more
NVIDIA Previews Kubernetes Recipes for Vera Rubin
NVIDIA’s AICR recipes give early adopters a documented Rubin cluster configuration, while production qualification and inference performance remain unfinished.
NVIDIA released preview Kubernetes recipes for the Vera Rubin NVL72 system, providing platform teams with a validated baseline using RKE2, Ubuntu 26.04, and the R615.23 driver. While these recipes successfully passed deployment and NCCL all-reduce tests, achieving 744.71 GB/s bandwidth, they lack production support and inference performance benchmarks. Teams must carefully manage dependencies like DRA v0.5.0 and host-installed drivers, as the migration from GB200 architectures introduces complex I/O placement changes. This preview serves as a crucial integration guide for early adopters, though production readiness remains unfinished.
NVIDIA published preview Kubernetes recipes for Vera Rubin NVL72 on November 2, 2026, giving platform teams a concrete starting point for evaluating the hardware with RKE2 and Ubuntu 26.04. The release includes training, inference and NVIDIA Dynamo inference variants, plus validation results from early Rubin systems.
The important word is Preview. These recipes do not carry the production support and lifecycle qualification of a Supported recipe. NVIDIA reports successful deployment and conformance checks, alongside a training-oriented communication benchmark, but explicitly leaves inference-serving performance unresolved. NVIDIA’s announcement describes an early migration path, not a completed production certification.
For platform teams, the useful contribution is the configuration itself: which driver runs on the host, which components Kubernetes manages, how multi-node NVLink resources are exposed, and where validation stops. Those details make this more actionable than a general promise of Rubin support.
What the AICR Preview Actually Packages
NVIDIA AI Cluster Runtime, or AICR, captures platform settings in versioned recipes, generates deployment bundles for existing tools, and validates the resulting cluster. It is part of NVIDIA’s DSX AI Factory Platform.
A recipe connects choices that otherwise need to be reconciled separately: operating system, kernel, GPU driver, container runtime, operators and hardware-specific settings. A working driver alone cannot establish that Kubernetes workloads can access the GPU or communicate correctly across nodes.
The Vera Rubin recipe family uses RKE2, the vr200 accelerator identifier and Ubuntu. The published configuration includes these coordinates and management choices, as detailed in the recipe coverage from BPDATA:
Manages other GPU-stack components, including the container toolkit
DRA driver
v0.5.0 with IMEX-backed ComputeDomains
Supports the validated multi-node NVLink arrangement
GPU allocation
Whole GPUs through the device plugin
MIG partitioning is outside this validation
The host-managed driver choice matters. The system image already includes the arm64 driver, so the recipe sets driver.enabled: false for GPU Operator while leaving the container toolkit operator-managed. That setting means “do not install another driver,” not “run without a GPU driver.”
The recipe also raises the Node Feature Discovery topology updater’s default 60Mi memory limit to avoid out-of-memory kills on multi-terabyte NVL72 workers. This is a useful example of what a reusable recipe preserves: a small control-plane setting that can still prevent a large machine from operating cleanly.
I’d treat the recipe as a versioned integration baseline. Its value comes from preserving a working combination, including less obvious settings, so another team can evaluate the same configuration without rediscovering every dependency.
What Changes From the GB200 Baseline
Vera Rubin NVL72 continues the MGX rack-scale architecture used by GB200 NVL72, but several software and topology assumptions change. NVIDIA’s migration notes distinguish tested versions from future support targets.
Area
GB200 baseline described by NVIDIA
Vera Rubin preview
GPU driver
AICR baseline R580.173.02
Tested with R615.23; early support targeted for R610, official platform support for R620
Network hardware
ConnectX-7 NICs and BlueField-3 DPUs
ConnectX-9 SuperNICs and BlueField-4 DPUs
Compute-tray layout
Two CPUs and four GPUs
Two CPUs and four GPUs
Network PCI exposure
Four ConnectX-7 adapters on the DGX GB200 reference tray
Eight ConnectX-9 PCI device groups exposing 32 functions
GPU NUMA affinity
GPUs 0–1 on NUMA 0; GPUs 2–3 on NUMA 1
Same mapping
Multi-node NVLink
Uses IMEX
Still uses IMEX
R615.23 is the tested driver, not a confirmed minimum for official Rubin support. Similarly, the validated system image ships with DOCA-OFED 3.3.0, and NVIDIA identifies DOCA 3.3.0 as the first generally available release supporting ConnectX-9. It explicitly avoids turning that testbed version into a requirement or recommendation.
Network Operator compatibility also remains a separate qualification step. This preview uses host-installed NIC drivers and DRANET for pod allocation.
The topology comparison exposes a practical migration trap: unchanged CPU and GPU counts do not mean unchanged I/O placement. NVIDIA says GPU-to-NIC connectivity is NODE within a socket and SYS across sockets. Teams running RDMA networking or GPUDirect Storage need to check affinity against the Rubin layout. The 32 PCI functions should not be interpreted as 32 physical network ports.
IMEX ownership needs attention too. With DRA-managed IMEX, NVIDIA instructs operators to stop, disable and mask the host’s static nvidia-imex service to prevent competing ownership. The validated cluster uses driverManaged mode. DRA v0.5.0 also introduces an alpha host-managed option, but that option provides domain isolation only.
My read is that this migration preserves some placement concepts while changing enough surrounding machinery to make a copied GB200 configuration risky. Keeping the same NUMA mapping does not remove the need to review networking, drivers and service ownership.
What NVIDIA Validated on Early Hardware
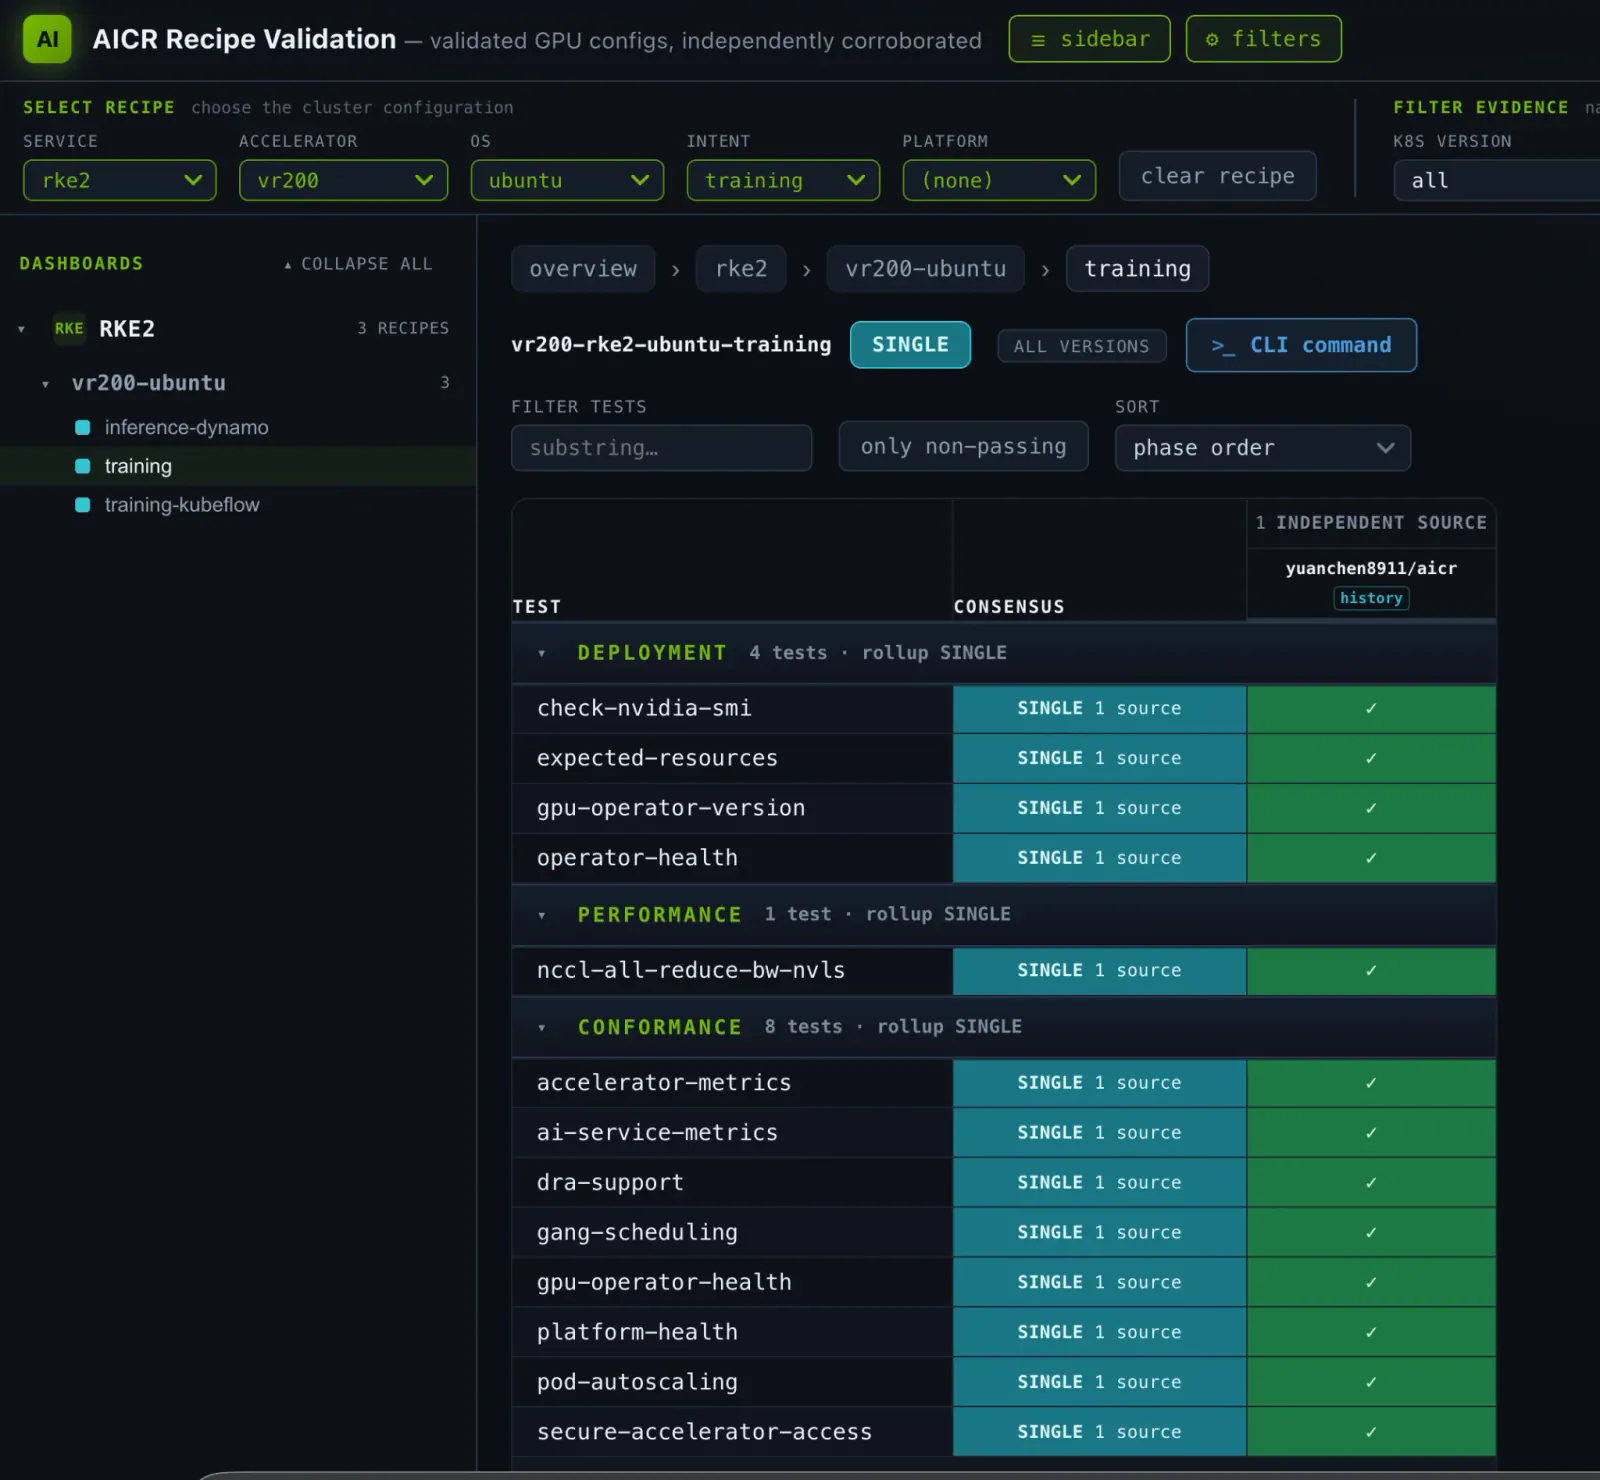
NVIDIA reports end-to-end validation using GPU Operator v26.7.0, DRA driver v0.5.0 and a host-installed R615 driver. Its training and inference variants passed deployment and conformance checks.
The training recipe also passed a cross-node NCCL all-reduce performance gate over the NVLink fabric through an IMEX ComputeDomain. NVIDIA reported 744.71 GB/s of bus bandwidth at a 16 GiB message size. These are vendor results from early hardware, not independently verified measurements. The validation coverage separates that communication result from the unfinished inference benchmark.
The selected runtime components deployed successfully
Conformance
Passed for both variants
The published conformance checks succeeded
Cross-node NCCL all-reduce
Training recipe passed; 744.71 GB/s at 16 GiB
Collective communication over the tested NVLink arrangement
Inference-serving performance
Deferred
No published Rubin serving-performance floor
All-reduce combines data across participating GPUs, making it relevant to distributed training communication. Bus bandwidth is a communication benchmark metric. It is not model throughput, tokens per second or end-to-end training speed.
The 16 GiB test size matters because it defines the reported measurement point. A single result cannot describe every message size or application workload. NVIDIA also provides no like-for-like GB200 result here, so the figure cannot support a Rubin-versus-GB200 speedup claim.
The useful conclusion is narrower: NVIDIA demonstrated that the selected stack could run its cross-node collective test and meet its performance gate on the tested system.
The DRA Crash Loop Shows Why Versions Matter
Early validation exposed an unmapped Rubin architecture value in go-nvlib. That missing mapping caused the DRA driver’s kubelet plugin to crash-loop. NVIDIA says the fix propagated through the stack and shipped in the official DRA driver v0.5.0 release. Its announcement identifies this as a concrete outcome of testing on early silicon.
The failure illustrates how low-level hardware recognition can block orchestration. A plugin needs its dependencies to understand the architecture before it can operate correctly. Changing a Kubernetes scheduling policy would not repair an architecture value missing from a library.
A separate early-cluster problem kept one compute tray outside the NVLink fabric. NVIDIA attributed that problem to hardware or fabric, unrelated to GPU Operator or the DRA driver, and said reseating the hardware resolved it. Blockchain.News’ account of the validation records that distinction.
These failures call for different responses: update the software dependency chain for the architecture mapping; investigate the hardware and fabric for the disconnected tray. That distinction is useful when diagnosing a preview platform, where several layers can produce similar workload failures.
How to Approach the Published Workflow
The Vera Rubin recipes are published in NVIDIA’s open-source AICR v1.0.0 release. The documented workflow generates a recipe, uses its bundle to configure the cluster, then validates the running environment.
The available evidence names aicr recipe and aicr validate, but does not expose complete command lines for every variant. The safe approach is to use the published recipe instructions for exact flags, especially when choosing the Dynamo inference variant.
For an evaluation, the meaningful stages are:
Select and generate the recipe. Offline generation resolves the platform criteria and emits recipe.yaml with the chosen configuration.
Review management boundaries. Confirm that the host driver, operator-managed toolkit, NIC drivers and IMEX ownership match the intended setup.
Deploy through the supported workflow. AICR produces bundles for existing deployment tools; generation alone does not configure or validate a live cluster.
Run validation against the resulting system. Keep deployment, conformance and workload-performance results separate.
NVIDIA reports that the first combined arm64, Ubuntu 26.04, 64k-page-kernel, RKE2 and Rubin deployment moved from cluster handoff to a healthy runtime in hours. It says a second cluster reproduced the result the next day. BPDATA’s coverage attributes those timings to NVIDIA; they are not a deployment-time guarantee.
I’d preserve the generated recipe and validation output together. NVIDIA treats the published evidence as a historical record for the recipe coordinate captured at that time. Changing a driver, image or operator creates a different combination whose behavior needs checking.
Why Inference Performance Is Still Unresolved
NVIDIA’s inference variants passed deployment and conformance on the same cluster, but serving-performance validation remains deferred. The missing dependency is a suitable runtime image built against CUDA 13.4 or later and verified on Rubin hardware.
According to the published account of NVIDIA’s limitation, current public vLLM and ai-dynamo images do not yet meet that requirement in the form needed to establish a Vera Rubin inference-performance floor.
This leaves three distinct questions for adopters:
Can the Kubernetes runtime deploy and pass its checks? NVIDIA reports yes for the tested configuration.
Can the fabric sustain the published collective test? NVIDIA reports a passing training-recipe result.
What serving performance can a model runtime deliver? This preview leaves that unanswered.
That separation is the most consequential detail in the release. An inference recipe can help teams prepare infrastructure before the serving image and its performance validation are ready. It cannot supply the missing model-serving measurements.
For migration planning, I’d use this preview to work through configuration changes and evaluate cluster behavior. Production inference sizing still needs the verified runtime image and serving results that NVIDIA has explicitly deferred.
Frequently Asked Questions
3 questions
1
Does AICR Replace Existing Deployment Tools?
No. NVIDIA describes AICR as generating bundles for existing deployment tools and validating the running cluster.
2
Are Rubin MIG Partitions Covered?
No. The recipes allocate whole GPUs. Although R615.23 advertises Rubin MIG profiles, NVIDIA excludes MIG from this validation.
3
Does 744.71 GB/s Measure Inference Throughput?
No. It is NVIDIA’s reported NCCL all-reduce bus-bandwidth result at a 16 GiB message size. Inference-serving performance remains deferred.