
Apple is giving local AI users a major hardware upgrade. The company’s new M6 chip brings substantially faster large language model processing to the Mac mini, while M5 Ultra raises the workstation ceiling with up to 512GB of unified memory and 1.2TB/s of bandwidth.
The most important specification, however, is not the Neural Engine or CPU core count. It is memory. The regular M6 remains capped at 32GB, making it an excellent platform for smaller models but a poor fit for the quantized 70B-class models serious local AI users may want to run. Apple’s 64GB M5 Pro Mac mini occupies that increasingly important middle ground.
Apple Splits Local AI Across Three Performance Tiers
Apple’s August 25 announcements establish three practical levels of desktop AI hardware: the mainstream M6 Mac mini, the larger-model M5 Pro Mac mini, and the Mac Studio workstation tier. The latter includes M5 Max as an intermediate option and M5 Ultra at the top.
| Local AI tier | Chip | Maximum unified memory | Memory bandwidth |
|---|---|---|---|
| Small and mid-sized models | M6 | 32GB | Up to 170GB/s |
| Quantized 70B-class models | M5 Pro | 64GB | 307GB/s |
| Larger workstation models | M5 Max | 128GB | Up to 614GB/s |
| Frontier-class local models | M5 Ultra | 512GB | 1.2TB/s |
This progression matters because Apple’s unified memory can be accessed by the CPU and GPU without maintaining separate system RAM and graphics-memory pools. More of the installed memory can therefore hold model weights, caches, and runtime data, although macOS and other applications still consume part of it.
M6 Makes the Small Mac Mini Much Faster for AI
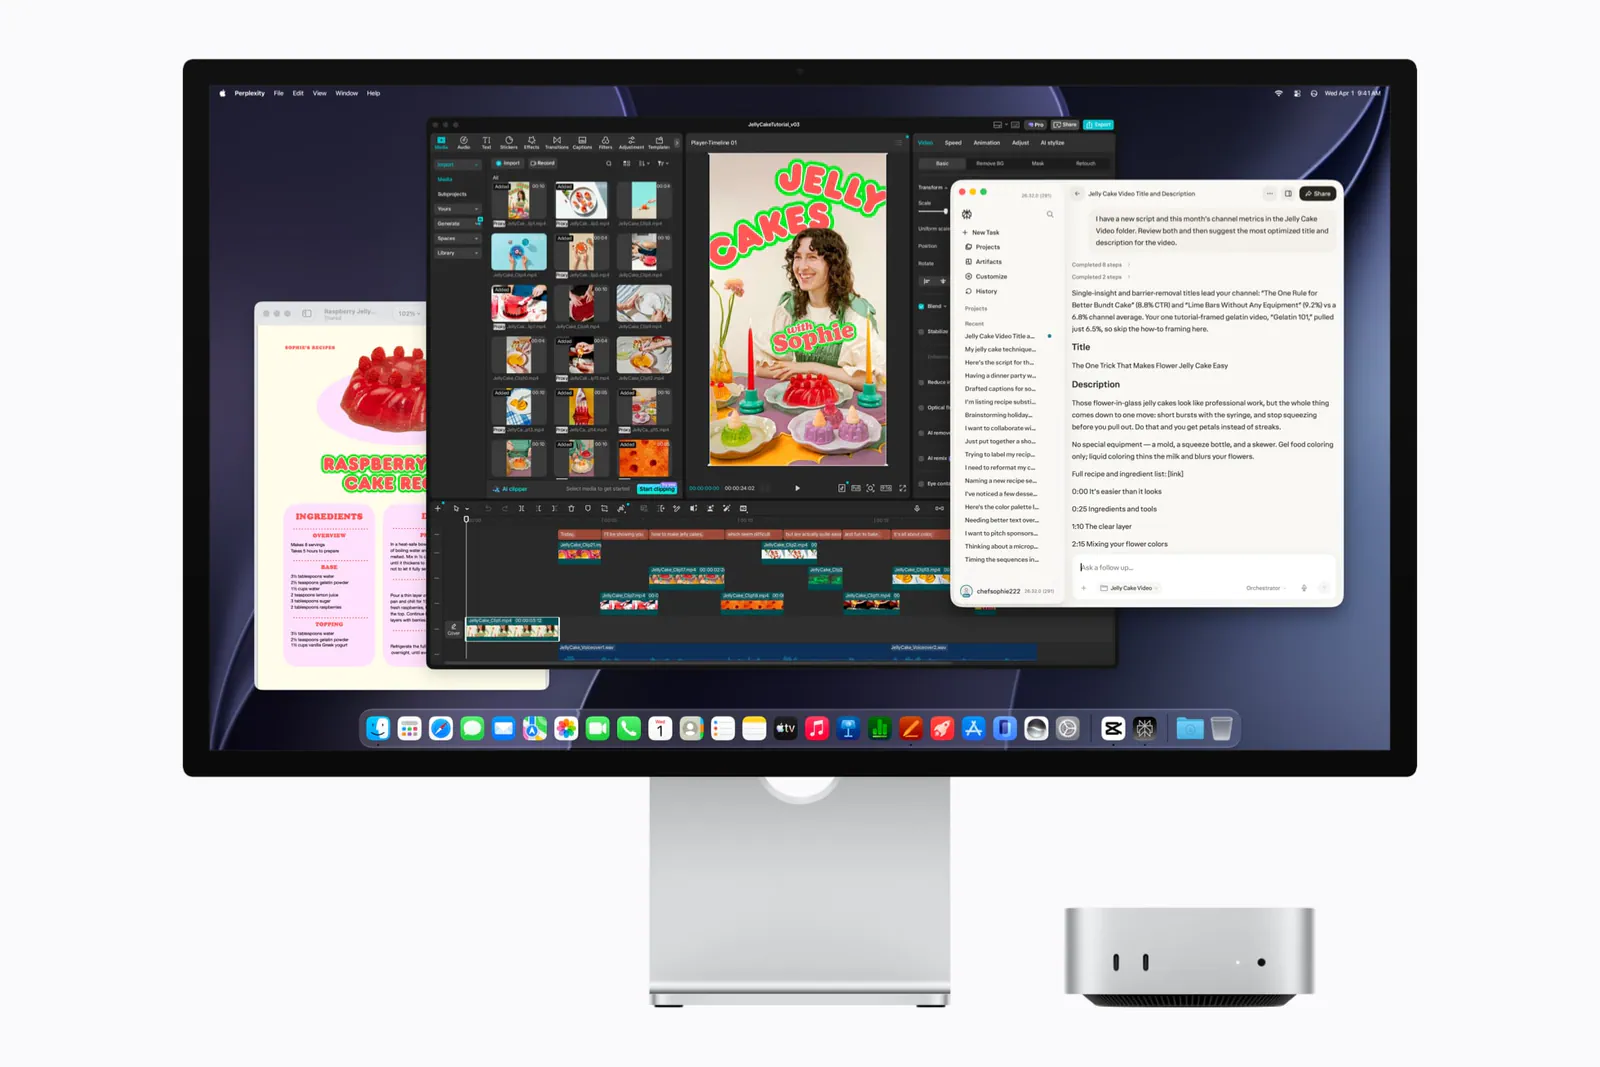
The Apple M6 is the company’s first chip manufactured on a 2-nanometer process. It combines a 12-core CPU, a 12-core GPU with a Neural Accelerator in every GPU core, and two 16-core Neural Engines that supported applications can use simultaneously.
Apple says the new M6 Mac mini delivers up to 4.8 times faster LLM prompt processing than M4 in LM Studio. Its GPU offers nearly 30 percent more peak AI compute than M5, while the Dual 16-core Neural Engine provides up to twice the peak compute of previous generations.
Memory bandwidth rises from the M4 Mac mini’s 120GB/s to as much as 170GB/s, an increase of roughly 42 percent. There is a configuration detail worth noting: Apple’s M6 technical specifications list 153GB/s for the 16GB variants, with the headline 170GB/s available on higher-memory configurations.
For local AI buyers, the sensible M6 configuration is therefore 32GB. The 16GB entry model can run compact models, embeddings, transcription systems, and image tools, but memory pressure will arrive quickly once an LLM, a long context, and ordinary desktop applications are loaded together.
Unified Memory Still Determines Which Models Fit
Quantization reduces model weights from formats such as 16-bit floating point to lower-precision representations. Apple’s MLX LM tools support several quantization methods, including common 4-bit configurations.
At exactly four bits per parameter, the raw weight requirements are approximately:
- 7B model: 3.5GB
- 14B model: 7GB
- 30B model: 15GB
- 70B model: 35GB
Those figures exclude quantization metadata, the key-value cache, temporary buffers, the operating system, and any other open applications. Context length can substantially increase memory use, particularly during long conversations or document processing.
That makes a 32GB M6 an excellent match for 7B to 14B models. Quantized models around 30B should also be usable, although available context and multitasking headroom will depend on the model architecture and runtime. A 70B model does not make practical sense because its quantized weights alone can exceed the machine’s total memory.
By comparison, a 64GB system has enough room for the roughly 35GB of raw weights required by a 4-bit model such as Llama 3.1 70B, plus a meaningful amount of runtime overhead. Fit does not guarantee fast generation, but it is the first requirement.
M5 Pro Is the Practical 70B-Class Option
The new M5 Pro Mac mini increases the maximum unified memory to 64GB and nearly doubles M6’s peak bandwidth, reaching 307GB/s. It also offers up to an 18-core CPU and 20-core GPU, with a Neural Accelerator integrated into every GPU core.
Apple reports up to four times faster LLM prompt processing than the previous M4 Pro Mac mini. More importantly, the 64GB memory option gives local AI developers enough capacity to experiment with quantized 70B-class models without moving to Mac Studio pricing.
There are still limits. Large context windows can consume many additional gigabytes, and running multiple models or AI agents concurrently reduces the available headroom. Some 70B quantizations may need shorter contexts or conservative cache settings. Models at higher precision will generally not fit.
Even with those qualifications, M5 Pro looks like the best-value configuration in this launch for committed local AI users. The M6 Mac mini starts at $899, while M5 Pro starts at $1,699. The final price of a 64GB configuration will be higher, but it remains well below an M5 Ultra workstation.
M5 Ultra Moves Local AI Into Workstation Territory
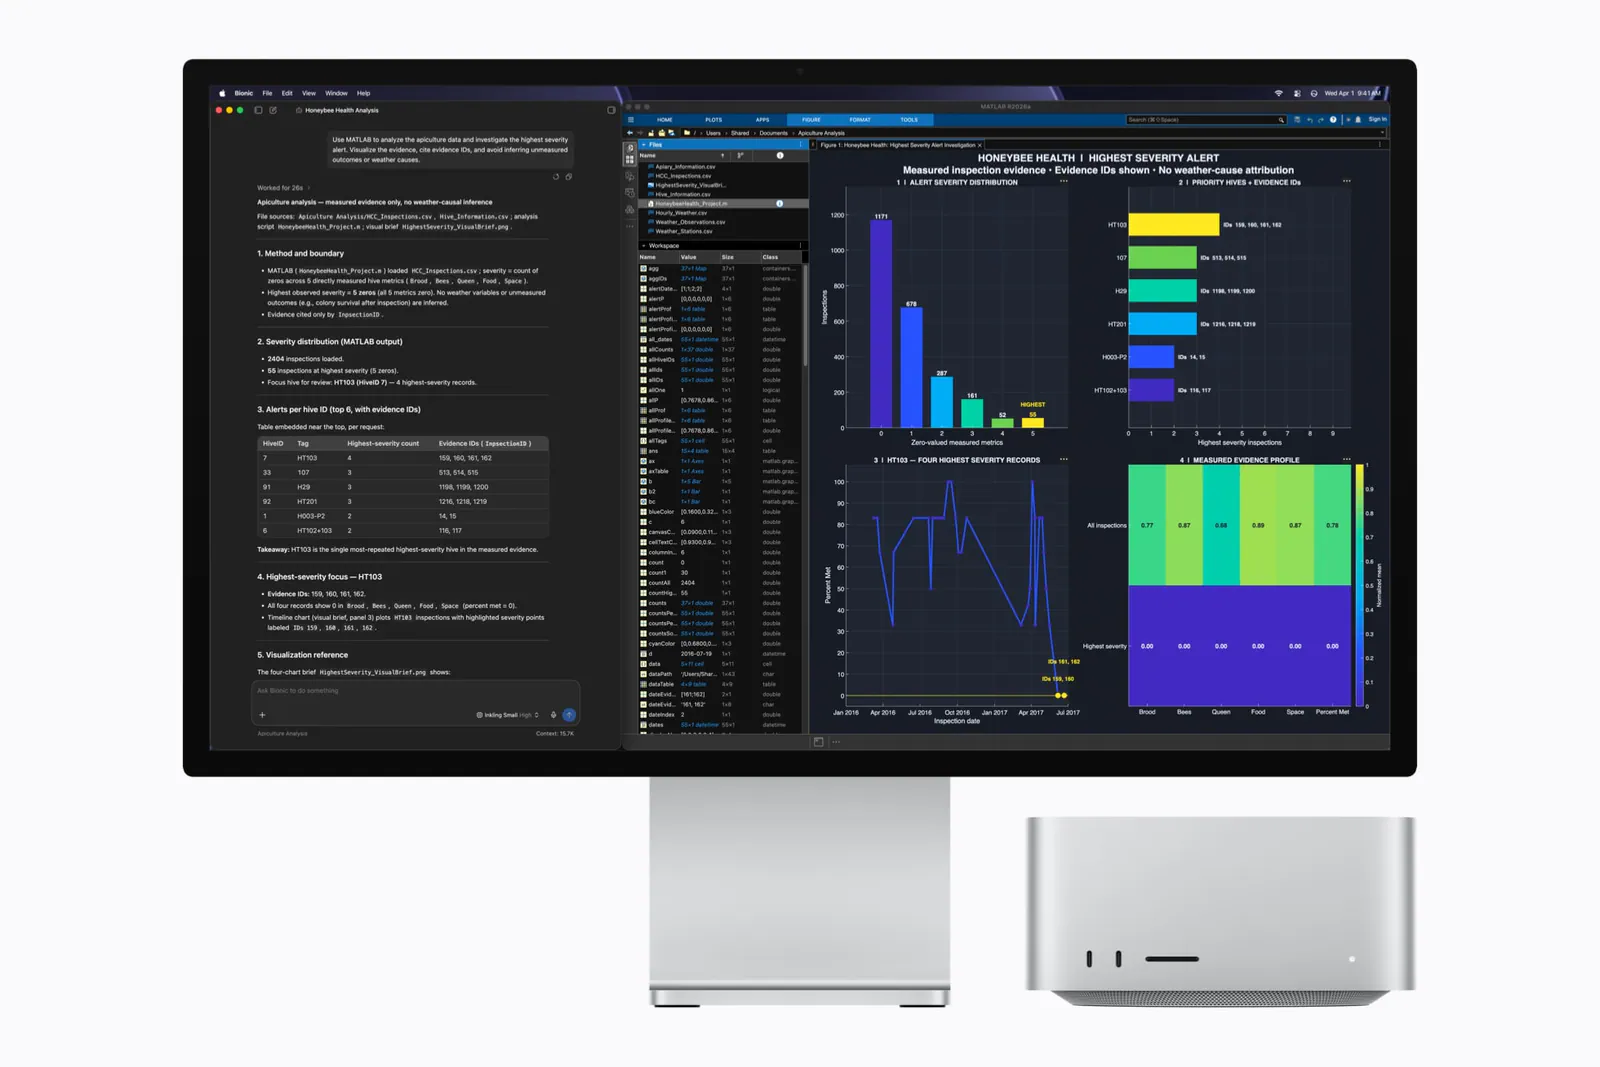
M5 Ultra is a different category of hardware. Apple uses its UltraFusion interconnect to combine two dual-die M5 Max packages, producing the company’s first quad-die system-on-a-chip. The result scales to a 36-core CPU, 80-core GPU, 32-core Neural Engine, and 1.2TB/s of unified-memory bandwidth.
The new M5 Ultra Mac Studio starts with 96GB of memory and can be configured with 256GB or 512GB. Apple says the higher-capacity systems can run LLMs containing hundreds of billions of parameters entirely on-device.
That capacity changes the workload. M5 Ultra is suitable for large-model inference, extensive context windows, local fine-tuning, AI-assisted scientific computing, and workflows involving several models. Apple also supports clustering multiple Mac Studio systems through Thunderbolt 5 and remote direct memory access.
Frequently Asked Questions
4 questions
1Can the Apple M6 run a 70B model locally?
The M6 is not a practical choice for 70B-class models because it supports only up to 32GB of unified memory. A 70B model quantized to four bits requires roughly 35GB for its raw weights before accounting for caches, metadata, macOS, and runtime buffers. M6 is better suited to 7B through 14B models and some quantized 30B-class models.


