
Ox Alpha appeared on OpenRouter on August 20, 2026, without a product announcement, technical report, or named developer. The free preview model accepts more than one million tokens of context, processes images and video, and is positioned specifically for coding and long-running AI agents.
The immediate reaction focused on performance. A small community evaluation reportedly placed Ox Alpha ahead of Anthropic’s Claude Fable 5 and OpenAI’s GPT-5.6 Sol on software-engineering tasks. Its anonymous origin then turned an interesting benchmark result into an industry guessing game, with Google and Chinese AI company Z.ai emerging as the most discussed candidates.
The evidence supports a narrower conclusion than the headlines. Ox Alpha appears to be a capable long-context LLM, potentially competitive with frontier coding models under the right agent setup. It has not yet demonstrated a clear, reproducible lead over Fable 5 or GPT-5.6 Sol.
OpenRouter Confirms the Specifications, Not the Developer
The official Ox Alpha listing on OpenRouter describes it as a reasoning model for coding, sustained agentic work, complex reasoning, and production workloads. OpenRouter says an anonymous third-party provider develops and operates the model. The routing platform is not its developer, owner, or infrastructure provider.
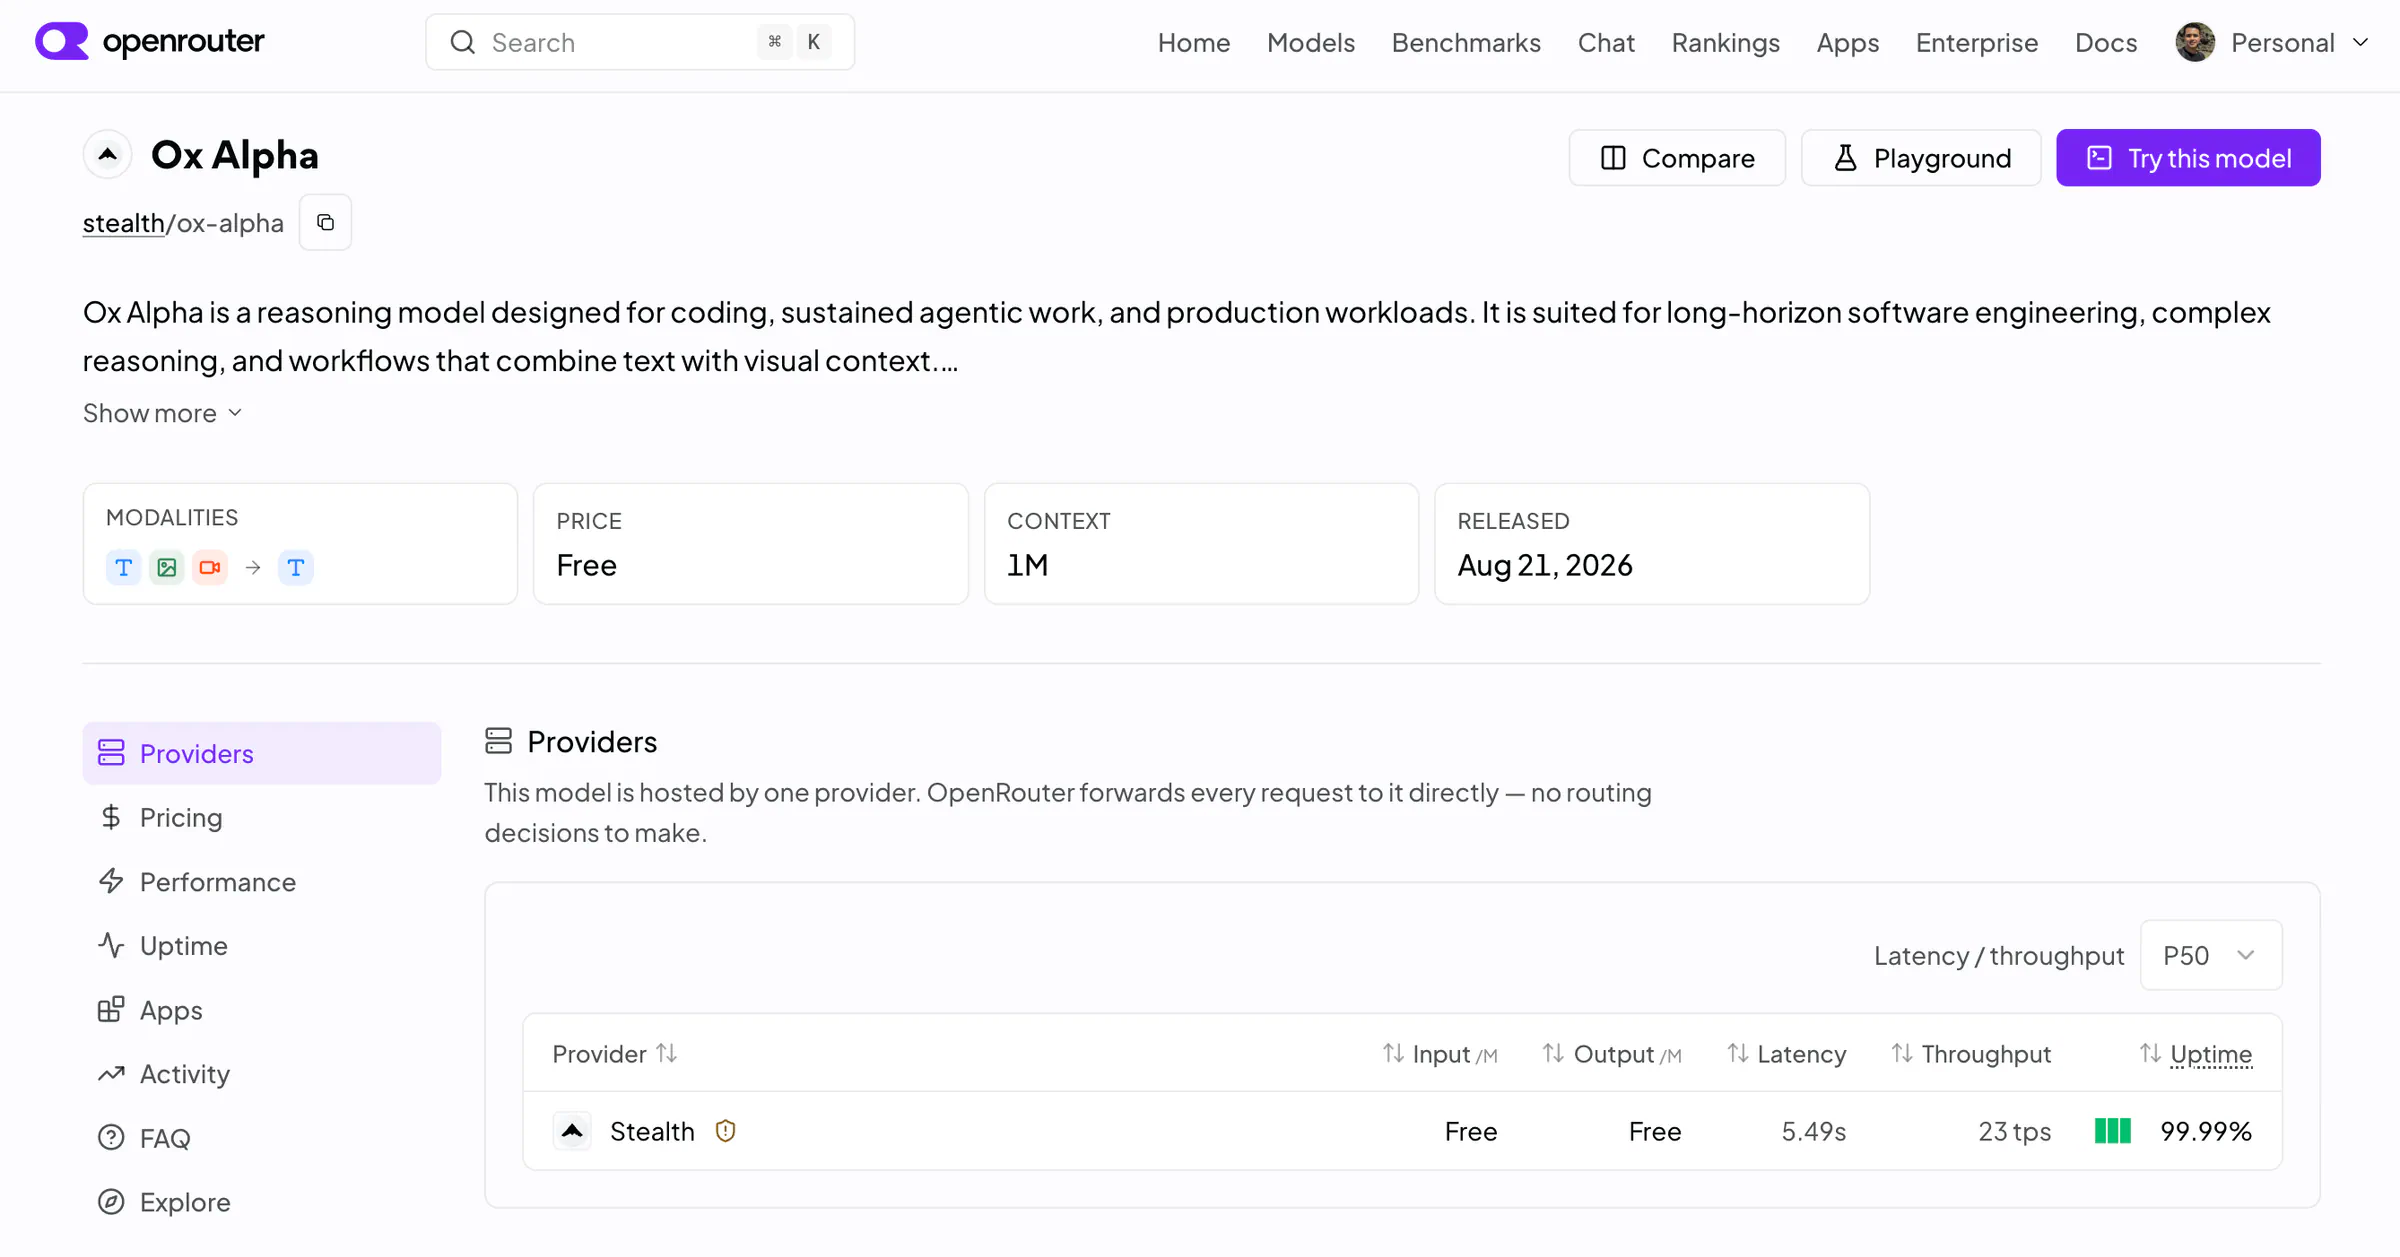
Its published specifications include:
- Context window: 1,048,576 tokens
- Maximum output: 131,072 tokens
- Inputs: Text, images, and video
- Output: Text
- Agent features: Tool calling, tool choice, reasoning controls, and structured JSON output
- Preview price: Free for input and output tokens
OpenCode separately promoted Ox Alpha as free for one week, with near-unlimited use and claimed provider capacity of 100 trillion tokens per day. That capacity figure has not been independently verified, but supporting this level of public experimentation suggests that a well-funded organization is behind the endpoint.
What OpenRouter does not provide is equally important. There is no architecture description, parameter count, training-data summary, safety report, license, permanent pricing, or company name. The model’s page also contains no official benchmark results.
The Coding Victory Came From a Ten-Task Test
The claim amplified by coverage in The Chosun Daily traces back to a community evaluation using ten tasks from DeepSWE. Ox Alpha reportedly completed eight, producing an 80% result. Fable 5 was listed at 65%, while GPT-5.6 Sol reached 52%.
That result is interesting, but it does not establish that Ox Alpha is the best coding LLM.
DeepSWE contains 113 original, long-horizon software-engineering tasks spanning 91 active repositories and five programming languages. Its tasks are written from scratch and graded by programmatic verifiers, reducing the contamination risk associated with benchmarks built from public pull requests. The accompanying DeepSWE research paper also emphasizes that the benchmark evaluates complete coding agents, not just isolated code generation.
A ten-task sample covers less than 9% of the suite. Each additional success changes an eight-out-of-ten result by ten percentage points, making the score highly sensitive to task selection and random variation. Reasoning effort, tool permissions, agent prompts, retry policies, token budgets, and context management can also change the outcome.
More comprehensive tests have been less dramatic. One public 113-task run reported that Ox Alpha solved 66 tasks, or 58.4%. Other community testing has placed it near 63%. Neither run is perfectly comparable with the official leaderboard because evaluation configurations and rollout counts differ, but both weaken the claim that Ox Alpha decisively beats the leading models.
The official DeepSWE leaderboard currently places GPT-5.6 Sol at roughly 73% with maximum reasoning and Claude Fable 5 near 70%. Ox Alpha does not yet have an official leaderboard entry. A separate harness-free LiveCodeBench evaluation produced a 28% Pass@1 result, further illustrating how strongly its apparent performance depends on the task and agent environment.
The defensible reading is that Ox Alpha has produced a promising coding signal. Calling it the new coding champion requires evidence that does not yet exist.
One Million Tokens Could Matter More Than One Benchmark
Ox Alpha’s context window may prove more practically useful than its early benchmark position. A 1,048,576-token limit gives an agent room to process large repositories, documentation, test output, execution history, and architectural instructions within one session.
Capacity alone does not guarantee effective memory. An LLM can accept a million tokens while still overlooking relevant files, losing earlier constraints, or spending too much computation searching through irrelevant material. Developers need retrieval tests, long-context accuracy measurements, and multi-hour agent runs before treating the published limit as a reliable working memory.
The multimodal support creates additional possibilities. Because Ox Alpha accepts images and video, coding agents can inspect interface screenshots, rendering errors, charts, design references, and recorded application behavior alongside source code. Early users have reported promising results when asking it to compare visual output with the code responsible for generating it, although other testers have encountered stalled sessions, repeated errors, and provider failures.
Those mixed reports are normal for a free preview. They also make the “production workloads” positioning premature. Production readiness requires predictable latency, stable availability, support commitments, version control, data-governance documentation, and a clear organization accountable for failures.
The Technical Fingerprints Point More Strongly to Z.ai
The Google theory appears to rest mainly on scale and timing. A provider offering enormous free capacity, multimodal input, and a million-token context window resembles the type of preview Google could operate. Cryptic posts invoking Gemini added fuel to the speculation, but playful social-media replies are not technical evidence of ownership.
The Z.ai theory has more concrete support. Z.ai, also known as Zhipu AI, released GLM-5.3 on August 14, six days before Ox Alpha appeared. GLM-5.3 targets complex coding and long-horizon agents, uses mandatory reasoning with low, high, and maximum effort settings, and supports very long outputs. Those characteristics closely resemble Ox Alpha’s exposed behavior.
Community researchers have also conducted black-box fingerprinting. One tester reported that Ox Alpha’s token counts matched GLM-5.3 across English, German, Chinese, code, and emoji prompts, with a consistent 75-token difference that could represent a hidden system prompt. The tester also observed .
Frequently Asked Questions
5 questions
1What is Ox Alpha?
Ox Alpha is an anonymous reasoning AI model released on OpenRouter on August 20, 2026. It is designed for coding, complex reasoning, and sustained agent workflows. The model accepts text, images, and video, supports tool calling, and is temporarily free. Its developer, architecture, parameter count, training data, permanent price, and long-term availability have not been publicly disclosed.


